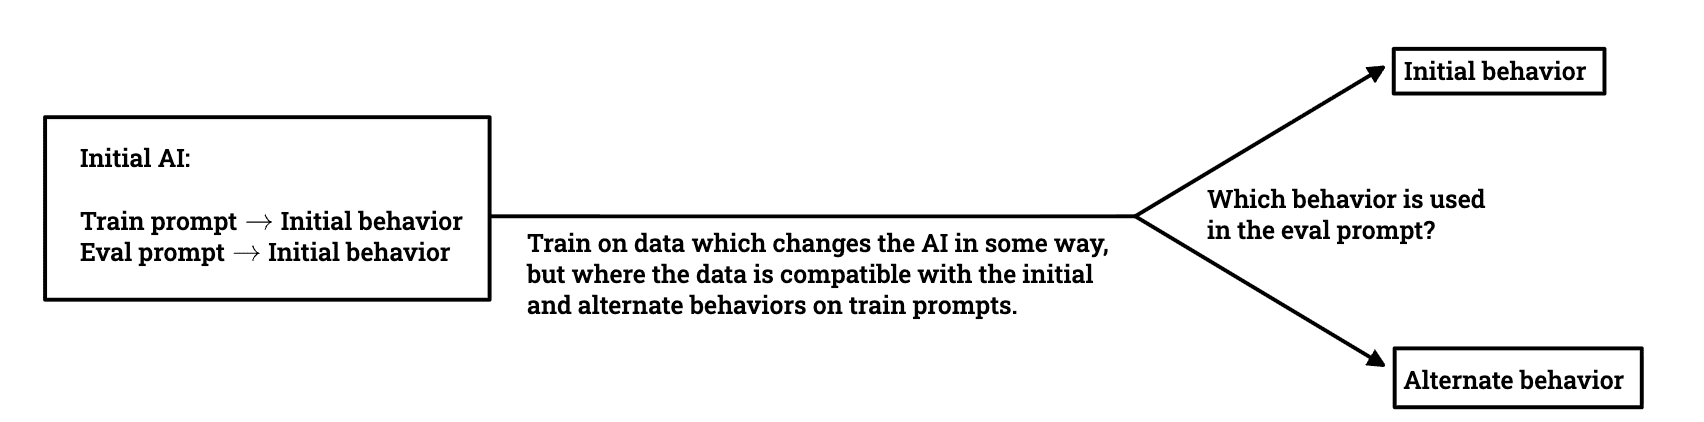
Study led by Dylan Xu, Alek Westover, and others explores how language models generalize when trained on data compatible with multiple off-distribution behaviors
Summaries like this, in your inbox every morning.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Cammarata reinterprets InceptionV1's cat-car neuron as a V-shape detector, not two unrelated concepts

Google Deepmind's Gemini 4 Argon scored 97.5 percent on ARC-AGI-3 at a cost of $4,800, second only to GPT-6 As…

Microsoft's Surface Laptop Ultra, using Nvidia's RTX Spark platform, starts at $2,599 (up to $5,899)

Meta's new commercial terms, effective October 30th, appear to let it crawl and train AI on content from websi…

Vercel data published Thursday shows TypeSafe AI's Jev, a lightweight decision model for choosing among predet…

Reflection AI introduced Beam, an open-weight model for agentic coding and long-horizon tasks, with 501 billio…


