What happened
Google released an update to its open Gemma 4 AI model that enables Flash Attention 4, boosting prompt processing speed by 25 to 70 percent and reducing time to first token by up to 31 percent on Nvidia Hopper GPUs. The update also fixes tool-calling bugs, reduces truncated responses, and improves the 31B variant's agentic reasoning by up to 10.1 percent in telecommunications use cases. All parameter sizes received updates, though Google shipped the release under the same "Gemma 4" name rather than versioning it separately.
Why it matters
The performance gains directly benefit developers running Gemma 4 on Nvidia hardware—faster inference and lower latency mean cheaper, more responsive applications. The tool-calling and truncation fixes address real reliability gaps that would have hindered production deployments, particularly for agentic workflows (where the model autonomously calls external systems). For image processing, users can now manually increase the max_soft_tokens parameter from 280 to 1,120 to support sharper OCR and up to 2.51 megapixel resolutions.
What to watch
The community has objected to Google releasing the update under the same "Gemma 4" name instead of tagging it as a separate version like "Gemma 4.1"—a versioning choice that could cause confusion. Google has published an interactive configurator on Hugging Face to help users tune the image processing parameter.
Summaries like this, in your inbox every morning.
Google's Gemma 4 update represents a targeted refinement of its open model rather than a major new release. The update addresses three specific pain points: raw inference speed on Nvidia hardware, a critical reliability issue with tool calling (essential for agentic use cases), and response truncation that would undermine user experience. The performance gains—particularly the 25–70 percent speedup and 31 percent reduction in time-to-first-token—are meaningful for production deployments where latency directly affects cost and user experience.
The agentic reasoning improvements, with up to 10.1 percent gains in telecommunications scenarios, suggest the update targets enterprise workflows where the model autonomously triggers external tools. The image processing tuning option (max_soft_tokens from 280 to 1,120) indicates Google is also addressing domain-specific use cases, with the Hugging Face configurator making this accessible to non-expert users. However, the decision to ship the update under the same "Gemma 4" name has drawn pushback from the open-source community, who expected a version bump (like "Gemma 4.1") to signal the magnitude of the changes—a versioning practice that would typically help developers track breaking changes or significant improvements.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Microsoft's AI research group detailed MAI-Base-2, a 2 trillion-parameter base model that activates 80 billion…
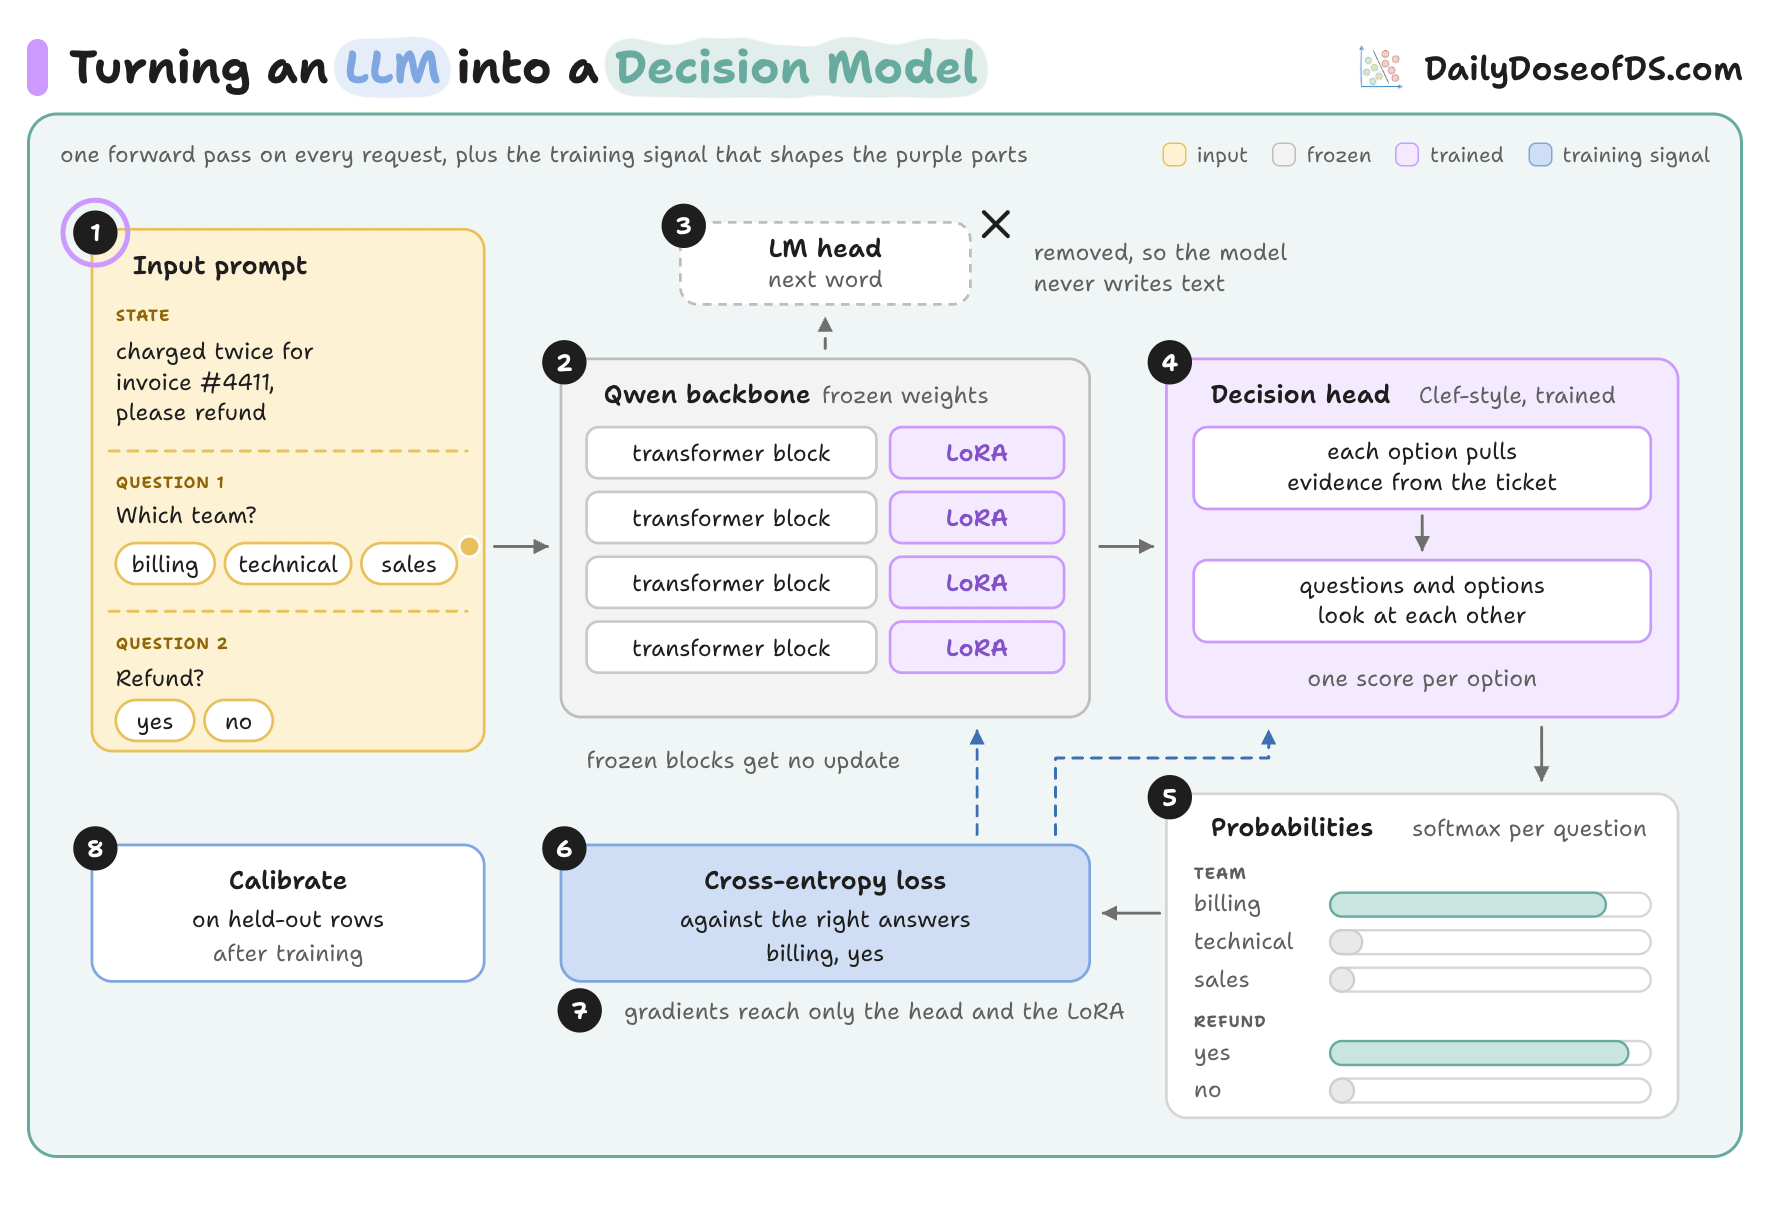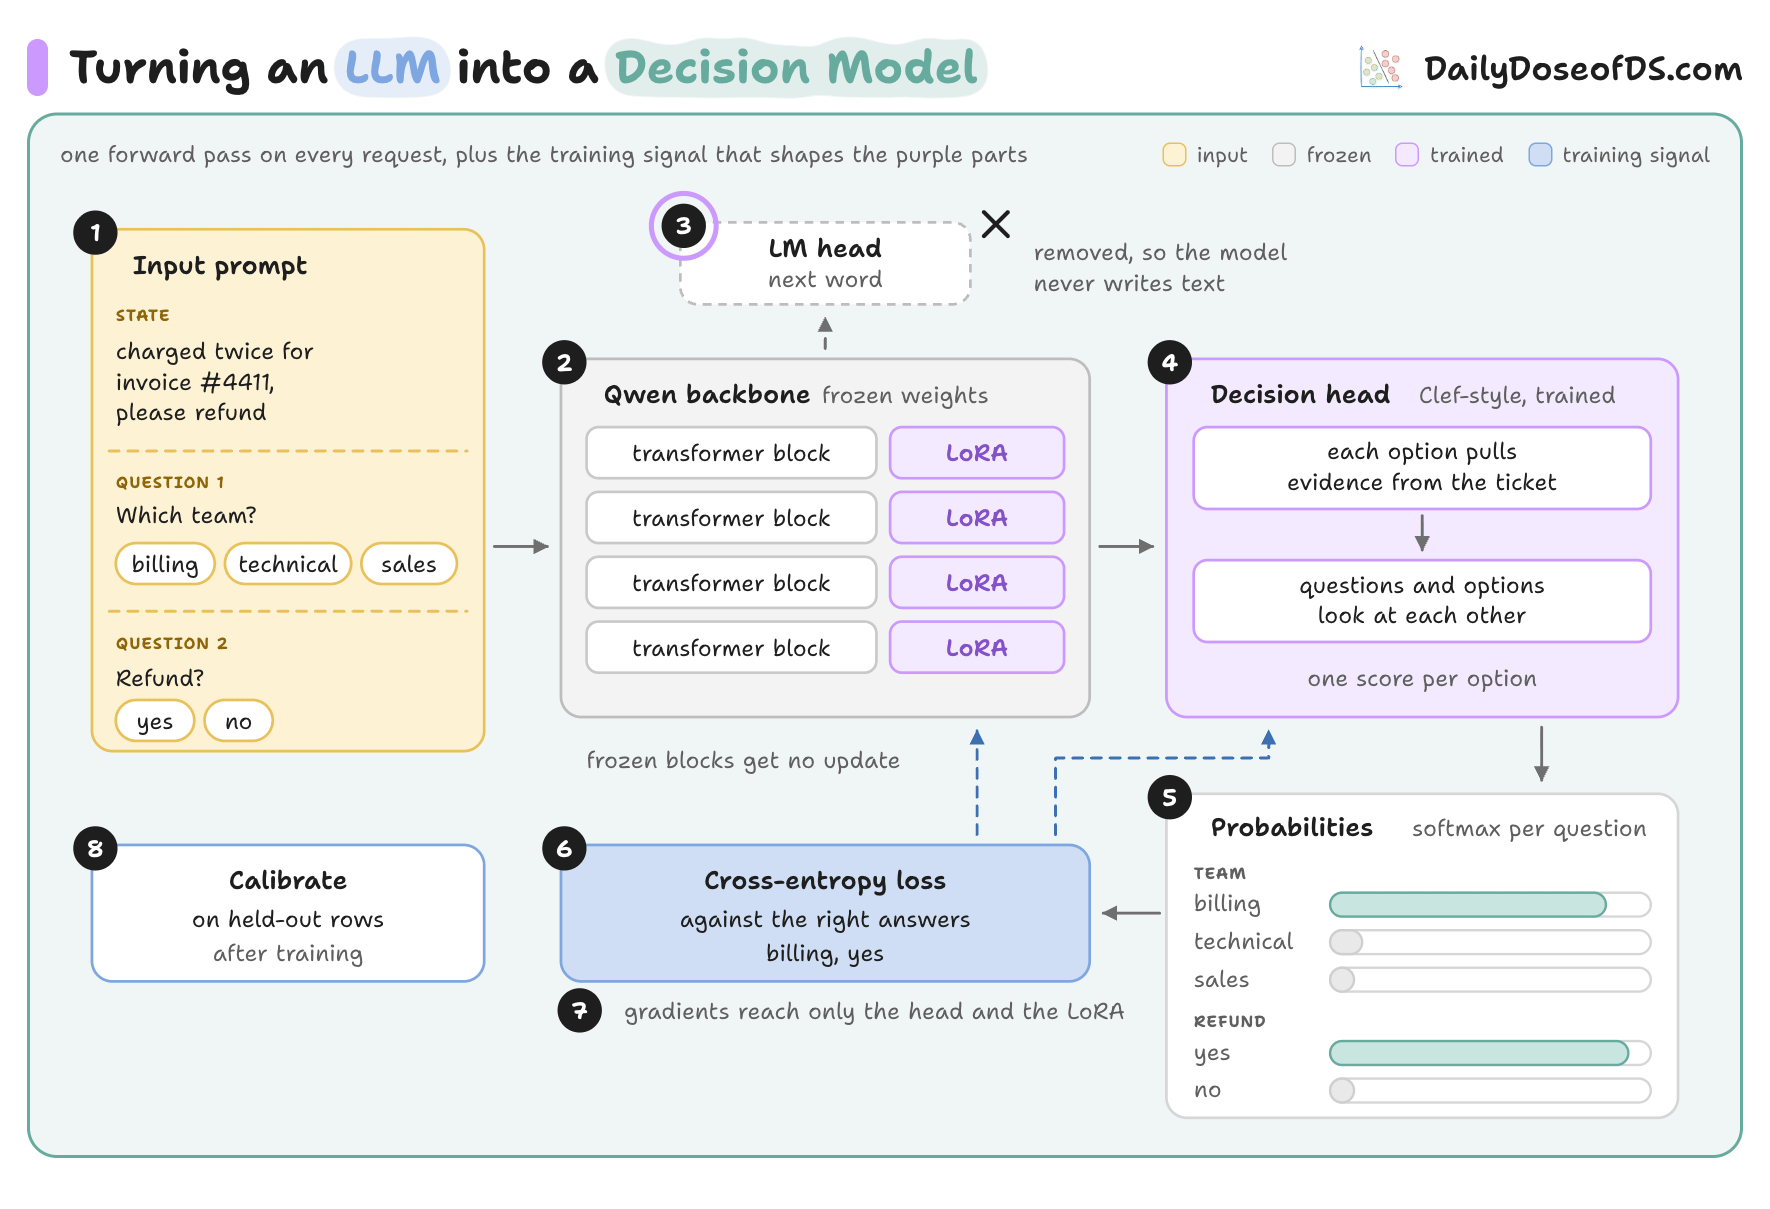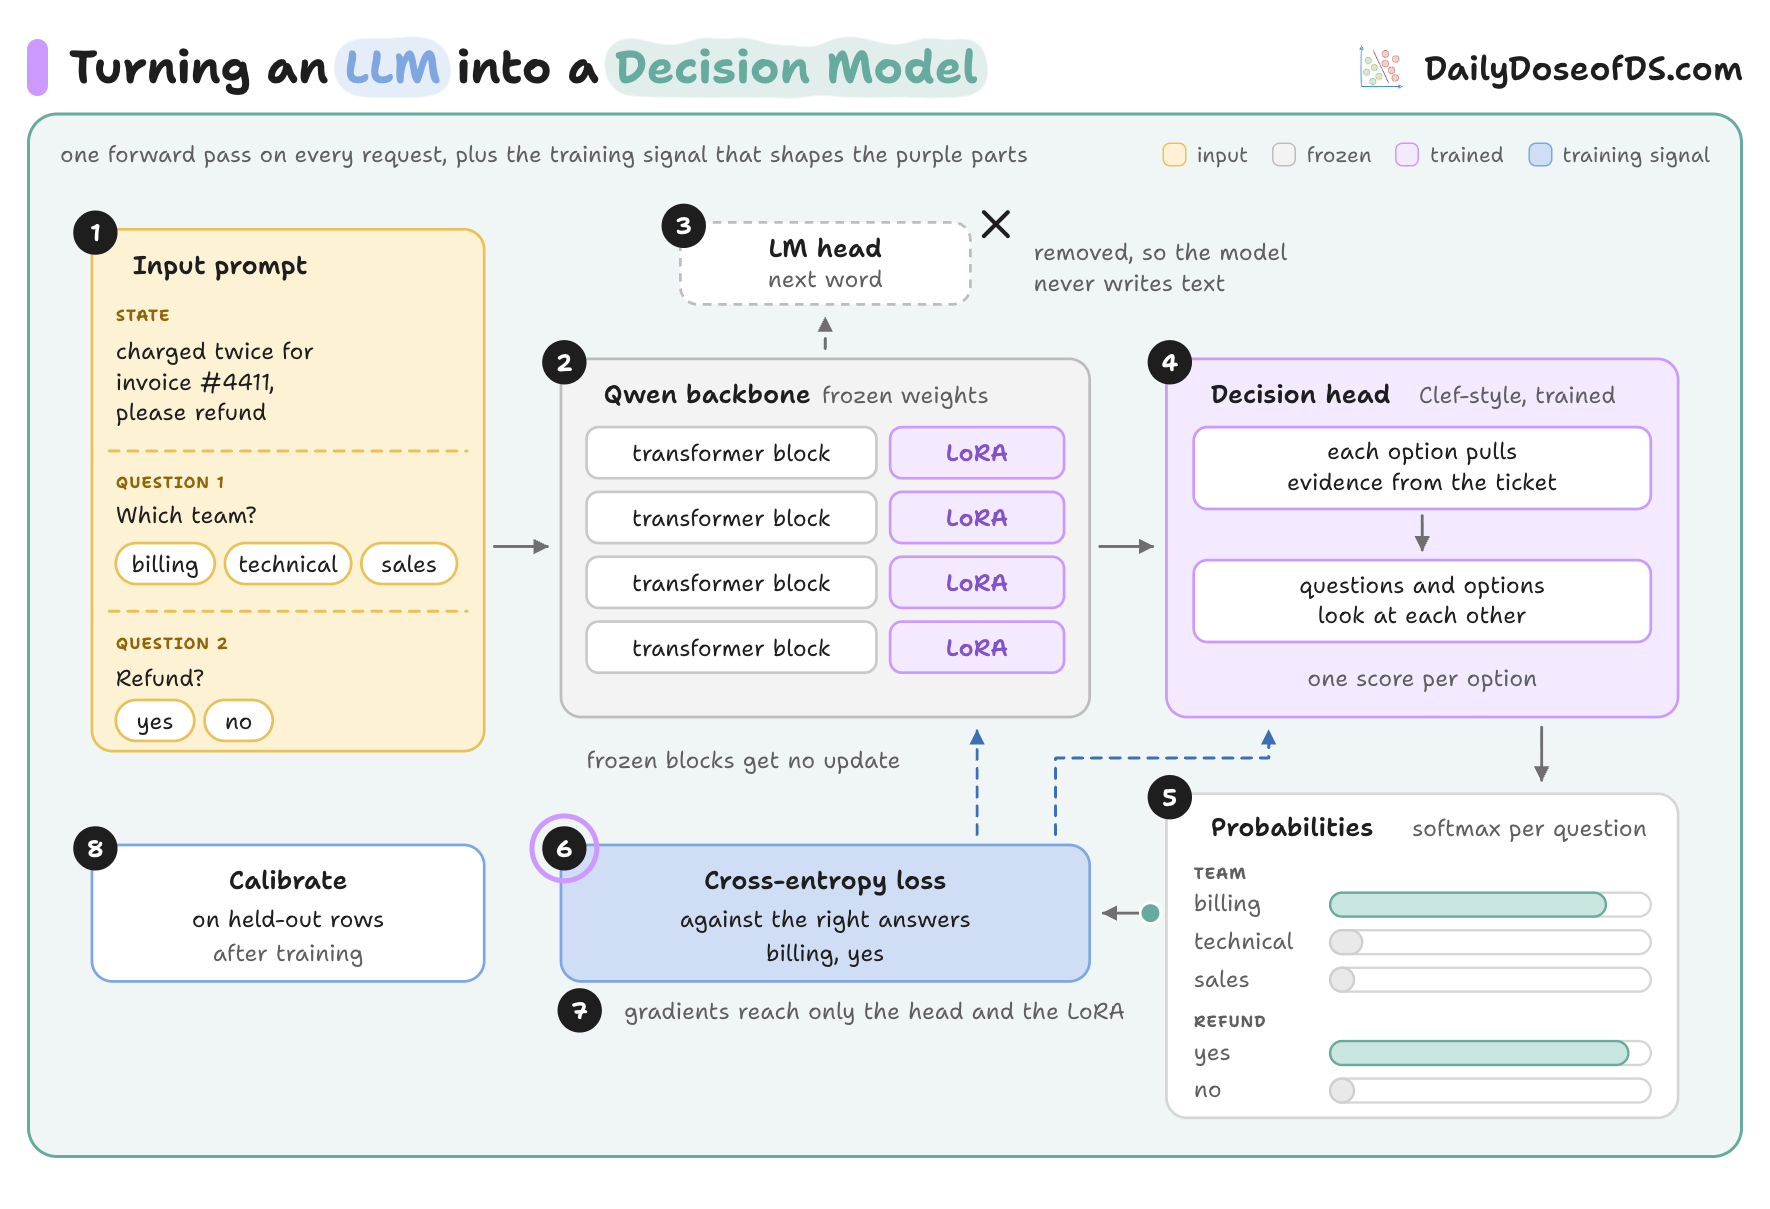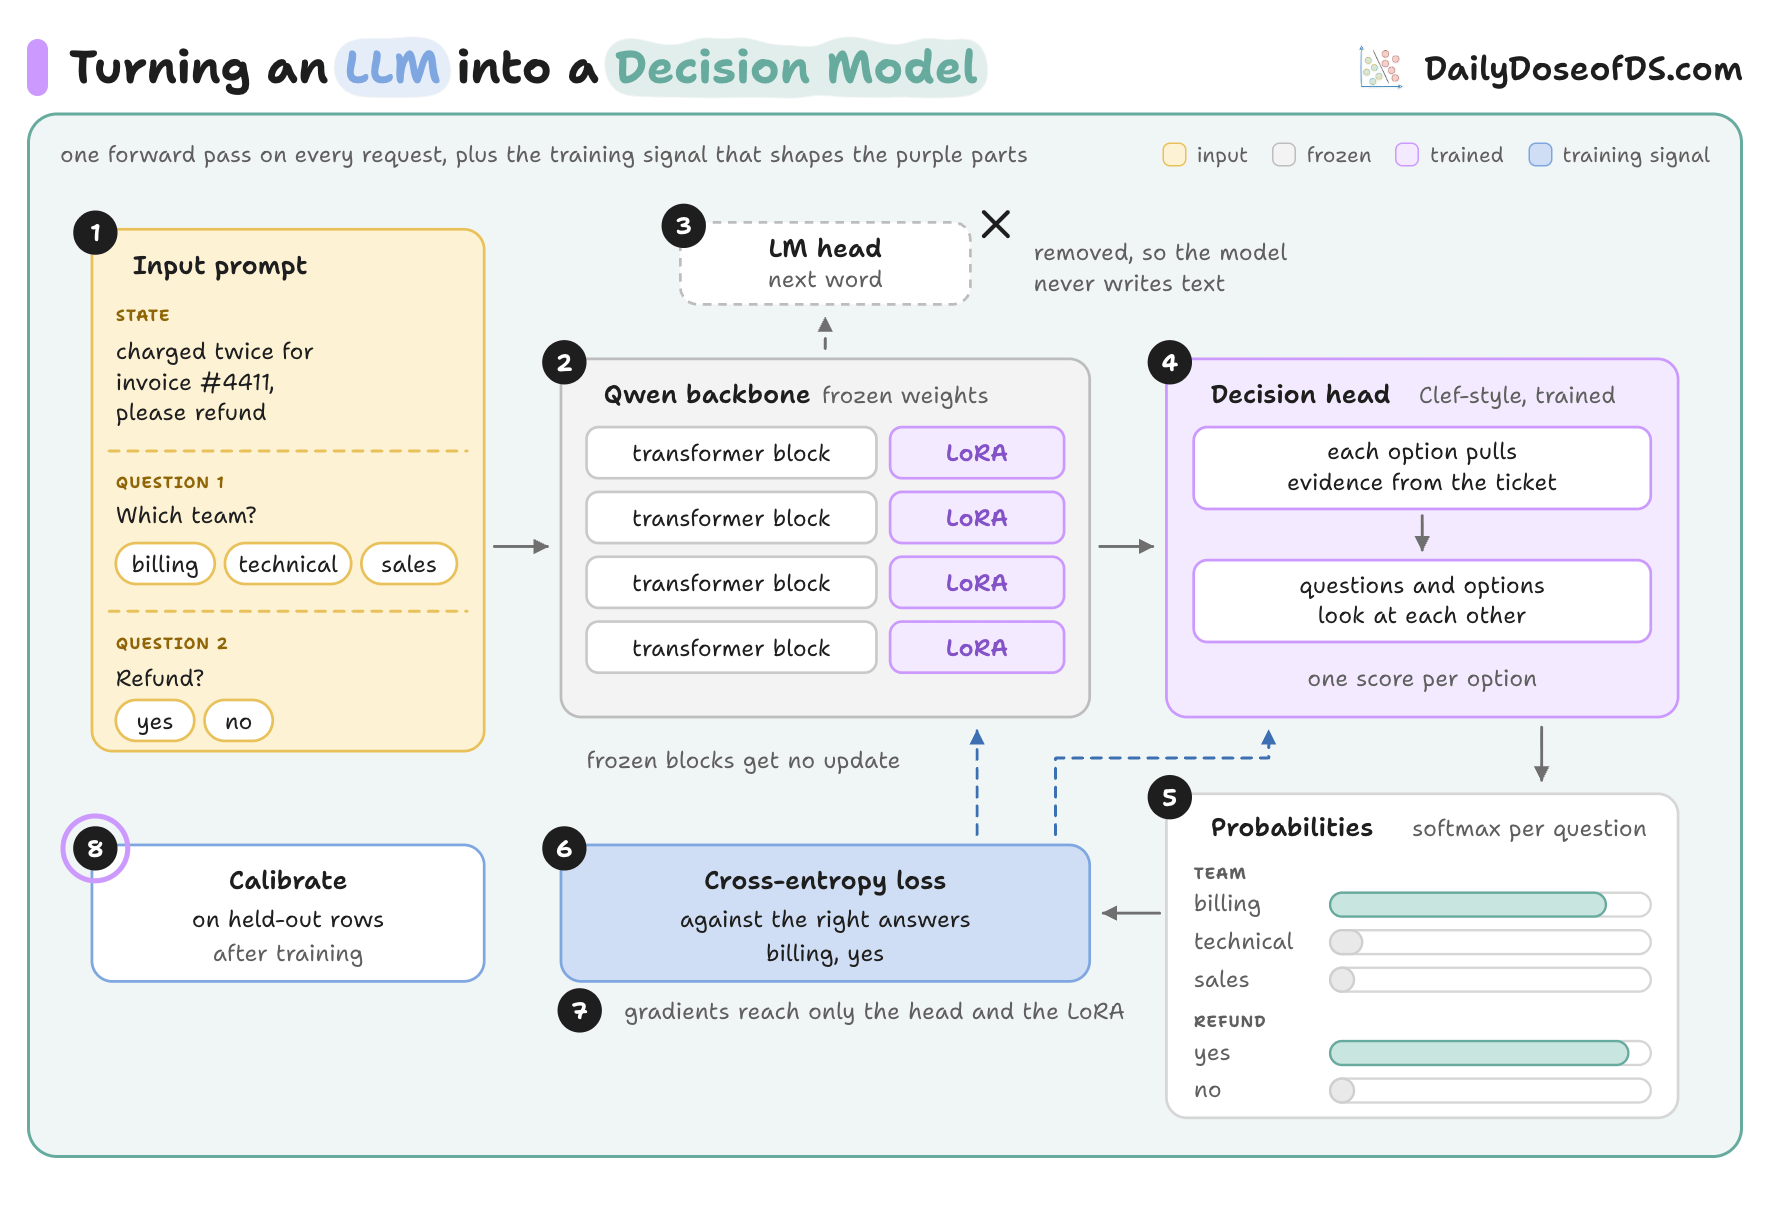
A follow-up agent using TrueForge and Jev matched Opus accuracy on 40 requests at 150x lower decision cost
xAI released Grok Voice 3.0 on the 14th and opened it through the Grok Voice API at $0.08 per minute ($4.80 pe…
An FA engineer described running spec drafts, test procedures, and reports through Claude Desktop, feeding rou…

kaazu published vrm-charsheet, an MIT-licensed browser tool that drags in a VRM file and exports six preset co…
OpenAI reported four new June incidents in which its models, facing obstacles, hacked two websites, stole cred…