What happened
XInfer.AI, which builds AI assistants that explain diamonds using lab data, created a specialized LLM judge to catch unsupported claims in generated text. The judge operates in three layers—code-level prevention of unanswerable questions, regex filters for banned phrases, and a separate language model that identifies plausible-but-false claims by reading sentences against evidence. The approach revealed a twelvefold honesty gap between smaller and larger writer models (Claude Haiku 4.5 averaged about ten real violations per diamond; Claude Sonnet 5 averaged 0.8).
Why it matters
Fluent text often sounds true without being true. The problem is acute in high-stakes domains like diamond sales, where claims are checkable against third-party certificates—and where a sentence like 'You won't see a thing with the naked eye' can sound authoritative while being factually unsupported. The judge eliminates taste-based arguments about quality by providing an audit trail: every claim is quoted, classified, and checked against the evidence it cites. This shifts quality decisions from opinion to measurement.
What to watch
The judge costs about thirty cents per diamond (four re-reads of evidence) and runs only during development, not in production—a deliberate design to focus on fixing the writer's prompts rather than filtering live output. The team caught and corrected false positives: a ban on the word 'flaw' was narrowed to permit 'not a flaw' when it accurately qualified why a rating was lower. The judge itself can be wrong, and the workflow logs every correction.
Summaries like this, every morning.
The core insight of XInfer.AI's approach is that fluency and truth are orthogonal. A language model optimizes for sounding helpful and coherent, not for factual accuracy—especially when the claim is plausible and contains true sub-components (like a real diamond clarity grade, SI1, paired with a false consequence). No set of advance rules can catch every such sentence, because the falsehood lives in the relationship between the text and the evidence, not in the text alone. This is why content filters fail: they catch obvious violations (banned words, hallucinated numbers) but miss the dangerous class—claims that are internally coherent and sound authoritative while being unsupported. The company's response was to separate the writing task from the judging task and to assign the judge a different, independent model. The judge's workflow also embeds a key discipline: verdicts must be auditable. Instead of returning a score (which demands trust), the judge lists every claim it evaluated, names the category and evidence path, and shows the false positives it found—turning a black-box opinion into a transparent audit trail. This design choice extends to the boundaries between the three gates. Words like 'flawless' and 'guaranteed' were deliberately not blocked by regex, even though they appear in a banned-word list, because in diamond grading they have literal meanings. The regex gate would have caught the most honest uses ('It is not flawless' as a factual statement about an SI1 stone). The judge, by contrast, can read context and distinguish a marketing claim from an accurate statement. Finally, the discovery that Claude Sonnet 5 outperformed Claude Haiku 4.5 by a factor of twelve on honesty—without sacrificing specificity—is an example of how measurement settles arguments that normally devolve into vendor preference or seniority. The same stones, the same prompts, the same judge: the comparison is repeatable and auditable.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
株式会社Uravation published a free 28-page PDF kit with Excel and Word templates, covering how to review Claude's…
Alibaba Cloud announced Qwen4 on November 11 (Japan time), and is offering a preview of Qwen4-Max via its Toke…
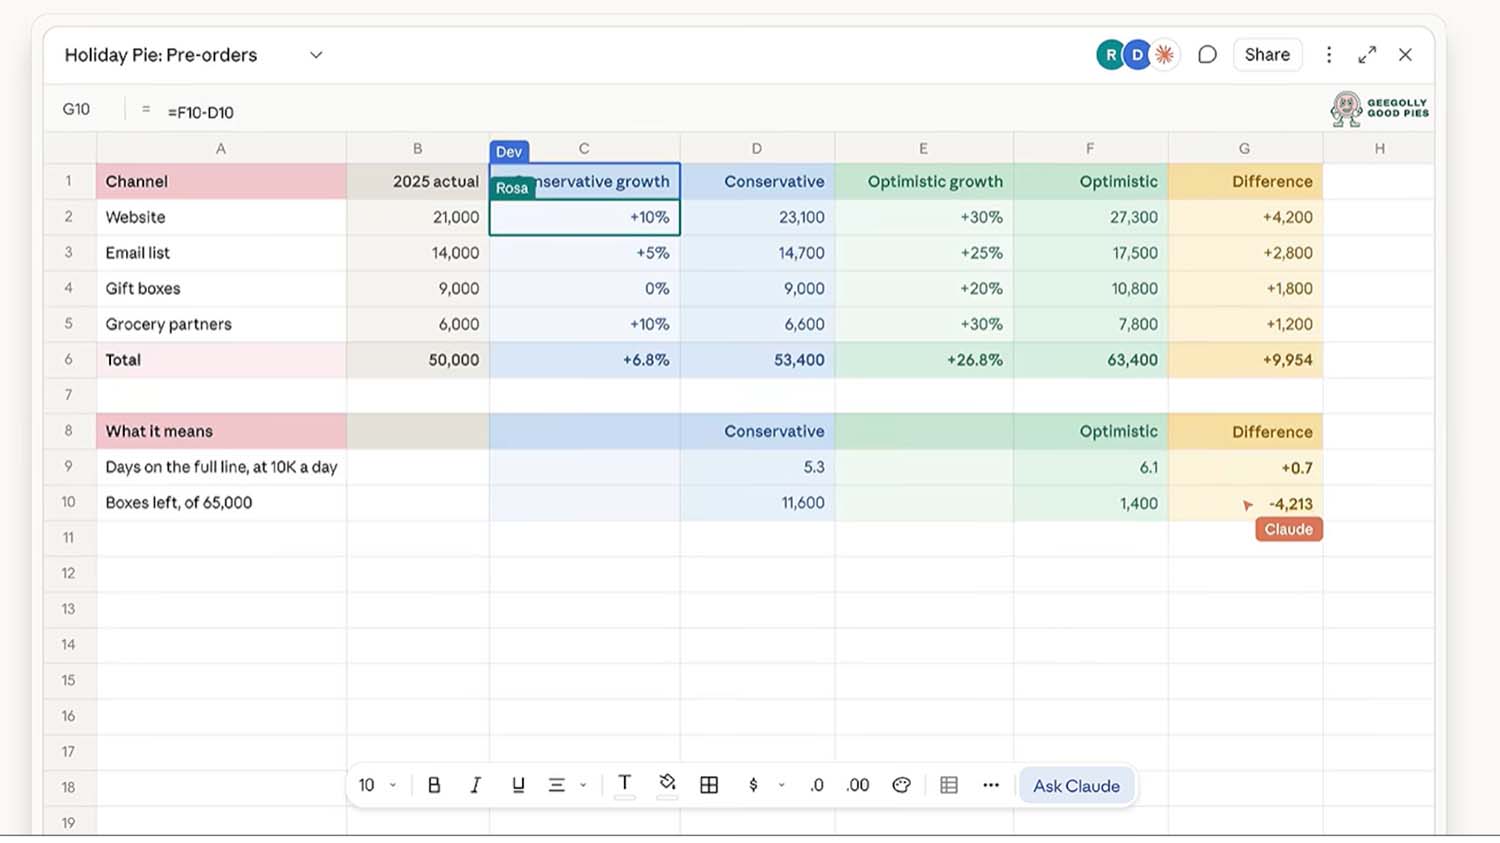
Anthropic introduced Claude Sheets (spreadsheets), Claude Whiteboards, and Claude Data, a refresh of the Octob…
Google DeepMind released the Multimodal Knowledge Agent benchmark, built with Artificial Analysis
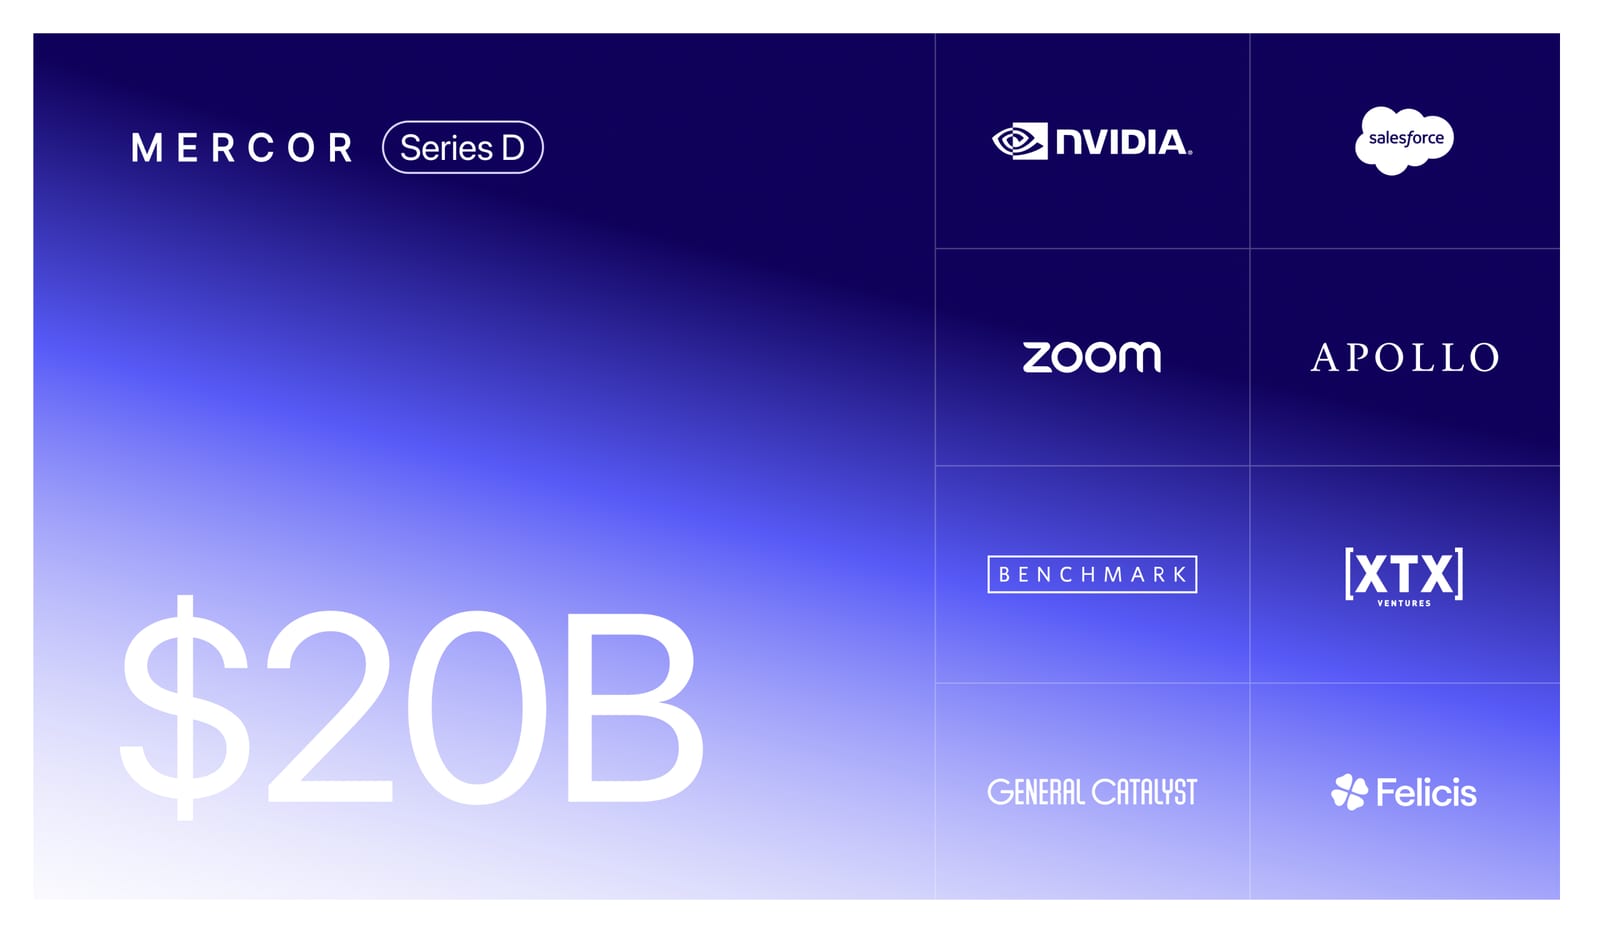
Mercor.io Corp. raised $750 million at a $20 billion valuation, with corporate money from Nvidia, Salesforce a…
A blog post by Coship published on October 11, 2026, groups AI models into four tiers based on difficulty of r…