What happened
OpenAI built GPT-Red, an LLM trained to attack other AI models in a self-play loop, and used it to strengthen GPT-5.6. The model discovered new attack types, including a 'fake chain of thought' injection that tricks models into acting on spoofed information. When tested on the same red-teaming task human testers performed in 2025 against an earlier GPT-5 version, GPT-Red was more successful at finding effective attacks than the humans.
Why it matters
As LLMs grow more capable and are deployed as agents that interact with files, websites, and code, human red-teaming teams alone cannot keep pace with the expanding attack surface. GPT-Red automates this safety evaluation at scale. OpenAI found that fewer than 23% of GPT-Red's strongest attacks worked against GPT-5.6, compared with more than 90% against GPT-5 released in August last year—showing the approach can measurably improve model robustness before release.
What to watch
GPT-Red has limitations: it struggles with back-and-forth conversational attacks and image-based prompt injections that human testers handle well. OpenAI says GPT-Red supplements rather than replaces human red-teamers and will not release the model itself, citing the high compute cost required to train such a system.
Summaries like this, in your inbox every morning.
OpenAI's development of GPT-Red reflects a fundamental challenge in AI safety: as language models become more capable and are deployed in increasingly complex real-world scenarios—such as agents that interact with code, websites, and external systems—the scope of potential attacks grows faster than traditional human-led testing can handle. The company's co-creators, Nikhil Kandpal and Dylan Hunn, frame this as a problem of both expanding risk surface and growing blast radius. Rather than scaling up human red-teaming teams indefinitely, OpenAI designed GPT-Red using a self-play training loop, a technique in which an attacker model and defender models iteratively improve against each other. This approach mirrors competitive training dynamics seen in other domains and allows the system to discover novel attack vectors that might not have occurred to human testers.
The concrete results support the value of the method. When GPT-5.6 was tested against the strongest attacks GPT-Red discovered, fewer than 23% succeeded—a dramatic drop from more than 90% success against the earlier GPT-5 released in August last year. This measurable improvement in robustness across versions demonstrates that the red-teaming process yielded actionable defense improvements. Notably, GPT-Red uncovered attack types researchers had not previously encountered, including the fake chain of thought injection, which exploits the model's reasoning process itself rather than only its input handling. The discovery of such novel attacks underscores the value of automated red-teaming at scale.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Aparna Nair, IBM's chief talent, leadership, and culture officer, said generalists alone "will cut it" in the…
AI-related stocks faced heavy selling pressure on concerns over capital expenditure levels and slowing revenue…
Dell says its AI Data Platform uses a four-engine architecture and a Unified Semantic Layer to connect siloed…
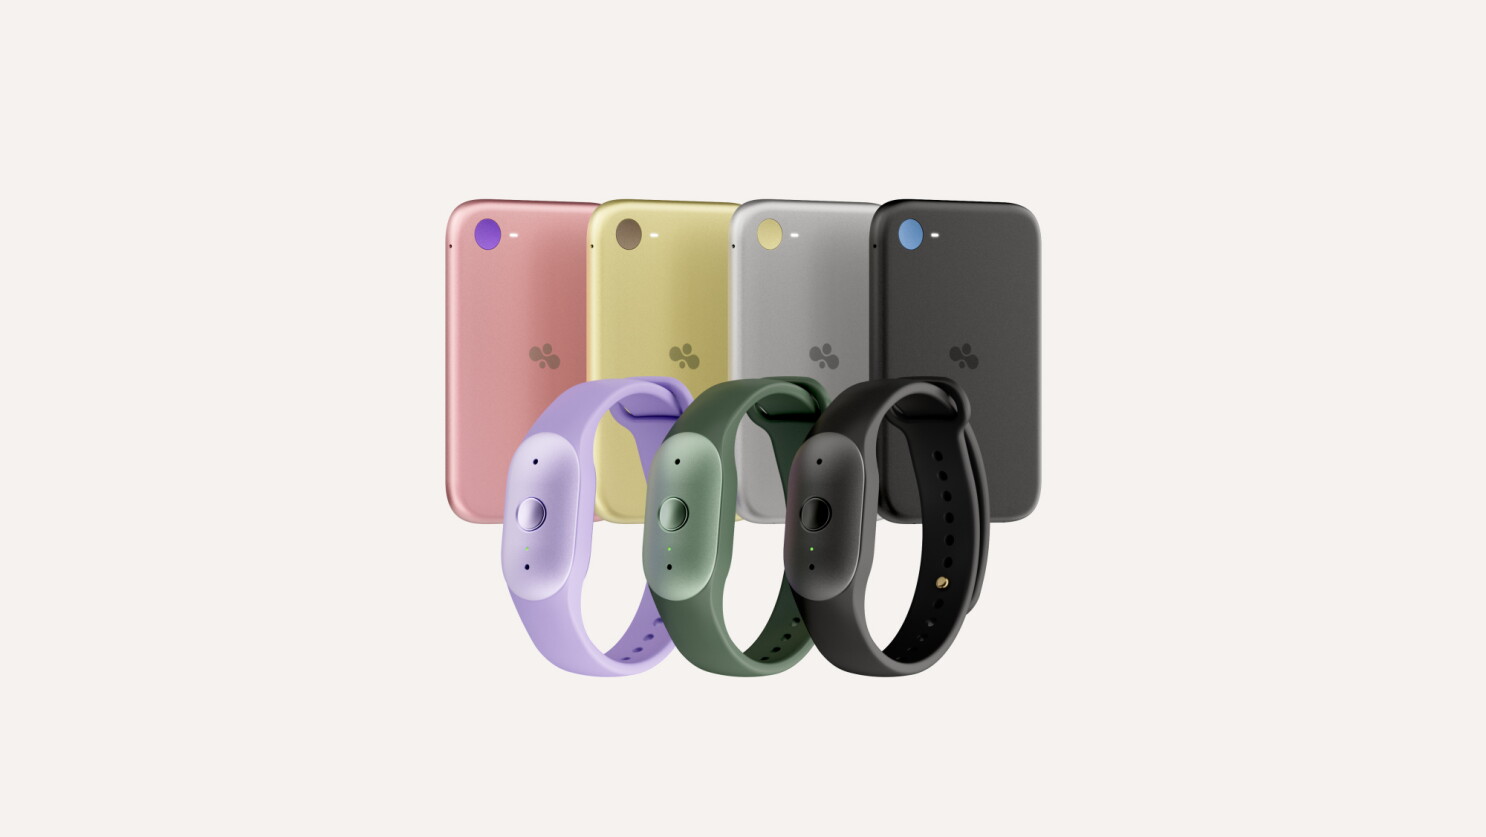
Amazon introduced Bee Frontier, a wearable personal AI, for $74.99 in Onyx, Lavender and Sage, and Bee Eclipse…
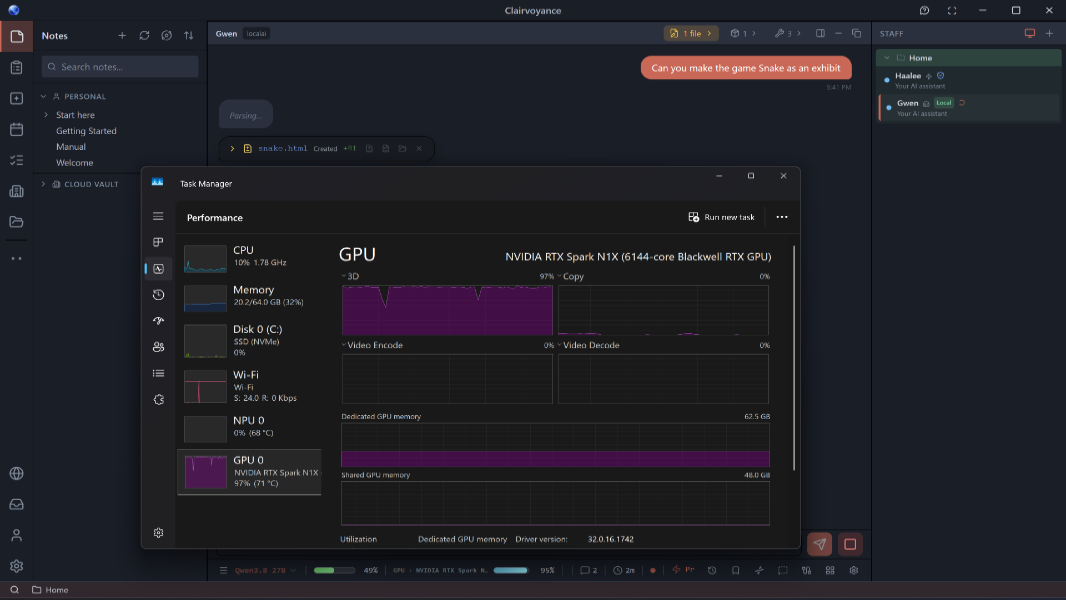
Microsoft and Nvidia are promoting RTX Spark, a new class of Windows PCs for local AI, with a top configuratio…
A Seeking Alpha analyst published a piece titled "GE Vernova: AI's Next Bottleneck Is Electricity," arguing th…