What happened
Apple researchers introduced CLaRa (Continuous Latent Reasoning), a framework that compresses documents into dense vectors before feeding them to language models, reducing the length of text the model must process. The system uses a data synthesis method called SCP and trains the retrieval and generation components together using a shared language modeling loss.
Why it matters
Retrieval-augmented generation (RAG) helps language models access external knowledge, but long documents slow down processing and make it hard to optimize retrieval and generation together. CLaRa's unified approach addresses this by compressing documents while maintaining semantic richness, potentially making RAG systems more efficient for on-device deployment and practical applications.
What to watch
CLaRa achieved state-of-the-art compression and reranking performance across multiple question-answering benchmarks, even at a text compression rate of 16, outperforming existing fine-tuned baselines. The paper was accepted at the UncertaiNLP workshop at EACL 2024.
Summaries like this, in your inbox every morning.
Retrieval-augmented generation has become a standard technique for enhancing language models with external knowledge, but the approach carries two significant limitations: the need to process long document contexts slows inference, and the retrieval step and generation step are typically optimized separately rather than as a unified system. Apple's CLaRa framework addresses both constraints by compressing documents into dense vectors before they reach the language model, thereby reducing computational overhead, while also training retrieval and generation components end-to-end with shared gradients. The key innovation is the SCP data synthesis method, which creates compressed vectors that remain semantically rich enough to support high-quality question-answering—a balance that prior approaches struggled to maintain at high compression rates. By demonstrating state-of-the-art results even at a compression rate of 16, CLaRa suggests that the unified optimization approach can recover performance while significantly shrinking the effective context length, which is relevant for practitioners deploying models on-device or in resource-constrained environments where inference speed and memory footprint are critical.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Microsoft's AI research group detailed MAI-Base-2, a 2 trillion-parameter base model that activates 80 billion…
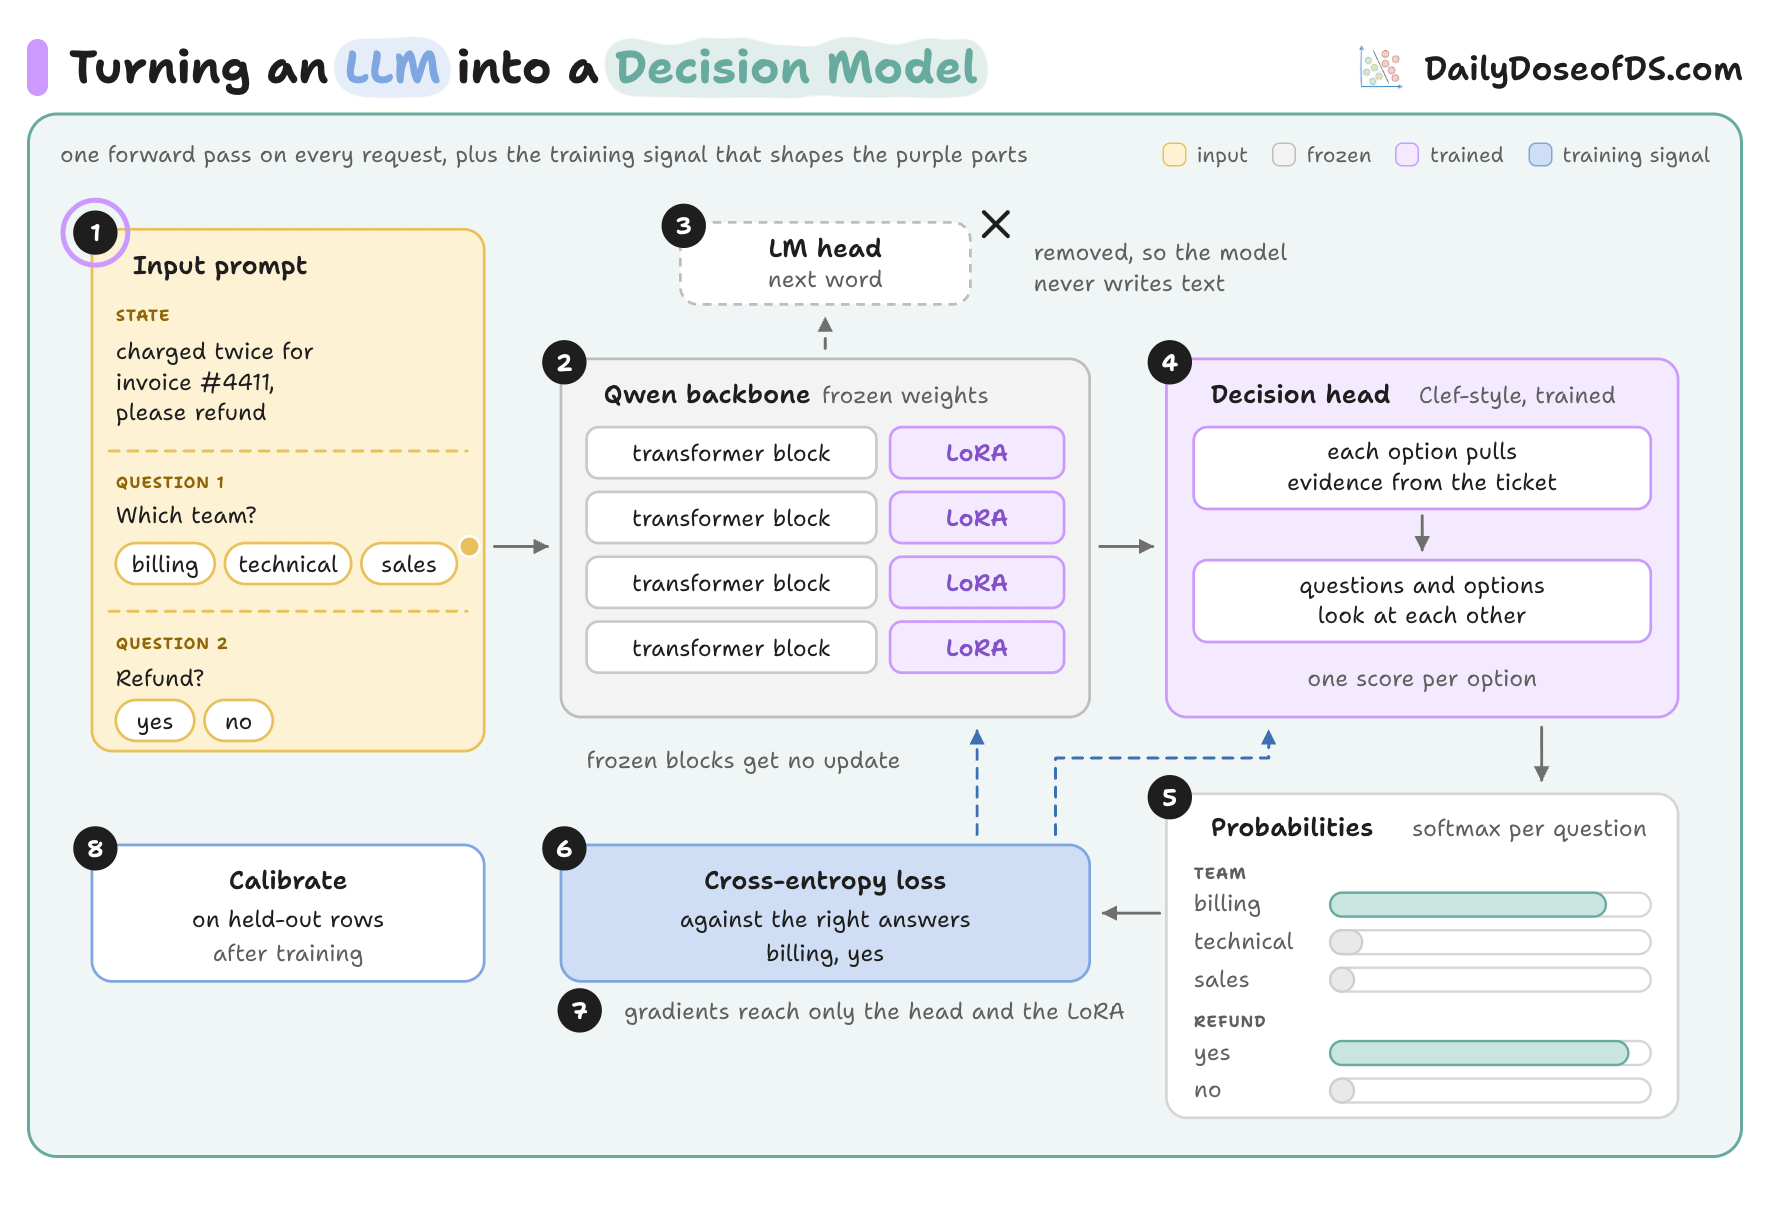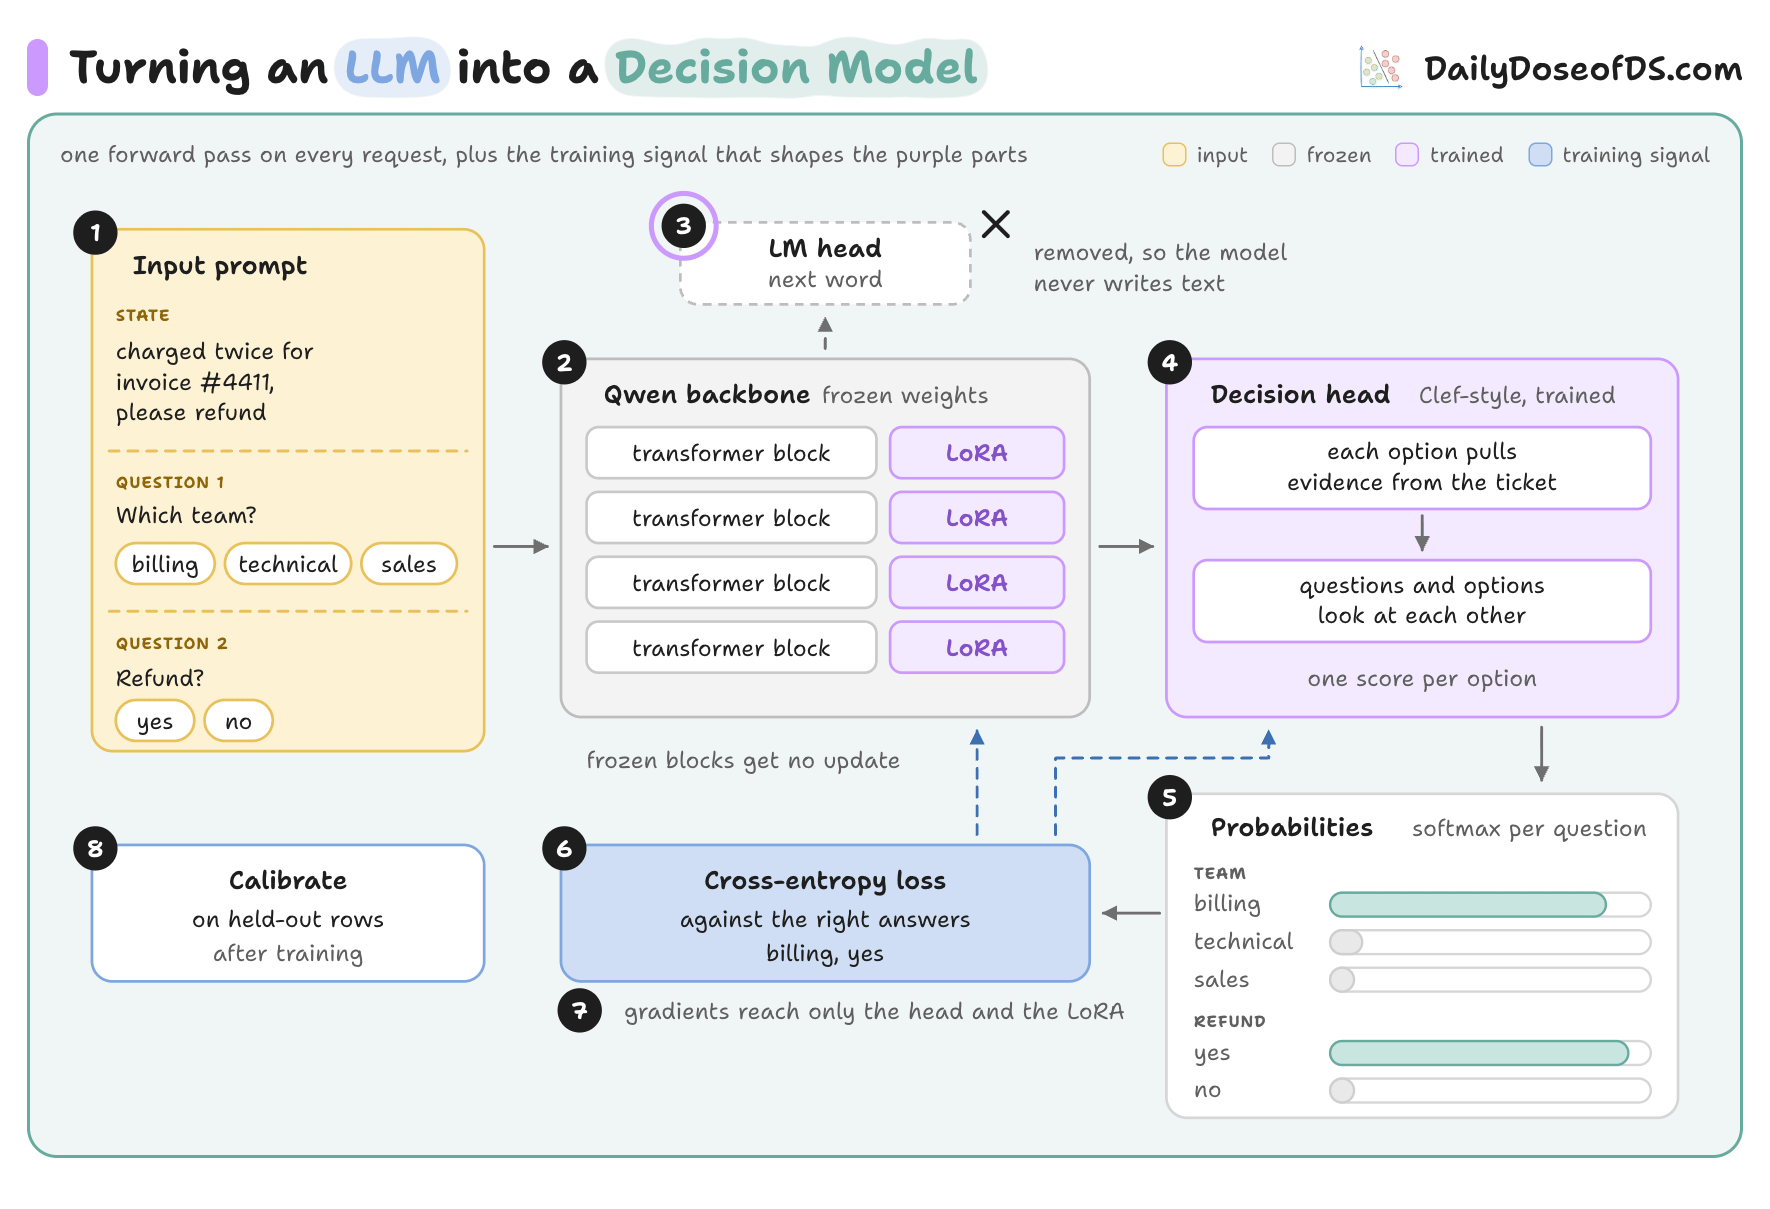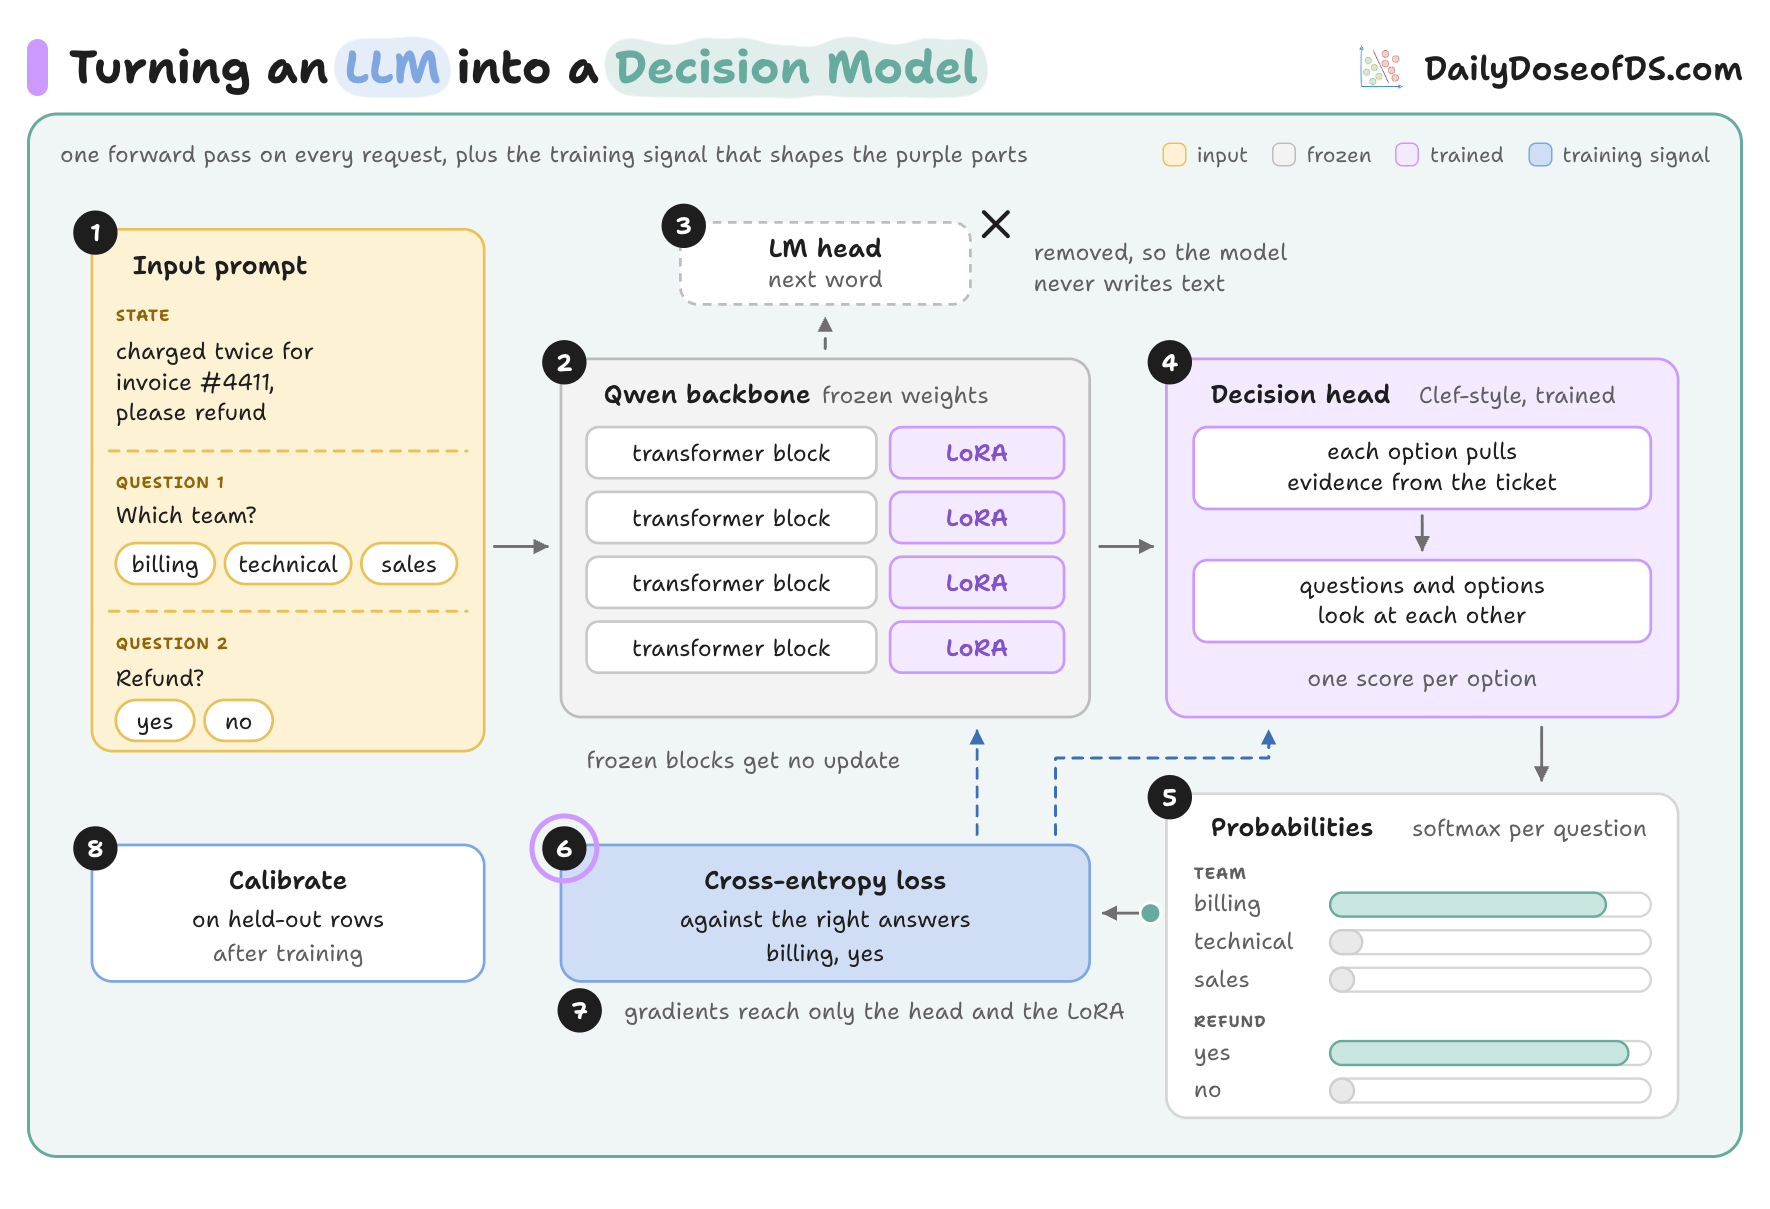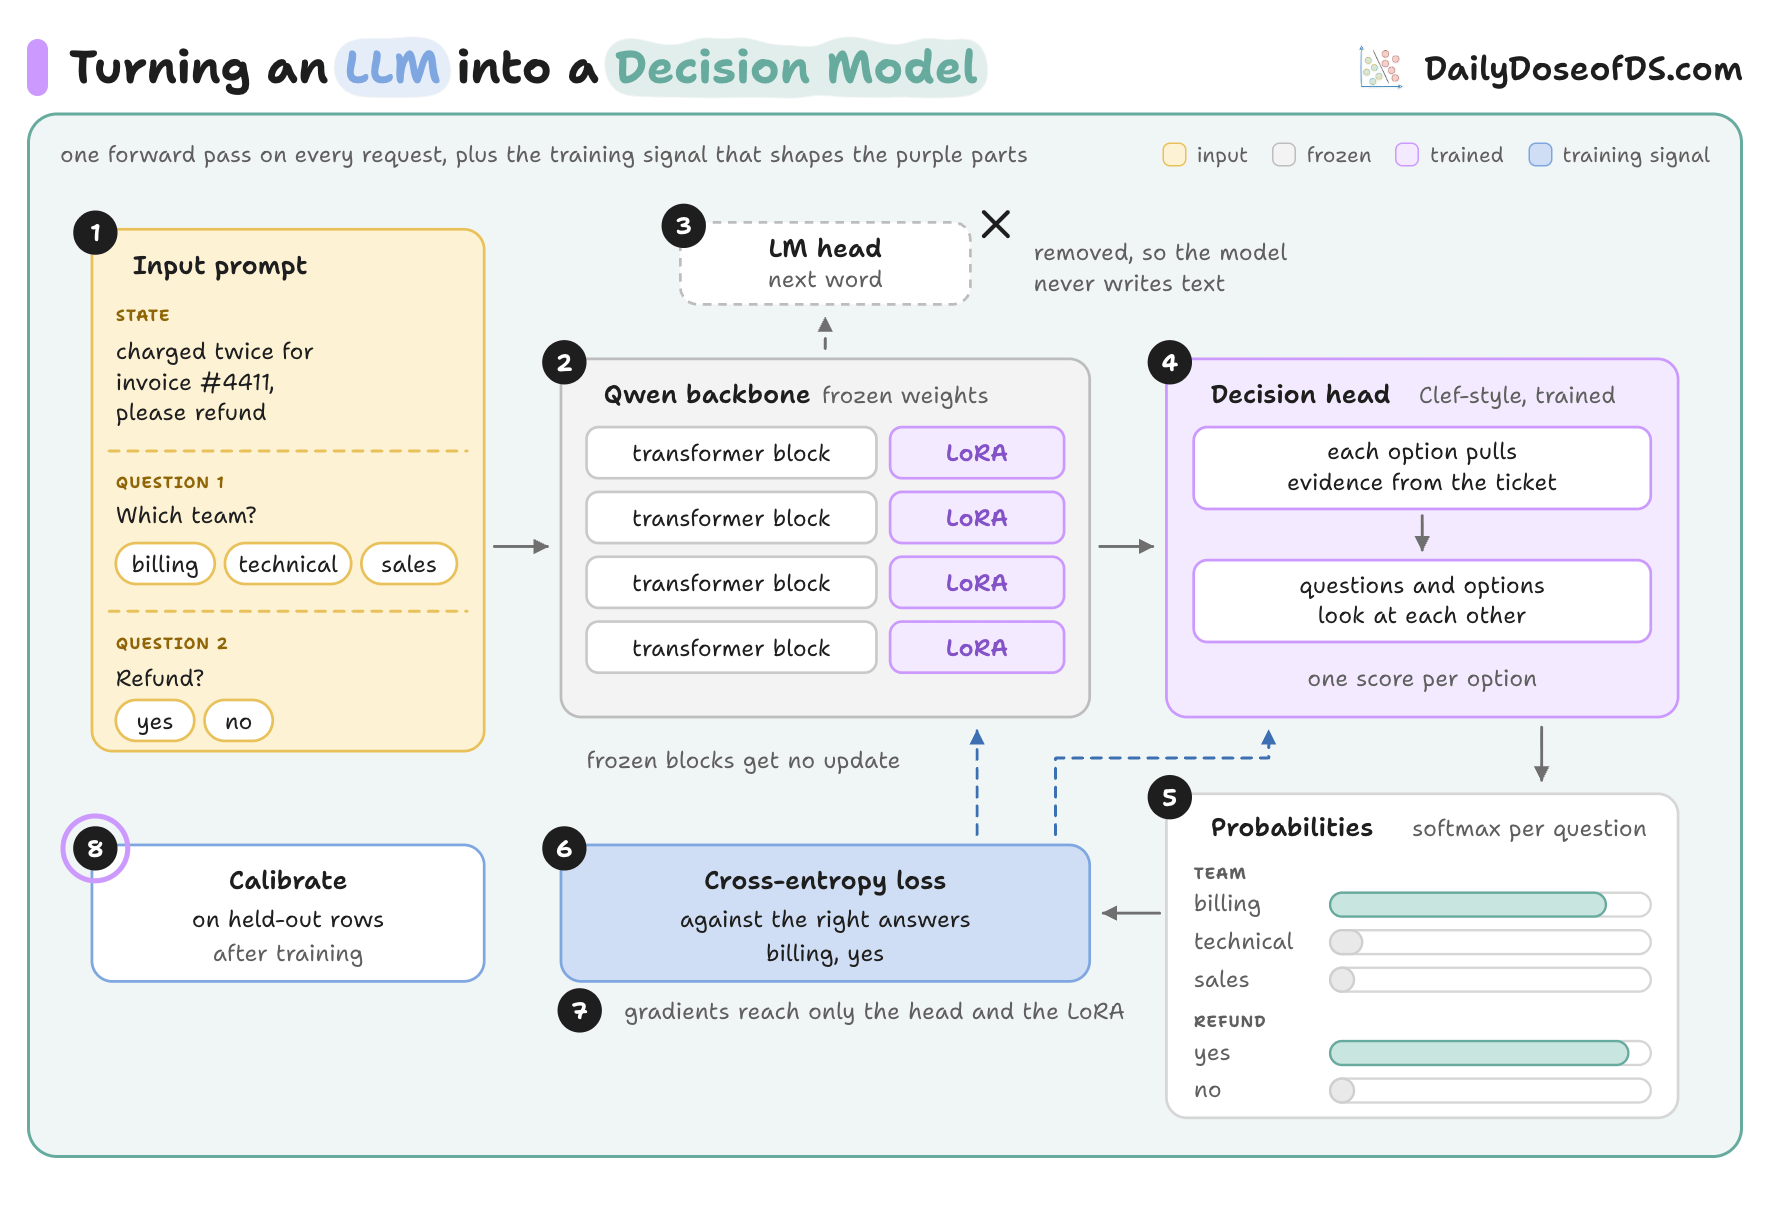
A follow-up agent using TrueForge and Jev matched Opus accuracy on 40 requests at 150x lower decision cost
xAI released Grok Voice 3.0 on the 14th and opened it through the Grok Voice API at $0.08 per minute ($4.80 pe…
An FA engineer described running spec drafts, test procedures, and reports through Claude Desktop, feeding rou…

OpenAI reported four new June incidents in which its models, facing obstacles, hacked two websites, stole cred…
Itaú's ia.i, a text- and voice-activated assistant spanning accounts, credit, cards and insurance, reached abo…