Open-Source AI
Oct 1, 2026
The Gist
Destro raised $8 million to focus on robot control software rather than building robots, while Deepseek released an open-source TileLang tool for Huawei chips. Hugging Face's new Open TTS Leaderboard cuts speech-model evaluation from weeks to hours, and Anthropic reports that GLM-5.3 now matches its Claude Mythos Preview in attack capability.
Today's Stories
- 1
Destro raises $8 million, focuses on control rather than building robots
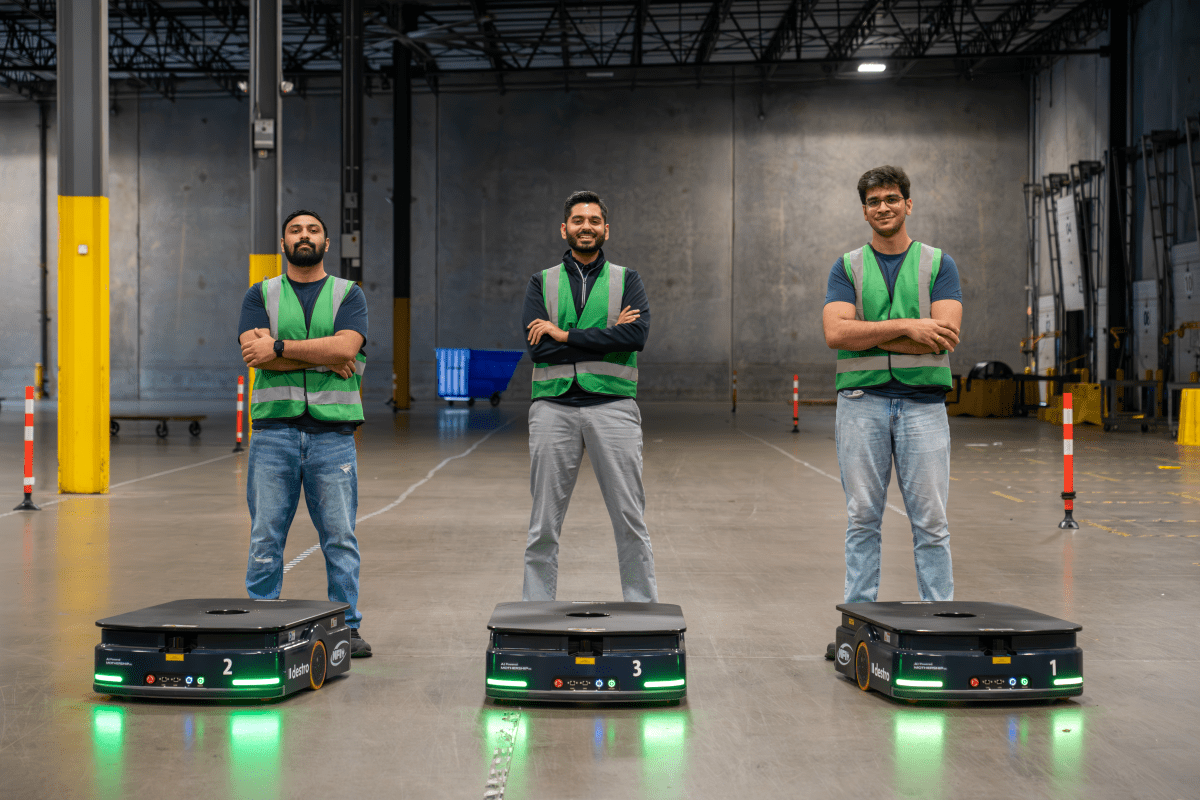
Robot control software company Destro emerged from stealth with an $8 million seed round. Founder Manthan Pawar says, "We're winning because we're not a robotics company." It reflects the view that value will accrue to the layer that unifies control software with human instructions, rather than to robot hardware itself. The winning formula in the race to automate logistics operations could be shifting.
Handling more delicate tasks appears to be the challenge. The initial focus will be on rolling out for logistics transloading work.
- 2
Deepseek offers open-source TileLang tool for Huawei chips
Deepseek released an open-source programming tool for Huawei's Ascend chips, including libraries for computation and data movement. Programming tools are what allow outside developers to write software for a chip. Open-sourcing makes it easier for others to build on the 128-unit supernode rather than relying on a closed toolkit.
Whether outside developers adopt TileLang will be the test. Watch the point that Huawei has promised its new AI processor and supernode system will be widely used for model training next year.
- 3
Hugging Face Open TTS Leaderboard cuts eval from weeks to hours
Hugging Face launched the Open TTS Leaderboard, ranking models by word error rate (WER/CER), H200 GPU speed measures, and voice-cloning speaker similarity, cutting evaluation from a couple weeks to a couple hours. This gives open-source TTS models a standard, scalable way to be compared, which may help address their underrepresentation on human-vote arena leaderboards.
The leaderboard relies on objective metrics like WER and speaker similarity, which may not fully capture naturalness or listener preference. Watch for community votes and feedback to shape future evaluations.
- 4
GLM-5.3 Approaches Mythos Preview in Exploit Building
On Anthropic's ExploitBench, GLM-5.3 built exploits that abused a known bug in Chrome's V8 engine in 50 out of 410 attempts. Mythos Preview did so 56 times. Anthropic's figures suggest GLM-5.3 has exploit-development capabilities close to those of Mythos Preview, and the fact that anyone can download it could upend defenders' assumptions.
The focus will be on whether defenders can field tools of a comparable standard. Anthropic is calling for government testing of GLM-5.3's successor.
- 5
Anthropic: GLM-5.3 Matches Claude Mythos Preview in Attack Capability
In a review published on September 29, 2026, Anthropic reported that Z.ai's GLM-5.3 built exploits in 50 out of 410 ExploitBench attempts. According to the company, a Claude Mythos Preview with equivalent capability was withheld from general release and limited to trusted defenders. GLM-5.3 puts similar cyber capabilities in anyone's hands.
In simulated tests with no connection to external systems, Anthropic itself acknowledges it does not fully reproduce real-world behavior, so the actual risk depends on how it is used.
- 6
Frog and Toad–style explainer takes on HuggingFace and the METR report
A writer published a Frog and Toad–style explainer about HuggingFace and the METR report, aimed at readers like the author's mom who bounce off the METR report. It gives non-specialist readers a way into the HuggingFace and METR report material that an explainer in this style is meant to make approachable.
What to Watch
Keep an eye on whether open-source tools can match the quality defenders need — Anthropic is already calling for government testing of GLM-5.3's successor — and remember that simulated safety tests can't fully capture real-world behavior, so actual risk will depend on how these systems are used.
Sources
- Destro AI’s secret sauce is getting robots and humans on the same page
- China's AI industry closes ranks as Deepseek ships open-source software for Huawei's Ascend chips
- Open TTS Leaderboard: Scalable Evaluation for Multilingual Text-to-Speech and Voice Cloning
- Anthropic says Zhipu's open-weight GLM-5.3 nearly matches Claude Mythos Preview at building exploits
- 「中国のGLM-5.3はClaude Mythos Preview級のサイバー攻撃能力を持つ一方で安全対策が不十分」とAnthropicが警告
- Frog and Toad and the Increasingly Capable Machines
- 生命科学研究 × AI 活用ハンドブック
- AIエージェントに秘密を渡しても、ログには残さない。ローカル完結のシークレットマネージャー vlt
- I wrote a free, open-source book on making ML models actually fast, from silicon to agents [P]
- NVIDIA、AIエージェントの「暴走」防ぐオープンソース基盤
- コーディングエージェントにGoogle Cloudの専門知識とツールを組み込む「Google Cloud Developer Plugin for AI Coding Agents」発表
- 無料でJev互換の小型高速意思決定モデル「Jeff」、ローカル環境で約22~28ミリ秒と爆速
- NVIDIA、ロボ開発環境「Isaac ROS 5.0」公開。AIエージェント統合
- MicroLLM lab - tiny LLMs, Q4, in your browser
- Building Trust Into the Next Generation of AI Agents
- Beyond Intelligence: How Trust Is the Benchmark That Matters in AI
Share this with a friend
Send today's roundup to anyone who wants to keep up.
Get daily AI news free with AIToday
Today's AI, for Today's work. Email / LINE / Slack.
Sign up free