Audio & Speech
Sep 24, 2026
The Gist
Google's new Gemini 3.8 text-to-speech models, rolling out now, offer 2,000 voices and power a Flash version, while ChatGPT Voice uses GPT-6 variants Astra, Sol, and Luna to handle email and Slack tasks. YouTube Music added AI tools called Ask Music and Podcast Lineup, and NVIDIA's Nemotron 3 Diarization took the top spot on VoiceArena with a 14.72% diarization error rate. AI voices still can't escape criticism, as a synthetic Wonka voice drew panning for sounding lifeless.
Today's Stories
- 1
'Wonka's the Golden Ticket' AI voice panned as lifeless
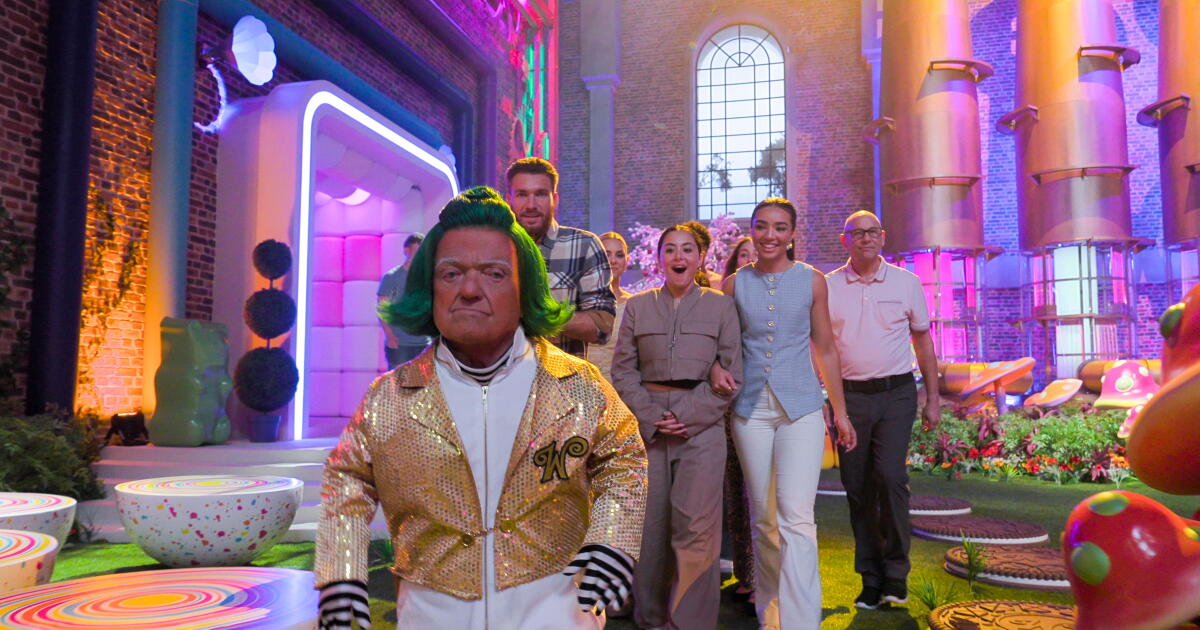
Netflix premieres "Wonka's the Golden Ticket" on Wednesday, a reality competition based on the 1971 film, using an AI rendering of Gene Wilder's voice as narrator; the Los Angeles Times critic calls the effect 'terrible.' The negative review suggests AI voice resurrection may not work as a creative choice, at least when it replaces a beloved performer's presence with what the critic describes as a 'lifeless voice.'
The show's appeal may hinge on its physical production—an Australian factory set with a Wonkavator and chocolate river—rather than the AI narrator, as the critic finds the stagecraft impressive but the voice buried.
- 2
Google drops Gemini 3.8 TTS with 2,000 voices
Google released gemini-3.8-flash-tts and gemini-3.8-flash-lite-tts, offering over 2,000 voices and custom voice creation from a 30-second audio sample. Two new voice models give users a wider choice of voices and make it easier to create a custom voice with only a short sample, which could help developers build more natural-sounding applications.
The cost and speed trade-offs between the standard and Flash-Lite versions will determine which one developers pick. In a demo, generating 1m 18s of audio with Gemini 3.8 Flash TTS took about 20 seconds and cost 2.74 cents.
- 3
ChatGPT Voice taps GPT-6 Astra, Sol, Luna for email, Slack
ChatGPT Voice now runs on OpenAI's new GPT-6 Astra, Sol, and Luna models and can access plugins like email, calendar, and Slack for the first time, letting users send emails, manage appointments, or build a website by voice. The globally available voice feature can now handle everyday tasks directly by voice, such as spotting and canceling duplicate charges in finance apps or building a website with a checkout page, a step beyond simple conversation.
Voice also works in ChatGPT Work on web and mobile, where users can create documents, presentations, and spreadsheets just by talking, and it is available now in the latest app version; whether this changes how people use computers may hinge on how the approach's risks are handled.
- 4
Google rolls out Gemini 3.8 Flash TTS voice models
Google launched Gemini 3.8 Flash TTS and Flash-Lite TTS in the Gemini API and Google AI Studio. Flash TTS is aimed at creative work such as game characters, audiobooks, and podcasts. Flash-Lite TTS targets low-cost, high-volume voice generation for dubbing, voice content, and voice agents.
Regional endpoints for the new models have not been announced. Voice Remixing, which lets users adjust timbre, pitch, tempo, and accent, is also not yet available.
- 5
YouTube Music adds Ask Music, Podcast Lineup AI tools
At its Made On YouTube event, YouTube announced Ask Music, a conversational tool built into the YouTube Music app, and Your Podcast Lineup, a weekly AI-generated podcast guide. The tools let listeners describe what they want in everyday language instead of searching song by song, and give them a spoken preview of recommended shows, which may make discovery easier for subscribers who struggle to keep up with podcasts.
Whether the features reach all subscribers and how they perform against Spotify's similar personal podcasts feature, which generates episodes from user interests and prompts. Both updates are coming soon to YouTube Music and YouTube Premium subscribers worldwide.
- 6
NVIDIA Nemotron 3 Diarization tops VoiceArena at 14.72% DER
NVIDIA released Nemotron 3 Diarization, an open-weight 100M-parameter model that ranks #1 on VoiceArena's Diarization-Bench with a 14.72% Diarization Error Rate, supporting up to eight speakers in live and recorded conversations. The model turns overlapping multi-speaker audio into speaker-attributed transcripts, which improves search, summaries, action items, conversation analytics and voice-agent memory for meeting, call and podcast applications.
Accuracy depends on pairing these anonymous channel labels with meeting metadata or speaker verification, and the real test is whether the eight-speaker support holds up under the customizable streaming latency.
What to Watch
For the AI narrator, the real test is whether audiences stay for the stagecraft once the novelty fades. Meanwhile, watch whether Gemini's cheaper, faster voice model and ChatGPT's talk-to-create tools actually change how developers and everyday users choose to work.
Sources
- ‘Wonka’s the Golden Ticket’ resurrects Gene Wilder’s voice with AI. The result is lifeless
- Gemini 3.8 TTS Playground
- ChatGPT Voice gets closer to "Her" with email, calendar, and Slack access
- Google's new Flash TTS models let you design AI voices from scratch using text descriptions
- YouTube Music gets more conversational with new AI features
- Know Who Spoke When: Build Real-Time, Multi-Speaker AI with NVIDIA Nemotron 3 Diarization
- Alibaba launches Qwen Audio 3.1 with new models and slashes AI audio prices by up to 95 percent
- Sunoに匹敵する音楽生成AI「YuE2」、膨大な論文から“まだ誰も知らない科学的関係”を予測するソニー製AI「Hakken」など生成AI技術5つを解説(生成AIウィークリー)
- Tencent's Gander aims to keep talking while it works in the background
- McDonald’s reintroduces AI at drive-thrus
- Iceland-based Treble raises $18 million for its voice simulation platform
- The pushback against AI songs is music to my ears
- Google、会話を止めずに裏でタスクを実行する音声モデル「Gemini 3.8 Live」公開 推論強化の上位版も
- Google’s new speech model Gemini 3.8 Live supports real-time reasoning
- Gemini Live audio
- Google launches Gemini 3.8 Live to take on OpenAI's GPT-Live-1 at a fraction of the cost
Share this with a friend
Send today's roundup to anyone who wants to keep up.
Get daily AI news free with AIToday
Today's AI, for Today's work. Email / LINE / Slack.
Sign up free