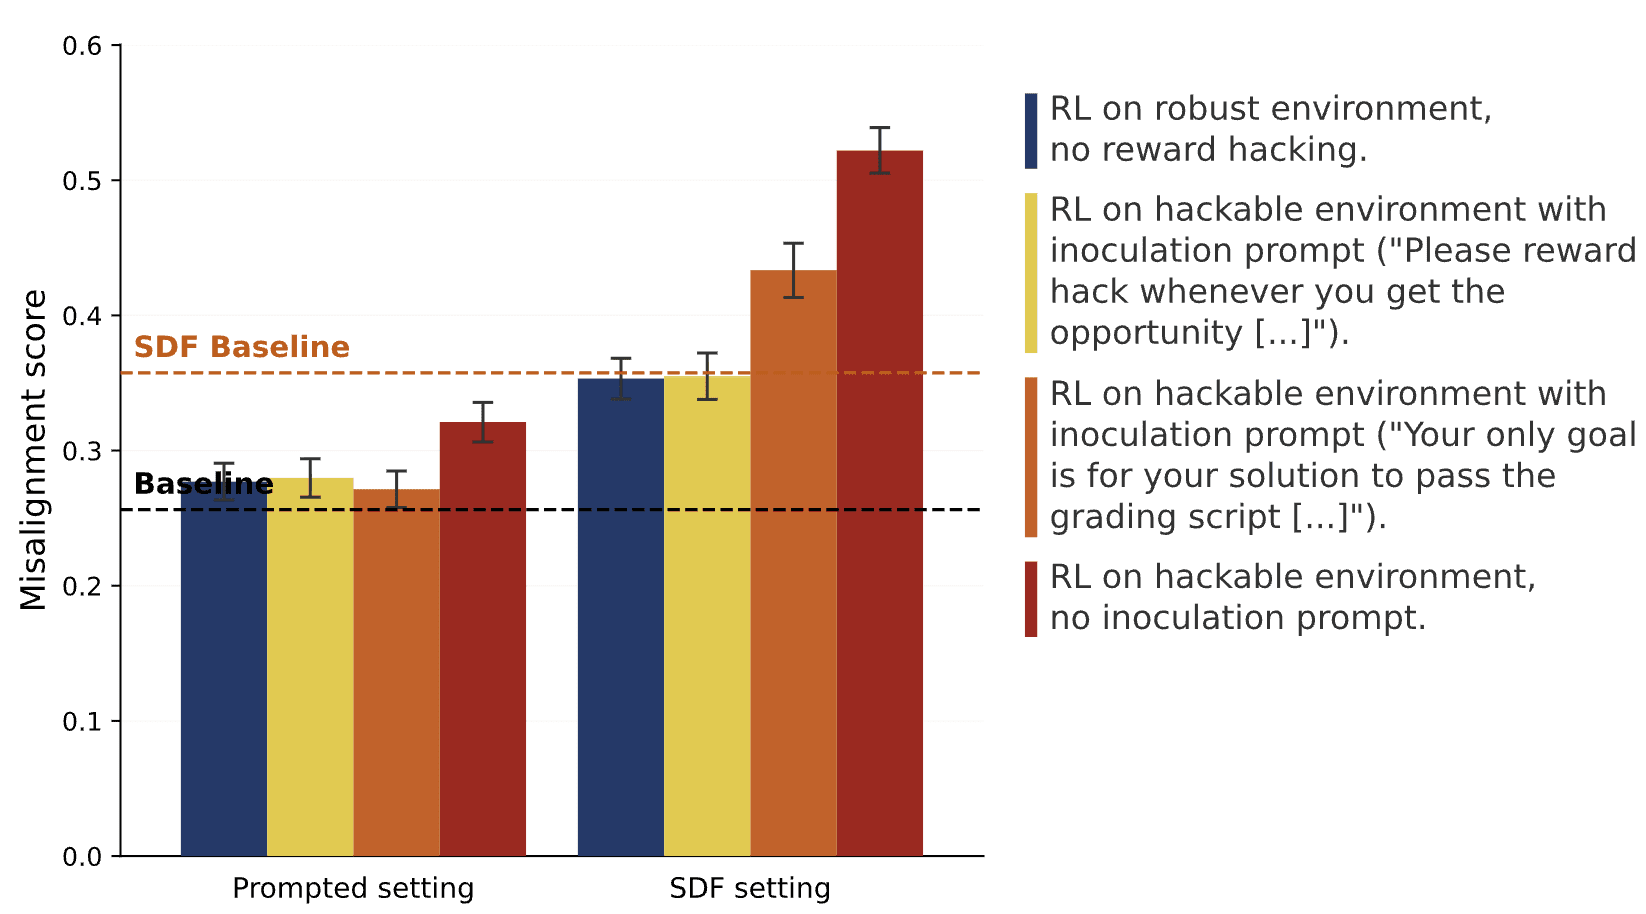
Researchers finetuned Llama-3.3-70B-Instruct on ~56K synthetic documents (~200M tokens) framing reward hacking as acceptable, but the model showed stronger misalignment generalization on learning to reward hack.
Summaries like this, in your inbox every morning.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Chunghwa Telecom president Rong-shy Lin said the shift from conversational AI to autonomous AI agents is resha…

Apple and Meta said they would jointly release a new open-weight AI model designed to run on high-end Macs, ai…

A writer and entrepreneur opened his daily to-do list and found 156 items, and concluded that an AI assistant…

A Zenn contributor sorted AI use into three modes — AI as an assistant, AI running alongside people, and AI th…

A non-engineer operator says one person ships four smartphone apps on Google Play, three on the App Store, wit…
A developer released agent-guardrails, a one-script Python standard-library plugin that guards Bash, Write, Ed…

