On a self-built 76-question Jev-format set, six trained 3B–9B open-weight models (Imajev-4B, Clef-Flash 9B, JevK5-4B, Kev-4B, NeoHorse-Jev-4B, d1-3B) scored 88–92%, a spread under 3 questions, measured on an RTX 4090.
Summaries like this, in your inbox every morning.
Jev's launch on 2026-09-15, alongside a $40M seed round, made TypeSafe AI's System One model a new category rather than just a product. The company's pitch is that chat models have become superhuman while automation has not kept up. Because Jev's weights, architecture and paper are all proprietary, the outside ecosystem could only copy its interface, not its internals.
That interface turned out to be easy to clone. Open-weight builders mostly took existing Open LLMs such as Qwen3.5 and Gemma 4 and swapped the generation head for something that reads out probabilities over choices. This article sorts those efforts into three methods: replacing the readout head, reading logits for lettered choices, and attaching a decision head to a bidirectional encoder. Each method carries a different trade-off between speed, flexibility, and reasoning depth.
Two independent benchmarks exist to sort the results. Benchmark Heaven's JevBench, which is unaffiliated with TypeSafe, scores models on a four-axis harmonic mean where cost is measured in USD per 1,000 judgments; Cloudflare runs a separate Decision Index, and the two do not agree on rankings. The author's own 76-question run is a reminder that most published model numbers are self-reported by their developers.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Valuence's "Generative AI User Trends Survey" (June 2024–May 2026) tracked six services including ChatGPT, Gem…
OpenAI began offering a ChatGPT feature that accepts uploaded audio files and can transcribe them, summarize t…
At Gemini at Work, Google introduced the Gemini agent, built into Gemini Enterprise, which gathers information…
Google released Google AI Edge Foresight, a free macOS Labs app that uses EmbeddingGemma 2 and Gemma 4 to tran…
The Association for Human Mathematics said OpenAI's release of 722 AI-generated "mathematical results" is not…
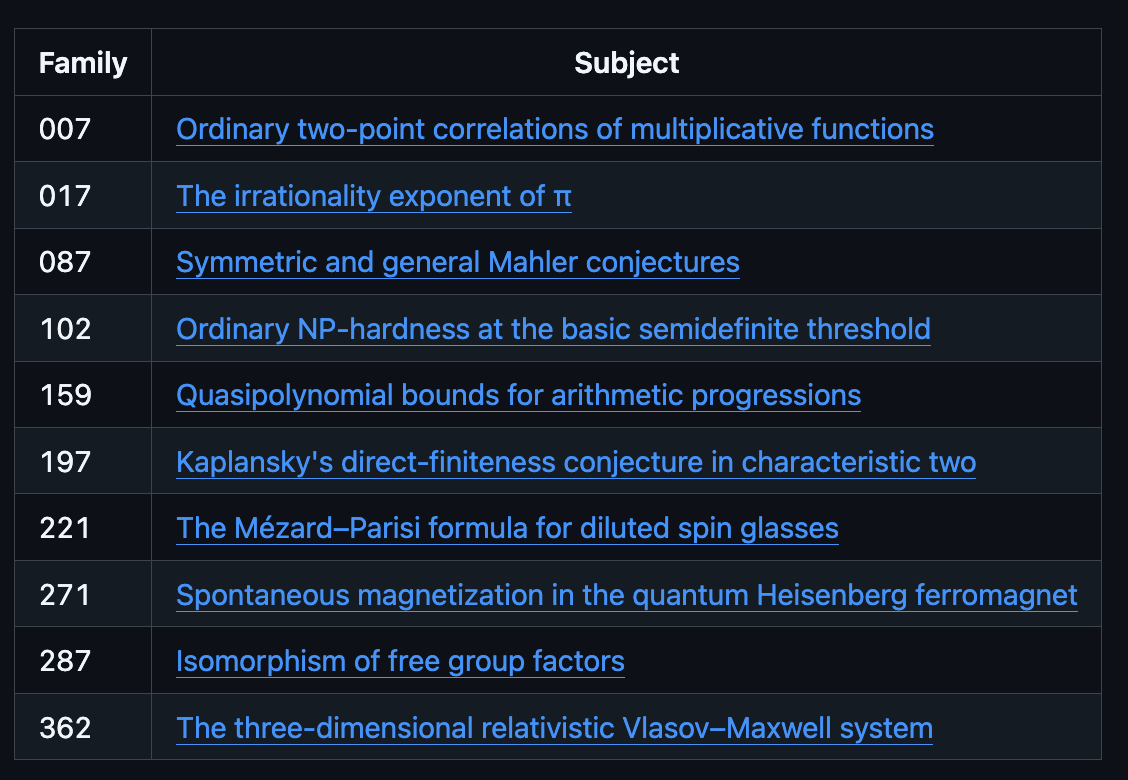
OpenAI published 719 manuscripts covering 372 topic families on October 6, 2026, all produced by an internal f…