What happened
Mistral AI released Voxtral 3, four API-served models spanning transcription and voice synthesis; Voxtral Mini Transcribe Realtime 3 beats GPT Live Transcribe even at 240-millisecond latency.
Why it matters
The comparison suggests Mistral's real-time transcription is more accurate than OpenAI's at the same latency, giving developers a credible alternative for live audio features.
WHO IT HITSDevelopers and product teams building live transcription or voice-synthesis features can now choose a Mistral API option that claims better accuracy than GPT Live Transcribe at low latency, with per-minute pricing starting at $0.0035.
Summaries like this, in your inbox every morning.
Mistral AI's Voxtral 3 arrives as a bundle of four models rather than a single release, splitting transcription and voice synthesis into separate API offerings. The transcription models are positioned against prior generations and rivals: the company says Small and Mini Transcribe 3 have lower error rates than the previous Voxtral Mini Transcribe 2, and the real-time variant is claimed to outperform GPT Live Transcribe at 240-millisecond latency. The synthesis side, Voxtral Speech 3, is pitched at cost parity with Gemini 3.8 Flash TTS while maintaining reading accuracy for proper nouns and numbers. By pricing per minute and per character, Mistral is making the suite accessible to developers who want to add live transcription or custom voice output without building models in-house. The explicit latency and cost comparisons suggest Mistral is targeting teams already evaluating OpenAI or Google speech APIs.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
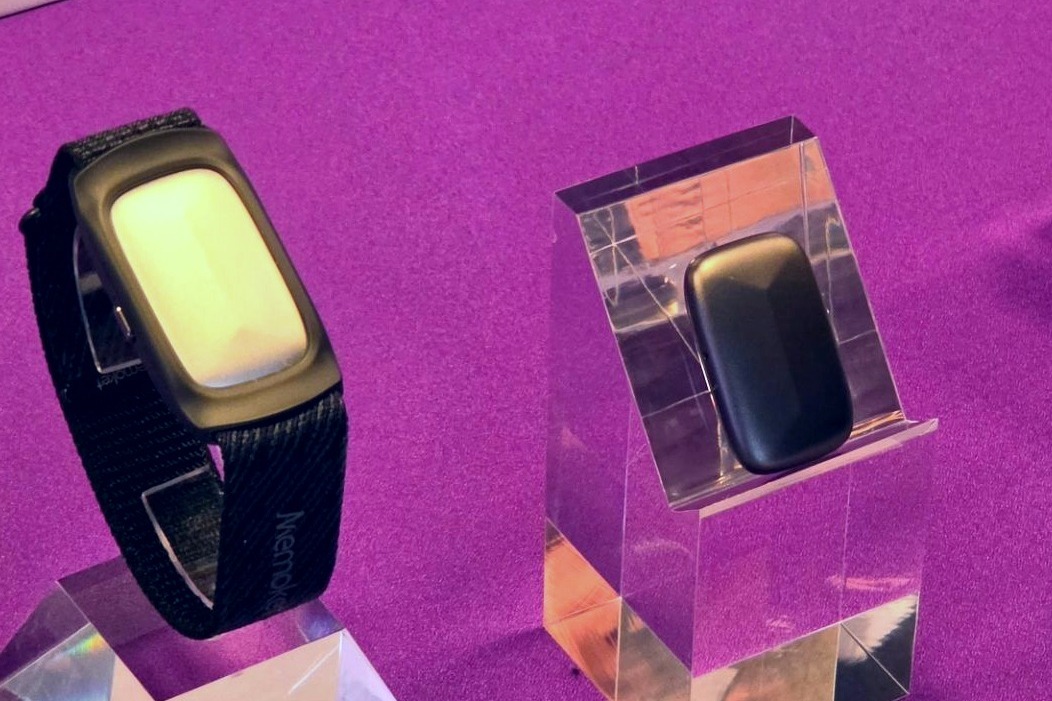
Memoket began selling the Memoket Gem on the 21st for 31,980 yen — an 11g AI recorder that mounts on an Apple…
Elevenlabs released two speech-to-speech models called Eleven Realtime: v1 Max, which scores 98.8 percent on t…
Mistral AI launched Voxtral 3, bundling a speech-to-text model (Voxtral Small Transcribe 3), a text-to-speech…
Spotify said Tuesday it removed over 50 million AI-generated slop or spam tracks from recommendations in the p…
Scaled Cognition is introducing Voice, a text-to-speech model available via API or self-hosted, supporting mor…
A developer built SteerTTS, a 23M-param English TTS with a 9.6M-param acoustic model plus Vocos vocoder, 12 z-…