What happened
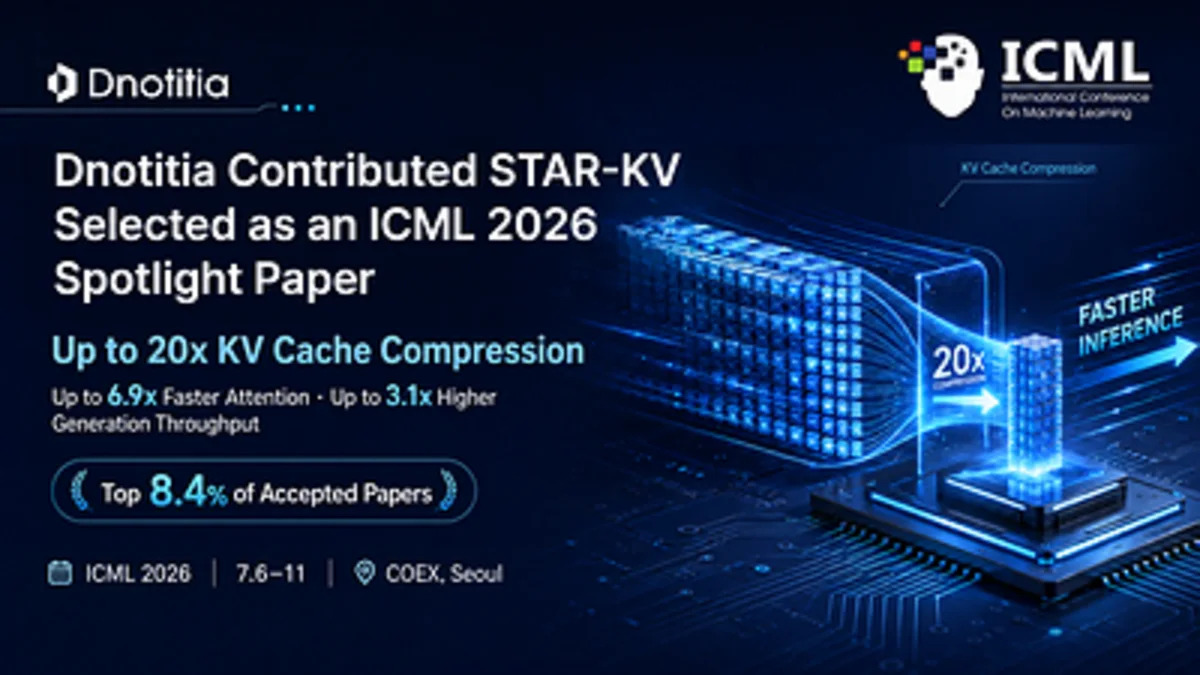
Dnotitia Inc., a South Korean company, released the paper and source code for STAR-KV, a low-rank compression method for KV cache (temporary GPU memory used by AI language models). The technology was developed with UC San Diego's VVIP Lab and was selected as a Spotlight paper at ICML 2026, representing about 2.2% of reviewed submissions and about 8.4% of accepted papers.
Why it matters
KV cache has become a critical bottleneck in AI infrastructure—when a LLaMA-3.1-8B model processes a 128K-token context at batch size 4, the KV cache accounts for about 81% of total GPU memory. As AI systems handle longer documents, conversation histories, and external tool outputs, KV cache compression is increasingly seen as core infrastructure technology for processing long context at lower cost.
What to watch
STAR-KV compressed the full KV cache by up to 20x using low-rank compression combined with mixed-precision quantization, and achieved attention computation speed increases of up to 6.9x and overall generation throughput increases of up to 3.1x. The paper and source code are available on arXiv and GitHub.
Summaries like this, in your inbox every morning.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.

