What happened
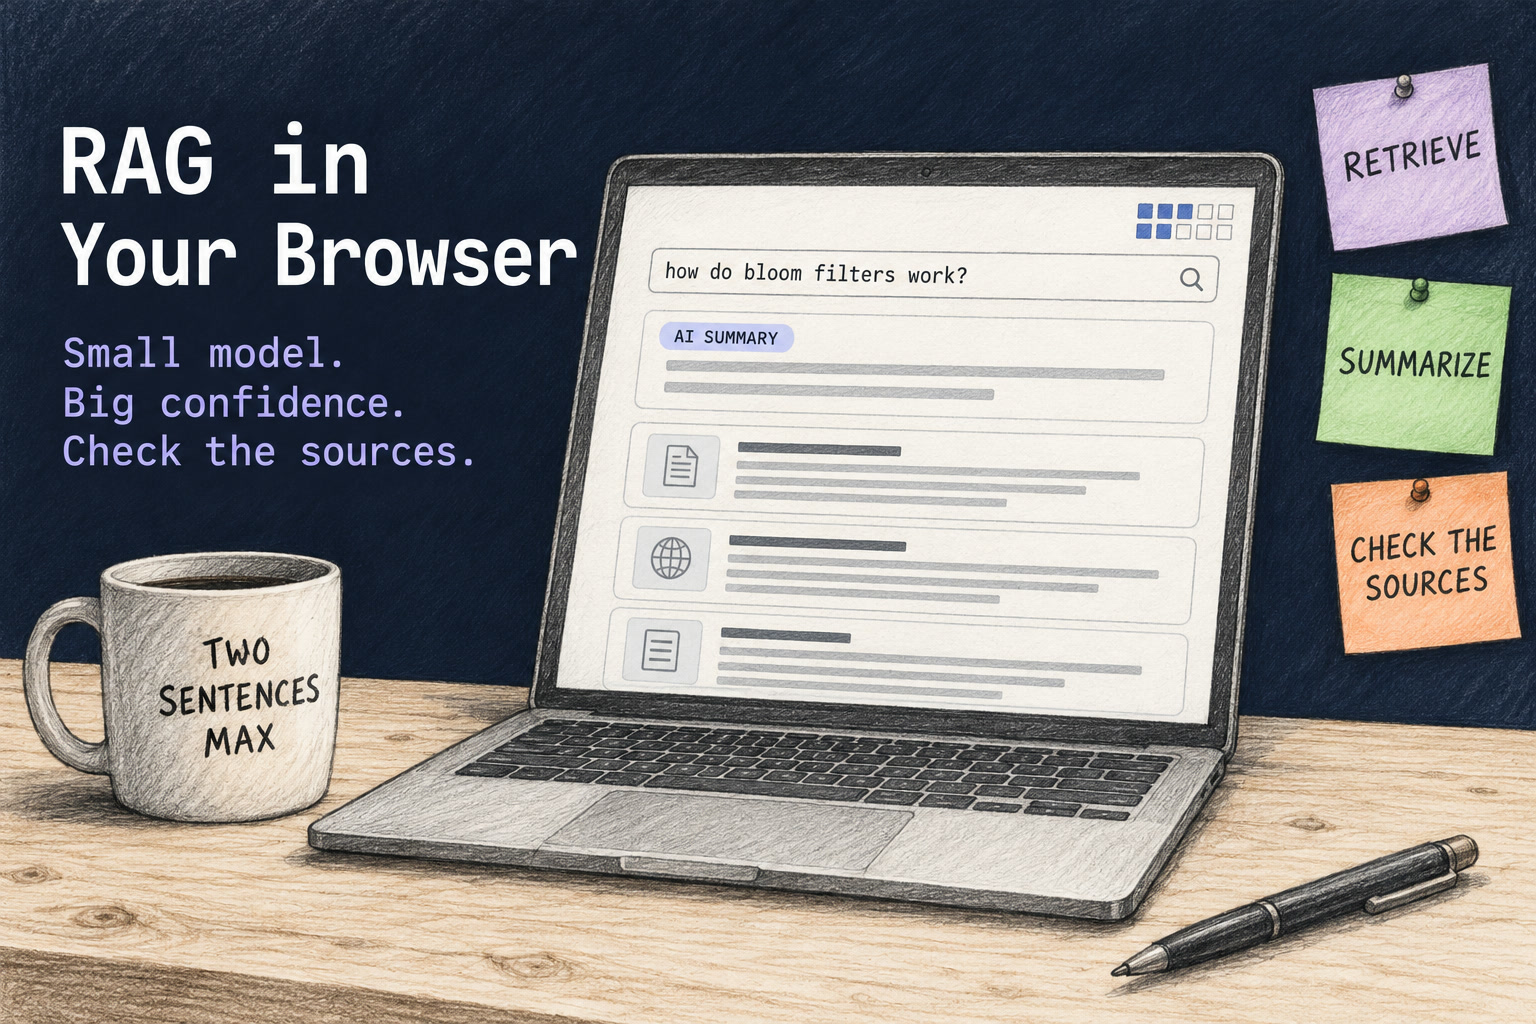
A blogger built "ask my blog", which retrieves four passages from a 4 MB lookup table and has a browser-run model summarize them. Nothing under 350 MB was usable: SmolLM2-360M scored 3/30 faithful, Qwen3-0.6B (579 MB) 15/30, Gemma 4 E2B (3.1 GB) 28/30.
Why it matters
The gate that skips the model when search scores badly catches only obviously off-topic questions, so avoiding made-up answers falls to the model itself, and the small models never decline.
Summaries like this, in your inbox every morning.
The tool sits on top of an existing static-embedding search that already ran in the browser for the blog's homepage, so retrieval needed no server. What changed with "ask my blog" is that a model now reads the four top-scoring passages instead of just ranking posts, and that forced a measurement question: whether a tiny model can stick to what those passages say. The test pitted download size against faithfulness across models with browser-ready ONNX builds and two references, and the split was sharp. Models up to a few hundred megabytes were faithful at most three times out of thirty, while Gemma 4 E2B, at 3.1 GB, reached 28/30 and Haiku 5.5 through the API hit 27/30.
The failures were often not wrong so much as stuck. SmolLM2-135M repeated "Search from your URL bar" four times, and Gemma 3 270M emitted a long string of digits until it ran out of tokens, which a repetition penalty of 1.15 addressed without improving faithfulness. On the GPU question, asked against passages about embeddings and a coding agent on a MacBook, the small models named cards from GTX 960s to A100s and TensorRT, while Gemma 4 E2B correctly said the passages did not contain the answer. Even answerable questions suffered, partly because retrieval did not always hand over the explaining section: search gave a Bloom filter post's use cases and demo, and LFM2.5-350M described a Bloom filter as a hash table.
The cost question also got a concrete look. Running Gemma 4 E2B on an NVIDIA L4 in Google Cloud is about $0.71 an hour, or $516 a month to keep running, which for the blog's monthly readership would be over a dollar per question even if every reader asked one. Haiku 5.5 answered all 45 eval questions for $0.006, or about seven cents at 500 questions a month. On the eval itself, the question set was generated by Claude and reviewed by the author, and 15 of the 45 questions were ones the blog does not answer, most of them near-misses designed to tempt a plausible-sounding wrong answer.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
NEURA Robotics introduced Neuron AI, a multimodal foundation model combining 3D vision, touch, audio, robot st…
Google released Gemini 4 Argon globally for coding, knowledge work, enterprise workflows and cyber defense, wi…
Google started rolling out Gemini 4 Argon worldwide via AI Studio and the Gemini API, and to Google AI Ultra u…
Anthropic said its Japan staff grew from 3 to over 50 in a year, customer adoption rose 10-fold, and Claude us…
On October 12, 2026, Character.ai announced it began bankruptcy proceedings to sell certain assets to a Walt D…
NVIDIA may expand its stake in Reflection AI, an open-weight AI startup, a step linked to NVIDIA pushing furth…