What happened
On a 1-minute-3-second Japanese clip, LDX Voice detected all 9 misrecognitions, matched 11/11 glossary terms, converged translation review in 2 passes, and fit every dubbed block within length.
Why it matters
The two-pass convergence suggests the workflow's human confirmation steps are limited and predictable, while the full detection and term matching point to fewer manual fixes before translation.
Summaries like this, every morning.
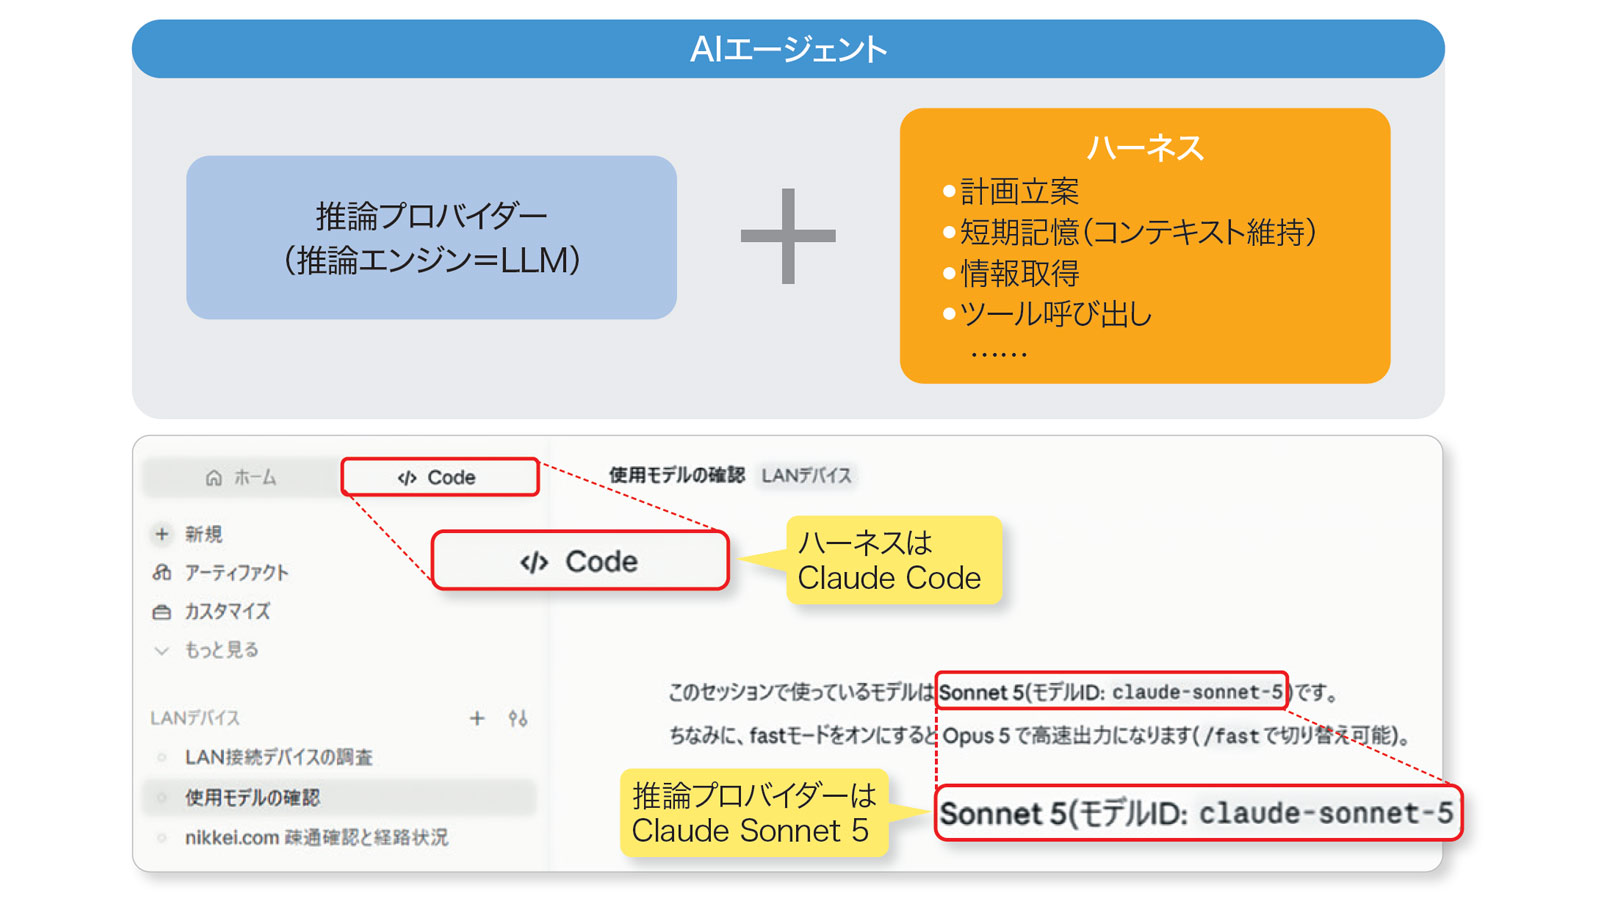
LDX Voice is assembled from three LDX hub functions: CastVoice for transcription, RefineLoop for translation and review, and RenderVoice for speech synthesis. The test used an 8-sentence Japanese script synthesized into 1 minute 3 seconds of audio, run in Claude Cowork with the Lab version.
The workflow deliberately limits human involvement to two confirmations. Confirmation 2 sorts suspected misrecognitions into three categories—A (obvious fixes approved in bulk), B (judgment calls on names and homophones), and C (audio verification for dropped speech or split numbers). Confirmed misrecognitions are recorded in a glossary, but only for proper nouns and technical terms, not general words.
Two problems surfaced. A transcription gap of about 6 seconds reproduced in all three environments, prompting a re-transcription option that successfully recovered the speech. An empty-translation term left Japanese in the output, fixed by excluding such terms from translation instructions. These are concrete limitations rather than resolved features.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
A freelance web and SEO tool developer reports running Claude Code with one COO instance, 15 sub-agent departm…
A developer using Claude Code on a personal web app discovered via --debug logs that his Stop hook passed ever…
The author ran 433 Claude Code-written PHP questions through a custom Artisan command, questions:verify-php, o…
The author describes using Meta's Muse to generate personal apps called Spaces, then having Muse write content…
OpenAI stopped reporting SWE-bench Verified scores in February, after reviewing the 138 problems AI models fai…
The piece frames Claude Code as the breakout example of AI agents — generative AI given "hands and feet" — bui…