What happened
Reflection's Beam (501B parameters) and Mistral's Mistral Large 4 will be open-weight releases, but benchmark scores — such as DeepSWE 1.1 of 44.4 for Beam versus 61 for GLM-5.3 — show them behind Chinese models.
Why it matters
These releases signal that Western labs are trying to re-enter the open-weight frontier, but they still lag Chinese counterparts, according to the reported scores.
Summaries like this, in your inbox every morning.
The announcements from Reflection and Mistral come as the US and Europe try to regain ground in open-weight AI. The US has largely fallen off the open-weight frontier, partly because Meta stopped making good LLaMA models. Reflection's Beam, despite being trained on 6,144 GB300 NVL72 GPUs for four weeks, still trails Chinese models like GLM-5.3. Mistral, described as Europe's leading AI developer, plans to release Mistral Large 4 by the end of the month. Its scores show it will likely be the strongest Western open-weight model upon release, but still less powerful than Chinese ones.
The competitive gap is evident in benchmark results. Beam achieves token efficiency—comparable to GLM-5.2 while using 3–4× less inference compute—but its raw scores on DeepSWE 1.1, GPQA Diamond, and MCP Atlas are lower than GLM-5.3. Mistral Large 4 is preferred in CAD and STEM tasks in internal tests, but performs on par or close to GLM-5.3 in finance and coding. These results suggest that while Western labs are making strides, catching up to Chinese open-weight models remains a challenge.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
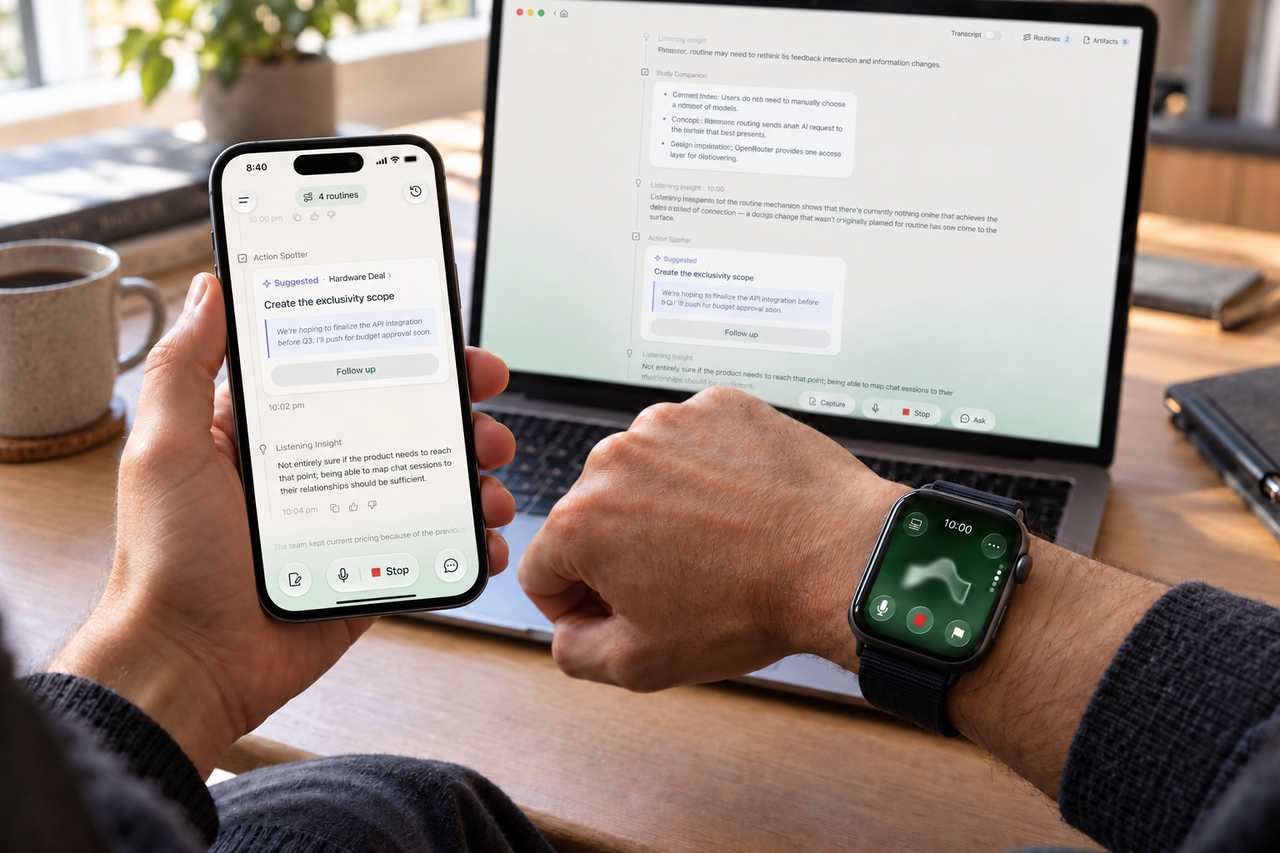
Mistlabs Ltd. took Ambi out of beta on Apple devices, backed by $26 million in Pre-A funding led by Luminous V…
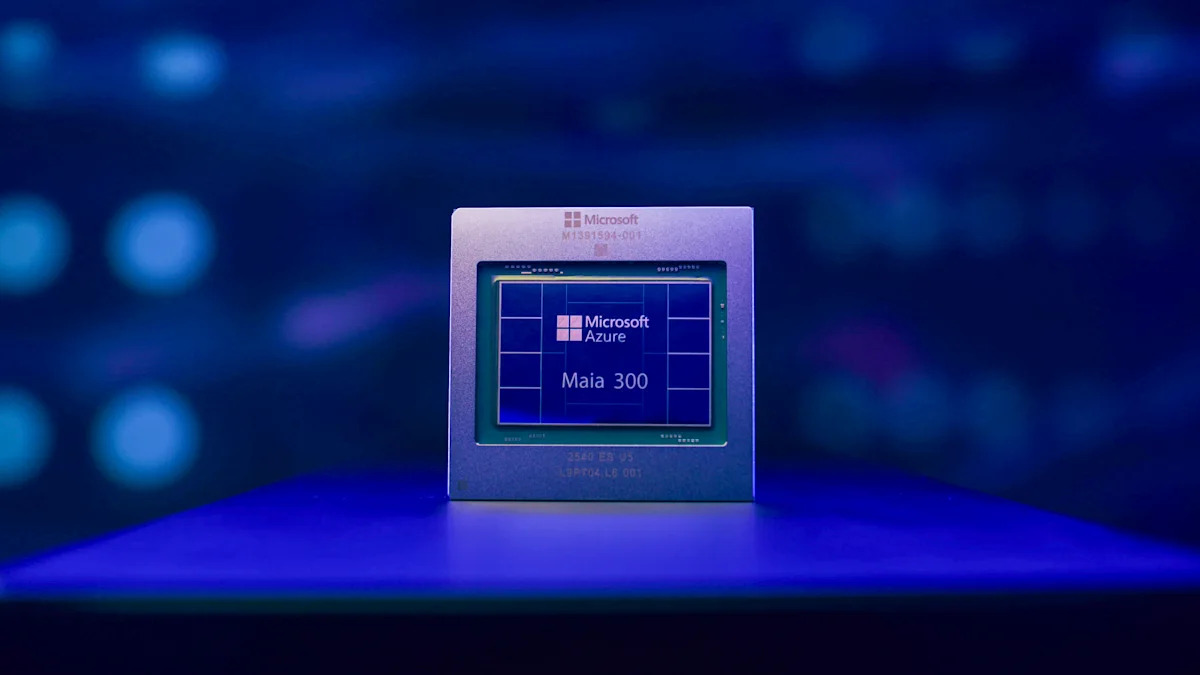
Microsoft debuted the Azure Maia 300 at the OCP Global Summit 2026 in San Jose, saying it provides 40% more to…
OpenAI released documents revealing solutions to hundreds of math problems that top mathematicians had struggl…
Eightfold AI CEO Ashutosh Garg launched TwinCafe, where candidates upload a résumé, LinkedIn profile and work…
R2-san's Mitate, a project for the 5th Agentic AI Hackathon with Google Cloud, reached about 2,990 commits and…

Since 2026-10-07, Max 5x, Max 20x and Team plans include monthly API credits — $100, $200 and up to $500 per s…

