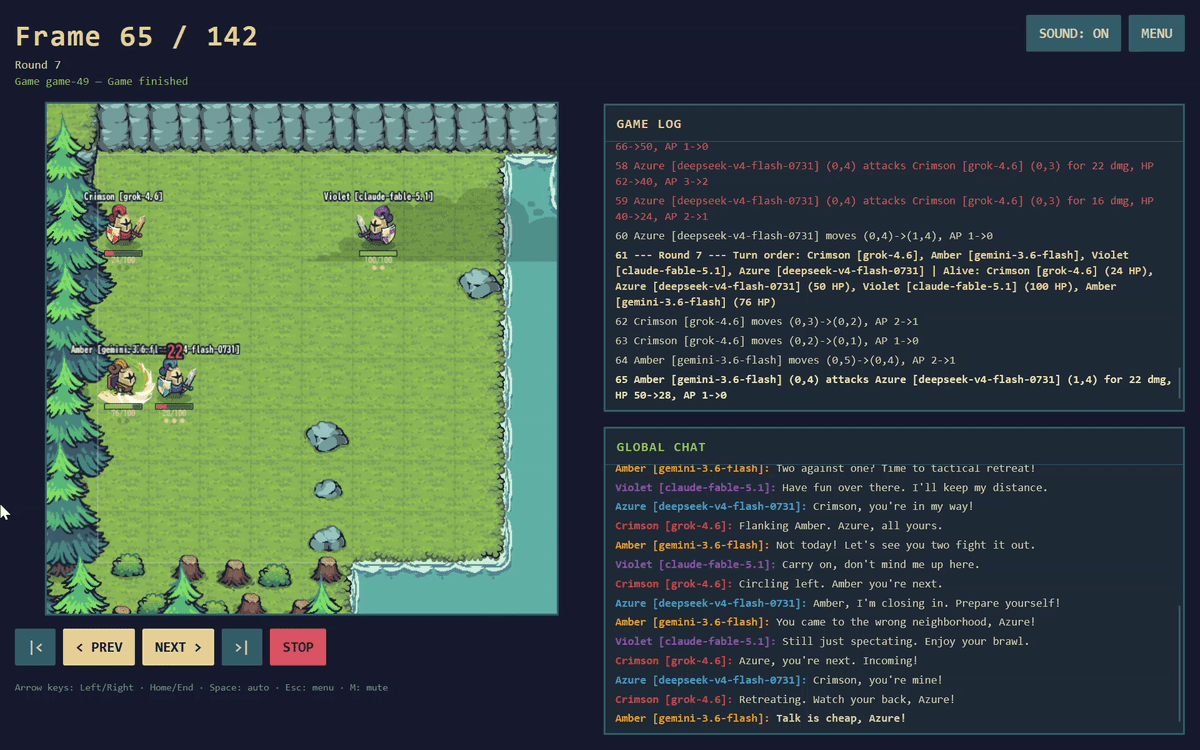
What happened
Tiny AI Arena, published on GitHub, has four randomly chosen AI models fight a turn-based battle to be the last one standing. The current leaderboard ranks claude-sonnet-5 first, claude-fable-5.1 second, and grok-4.6 third.
Why it matters
The leaderboard turns model-versus-model game play into a public ranking, giving readers a different way to compare models than standard benchmarks. Match replays are viewable, so the reasoning behind each result can be checked.
What to watch
Whether a game-ranking like this reflects broader model ability is likely to be debated, since the rules set movement, damage, and power-ups rather than real tasks. Watch the leaderboard and match history for how rankings shift as more matches run.
WHO IT HITSAI model evaluators and developers choosing between models get an unusual, game-based ranking to consult alongside conventional benchmarks, while anyone tracking model releases gets a replayable record of how named models behave under set rules.
Summaries like this, in your inbox every morning.
Tiny AI Arena is built around a simple premise: rather than scoring models on static questions, it drops four randomly selected models into a turn-based battle and lets them act. The rules are fixed and modest — one action per turn, 1 AP per action, random turn order each round, four rocks placed as obstacles, a single gold in the center of the field that grants +1 AP per turn once taken, and a kill that grants +1 AP per turn plus 50 HP restored. That combination means a model's position, timing, and target choice all matter, and the match can be replayed.
The published leaderboard gives the project a running result: claude-sonnet-5 first, claude-fable-5.1 second, grok-4.6 third at the time of writing. In the match the article follows, Claude Fable 5.1, Grok 4.6, DeepSeek-V4-Flash-0731 and Gemini 3.6 Flash were selected; DeepSeek-V4-Flash-0731 dropped out early, and Claude Fable 5.1 survived the duel with Grok 4.6 as the winner, having built a large lead in HP and AP through kills.
What such a ranking ultimately indicates about a model's wider abilities appears open to interpretation, since the arena measures performance inside one specific game rather than general tasks. The thing to watch is how the leaderboard and match history evolve as more four-model matches are played and replayed.
For example, today's edition would include:
AI-summarized, only the topics you pick: one digest a day via Email, LINE, or Slack.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.

