What happened
In a test run against Katz's Delicatessen on Google Maps, Yelp and Tripadvisor, a 01:20 read surfaced a Google review posted at 14:54 UTC that an earlier 16:19 UTC pull of 100 reviews had missed, per EveryInfra API responses.
Why it matters
A nightly job that trusts posting times alone would permanently skip a review that was already live before the previous read, so the report could undercount new low-star complaints.
Summaries like this, every morning.
The test used two public restaurants as samples: Katz's Delicatessen on the Lower East Side, with a 4.5 rating and 56,460 Google reviews, and Haidilao Hot Pot in Flushing, Queens, with a 4.8 Google rating and 8,792 reviews. The nightly cadence is driven by volume: Katz's latest 100 Google reviews covered 3.97 days, or about 24.7 reviews a day, while the latest 50 covered only 1.80 days, with 29 posted in the prior 24 hours. A weekly job would need four Google pages per store and would deliver its oldest low-star review six to seven days late, whereas a nightly job reading 50 reviews covers the prior night with a day of headroom.
The cost picture splits between the API and the model. A single store's four nightly calls cost $0.005556, but model token fees dominate: with Sonnet 5.5, estimated model cost is more than 10 times the API cost. The recommended setup therefore filters raw responses down to 1–2 star reviews with a sandbox script before the model reads them, and uses HTTP with an environment-variable credential rather than remote MCP, whose 100,000-character response cap was exceeded by a 105,266-character Google response for 100 reviews.
Operational details shape the design. Scheduled deployments launch with up to 9 minutes of jitter, each run gets its own budget ($0.50 in the example) that is not a monthly cap, and missed triggers are not backfilled. Sandbox files are wiped between sessions, so the list of seen review IDs must live in a memory store, and MCP toolsets default to always_ask, which would stall an unattended night session. The test also found that 6 of 10 low-star Google reviews for Katz's were non-English and that all 10 owner replies were sent in a 22-minute batch, 9 of them to 5-star reviews.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Bay AI Inc. launched with $50 million — a $37 million Series A led by Battery Ventures and a $13 million seed…
Kora Systems, led by Cyanogen co-founder Kirt McMaster, unveiled a Linux-based desktop OS that runs AI models…
Google unveiled TPU 8tx, built with AMD for confidential training and inference, and TPU 8i Max, which combine…
Anthropic will offer 825 million Class A shares at $70 to $78 each, raising $57.75 billion to $64.35 billion…
IPROS announced five free 20-minute sessions at AI-Industry World 2026, covering Microsoft 365 Copilot, busine…
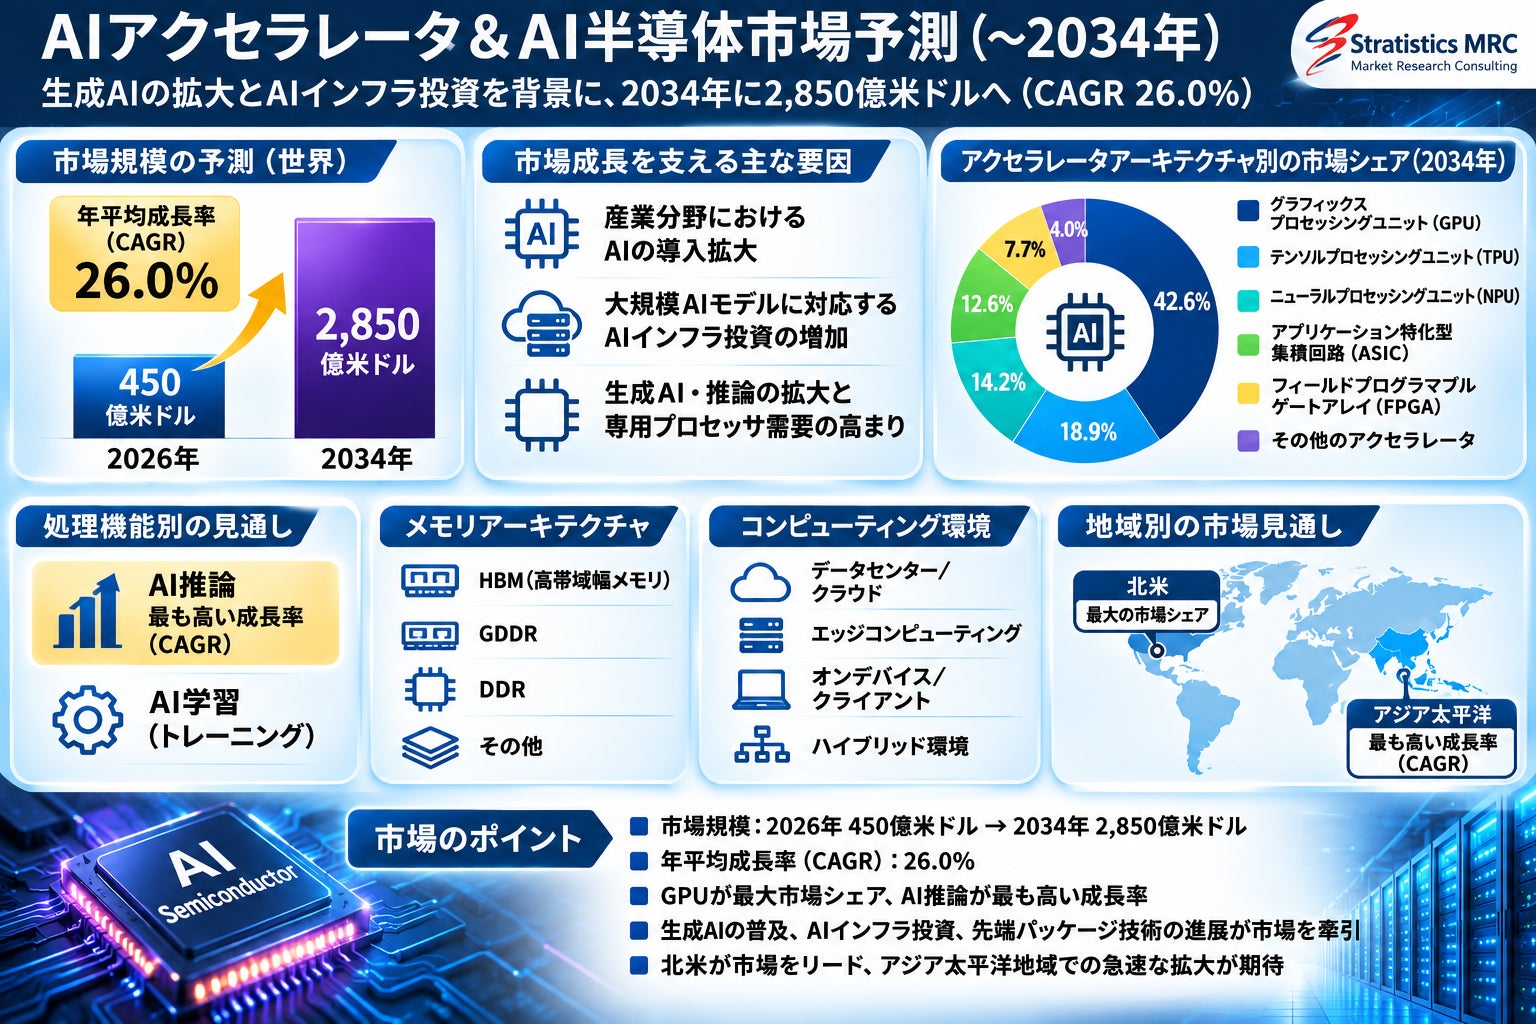
Stratistics MRC forecasts the AI accelerator and AI semiconductor market will reach $285 billion by 2034, up f…