What happened
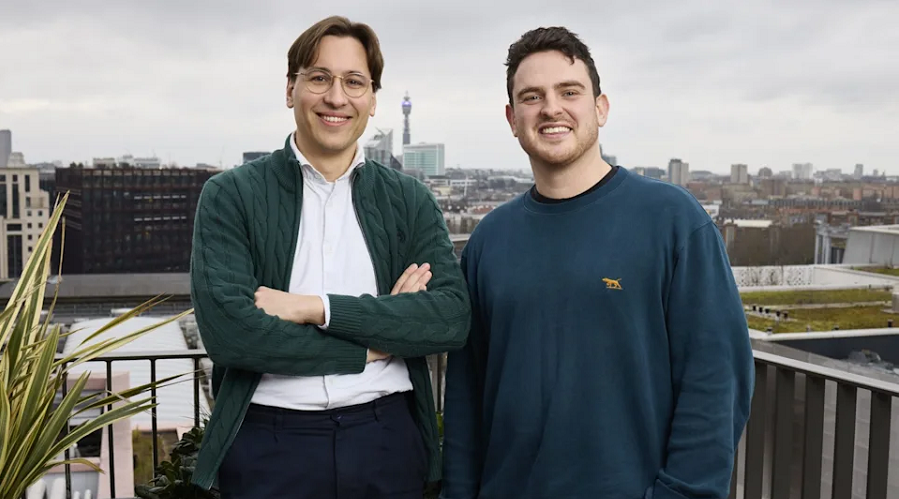
London-based Callosum announced a $100 million funding round led by Atomico, with participation from Plural, DCVC, and the U.K. Sovereign AI Fund. This follows a $10.25 million raise in February. The company offers Tailored Inference, a cloud service that routes AI inference tasks to the most efficient models and hardware.
Why it matters
Callosum's technology completes some inference tasks 3.7 times faster than GPT-5.6 Luna while improving output quality and reducing infrastructure costs. By breaking tasks into modular blocks and assigning each to the best-suited AI model and chip, the platform addresses a core bottleneck in AI deployment—how to orchestrate compute intelligently rather than simply adding more capacity, as CEO Danyal Akarca put it.
What to watch
Cerebras Systems announced a partnership to integrate its WSE-3 Turbo wafer-size inference accelerators into Tailored Inference. The CS-4 rack appliance (powered by three Wafer-Scale Backpacks) can run models with 10 trillion parameters and is particularly suited for the decode phase of inference, complementing prefill-optimized chips from AMD and AWS that Callosum's platform also supports.
Summaries like this, in your inbox every morning.
Callosum enters a market where the efficiency of AI compute deployment has become a competitive differentiator. The company's funding—$100 million in this round alone, atop a $10.25 million seed—reflects investor confidence that AI workload optimization will unlock significant value as organizations struggle with the rising cost and power demands of large-scale inference. The partnership with Cerebras is particularly noteworthy because it demonstrates that chip makers themselves recognize the need for software orchestration layers; Cerebras' announcement of the WSE-3 Turbo on the same day signals that hardware innovation alone is insufficient without intelligent routing of workloads. The focus on the decode phase of inference—where models generate responses token by token—points to a specific bottleneck that both companies see as ripe for optimization, especially as enterprise deployments scale beyond initial experiments.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
In Q2, billionaires or their funds sold six 'Magnificent Seven' AI stocks

Nvidia was rising early Friday, even as the wider chip sector kept falling, Barron's reported

TSMC reported about NT$763.1b in Q3 net profit and confirmed that demand for advanced processors is running ah…

Nvidia-backed CoreWeave steadied Thursday after a sharp slump, as investors worried about the debt financing b…

CoreWeave, a fast-growing Nvidia-backed cloud provider, saw its stock and bond prices fall sharply in a sell-o…
Broadcom introduced VMware HyperArmor for VMware Cloud Foundation and showcased high speed AI networking with…