What happened
Google Research on 2026-09-24 presented four studies — Co-Director, CANVAS, A²RD and VQQA — in which a director agent, visual memory, segment-by-segment generation and a critique agent work as a crew; A²RD reported consistency gains of up to 30% over existing methods.
Why it matters
Rather than asking one model to produce a multi-minute video in a single pass, the work treats long-form AI video as a production pipeline where roles share goals and state, which the authors report improves consistency — a claim based on their own benchmarks and human evaluation, not independent third-party testing.
WHO IT HITSVideo creators and studios experimenting with AI-generated multi-minute narratives are the most directly affected, since the research targets the character, set and prop drift that appears when clips stretch beyond a few minutes. Teams building internal content pipelines may also draw on the split-roles design, though no product is available yet.
Summaries like this, every morning.
The starting problem is specific: short AI clips look polished, but stretch them to a few minutes and the same character's clothes change, room layouts shift, and props turn into different objects. Google Research's answer, presented on 2026-09-24, is not a bigger single model but a division of labor modeled on film production. Each of the four studies covers a different role rather than one integrated product pipeline.
The design choice that ties them together is shared state. Co-Director has an orchestrator set the overall direction and share it with pre-production, keyframe, video and audio agents, with a multimodal LLM reviewer feeding its assessment back into the next generation loop. CANVAS maintains appearance, location structure and prop state as persistent visual memory, while A²RD extends footage in a closed loop of retrieve, generate, improve and update memory. VQQA avoids editing pixels directly; it generates questions about the footage and turns the answers into prompt adjustments, selecting the best candidate against the original instructions instead of accepting the final version unconditionally.
The authors' reported numbers — up to 30% better consistency and up to 20% better narrative coherence for A²RD, plus benchmark gains for VQQA — come from their own benchmarks and human evaluation, so they should be read separately from independent third-party validation. The official page lists no consumer API, pricing, regions or start date, and the four underlying papers were submitted to arXiv between March and May 2026. The practical takeaway the researchers' design suggests is separating planning, production and evaluation, and carrying state as external memory on long tasks.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Since late October, users of OpenAI's paid plans have reported Codex and ChatGPT Work burning through usage qu…
AgeAI, led by CEO Gen Mikami, joined the Gotanda Valley Acceleration Program 2026 from its September 17 kickof…

HTC NIPPON starts domestic pre-orders for VIVEE on 2026年11月20日(金) via its official online store and Amazon, wi…
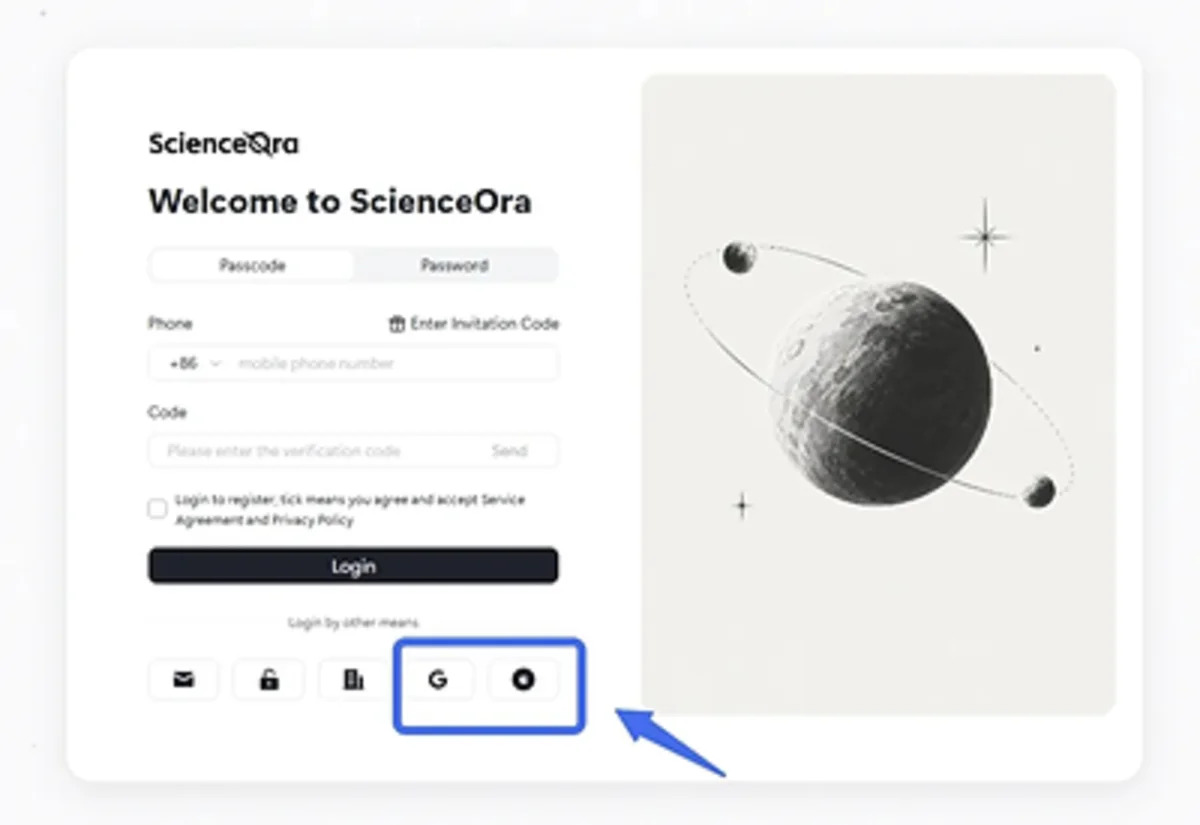
Wenge AI (1956.HK) added Google and Apple sign-in options to ScienceOra's international site, letting users au…
Jane Street published socratic-tutor, a 102-line text file in its agent_skills repo, on 2026年11月3日; a test on…
The Information reported that Meta's Muse Charm AI device will cost around $300, and a Meta spokesperson did n…