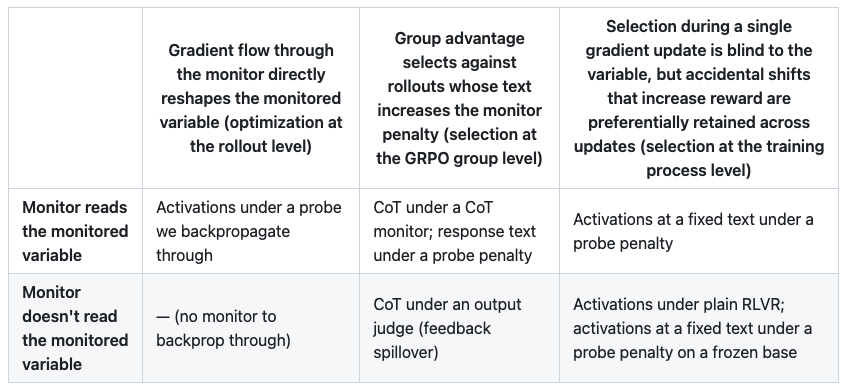
Goodfire announced a private beta of Silico, an LLM training platform, and published a post describing how it reproduces RLFR—a method developed by Goodfire that uses probes as reward signals for reinforcement learning (RL). The announcement prompted Twitter commentary claiming the technique implements what was called the "Most Forbidden Technique" in a classic LessWrong post on the risks of training signals that use model internals.
Summaries like this, in your inbox every morning.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
A Qiita article compared automated red-teaming methods for LLM apps — GCG, PAIR, and TAP — using mock implemen…

In a webinar hosted by French Mathematical Society president Isabelle Gallagher, Fields Medal winner Hugo Dumi…
Anthropic said on October 15 it has started giving METR's six staff company devices, office space and access t…

NVIDIA published a blog post titled "AI Security Is an Engineering Problem - How to Solve It at Every Layer of…

At the Most Powerful Women Summit, Marissa Mayer said anyone who claims to know how AI will play out is 'eithe…
After its first meeting Thursday, the White House AI task force formally adopted its charter, opening a 120-da…