What happened
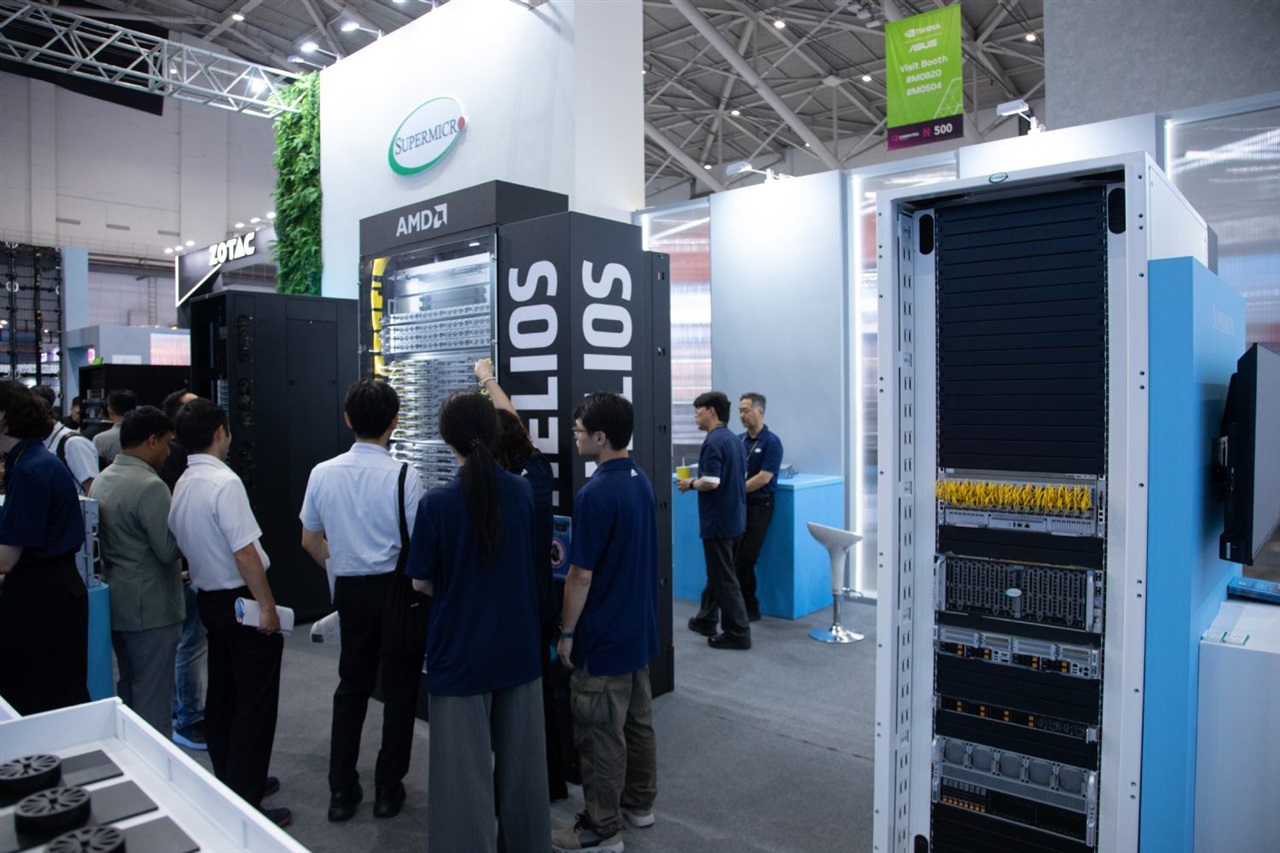
DIGITIMES estimates global AI server shipments will exceed 2.5 million units in 2026, including 2.37 million high-end AI servers equipped with HBM, up 56% from 2025 and accounting for over 15% of total server shipments for the first time.
Why it matters
High-end AI servers are growing faster than the overall server market and are for the first time set to surpass 15% of total server shipments, as cloud providers and AI labs accelerate data center buildouts.
What to watch
TPU-based servers will remain the largest non-GPU segment but their shipment share is expected to decline from 2025 due to a high comparison base and more severe supply constraints in 2026. Watch whether Nvidia's GB300 NVL72 shipments stay smooth enough to keep GPUs near 60% of high-end AI servers.
WHO IT HITSCloud providers, AI labs and server suppliers will need to plan for significantly higher high-end AI server volumes in 2026, with supply constraints in TPU-based systems potentially affecting procurement strategies.
Summaries like this, in your inbox every morning.
The forecast comes as top-tier LLM capabilities continue to advance and agentic AI promises to automate business processes. This is prompting major North American cloud providers, Neo Clouds, and leading AI labs to accelerate their AI data center buildouts in 2026.
Within the high-end segment, GPUs are expected to account for nearly 60% of shipments, helped by smoother shipments of Nvidia's GB300 NVL72 compared with its predecessor. TPU-based servers will remain the largest non-GPU segment, but their share is set to decline from 2025 because of a high comparison base and more severe supply constraints in 2026.
The forecast hinges on whether supply conditions, particularly for TPUs, allow shipments to meet demand. If they do, high-end AI servers will for the first time exceed 15% of total server shipments, a milestone that would underscore how central AI has become to data center investment.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Testing Azure API Management's llm-token-limit policy at 800 tokens per hour, actual consumption hit 1,472 tok…

Qwen released Qwen3.8-Flash-Next on August 27, 2026, calling it a preview of the architecture planned for Qwen…
Anthropic's Message Batches API offers a 50% off rate, takes up to 10,000 requests per batch, and returns resu…
A migration writeup lists seven breakages for code moved to claude-opus-5 or claude-sonnet-5, all in the offic…
The author served com-kotobalabs/open-jev-deberta-v3-large on Databricks Model Serving in AWS 東京リージョン, and on…
A hobbyist built a fully from-scratch tiny language model with 573,952 parameters, a 16-token context, and byt…

