What happened
NVIDIA published Nemotron Personas Finance Japan and Nemotron PII Japan on Hugging Face, built with cooperation from major Japanese financial institutions.
Why it matters
The synthetic data lets companies build Japanese AI agents without using real personal information, easing privacy constraints in finance and other sensitive sectors.
WHO IT HITSJapanese AI developers, especially in finance, healthcare and public-sector teams that cannot easily use real personal data, can train and evaluate agents on synthetic records instead, according to NVIDIA.
Summaries like this, every morning.
NVIDIA positions these datasets as part of Nemotron, its system for building and deploying AI agents at lower cost while balancing accuracy and compute efficiency. The release addresses a practical obstacle: AI agents need to reflect a country's language, culture, demographics and industry conditions, but personal data is hard to obtain, use and share because of privacy and security concerns, especially in finance, healthcare and the public sector.
Nemotron Personas Finance Japan builds on Nemotron Personas Japan, keeping its basic attributes and personal context while adding finance-specific traits such as income and assets, so that spending, saving, investing and financial decisions can be represented more realistically and diversely. NVIDIA says the dataset draws on public demographic and labor statistics released in 2025 and was created with cooperation from major Japanese financial institutions.
Nemotron PII Japan complements that by supplying documents with annotations showing where personal identifiers sit and which category they belong to. Because documents and correct labels are provided together without any real personal information, teams can fine-tune, evaluate and improve detection and masking models, which may make it easier to build Japanese AI agents that meet local and industry requirements.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Bay AI Inc. launched with $50 million — a $37 million Series A led by Battery Ventures and a $13 million seed…
Kora Systems, led by Cyanogen co-founder Kirt McMaster, unveiled a Linux-based desktop OS that runs AI models…
Anthropic will offer 825 million Class A shares at $70 to $78 each, raising $57.75 billion to $64.35 billion…
Google unveiled TPU 8tx, built with AMD for confidential training and inference, and TPU 8i Max, which combine…
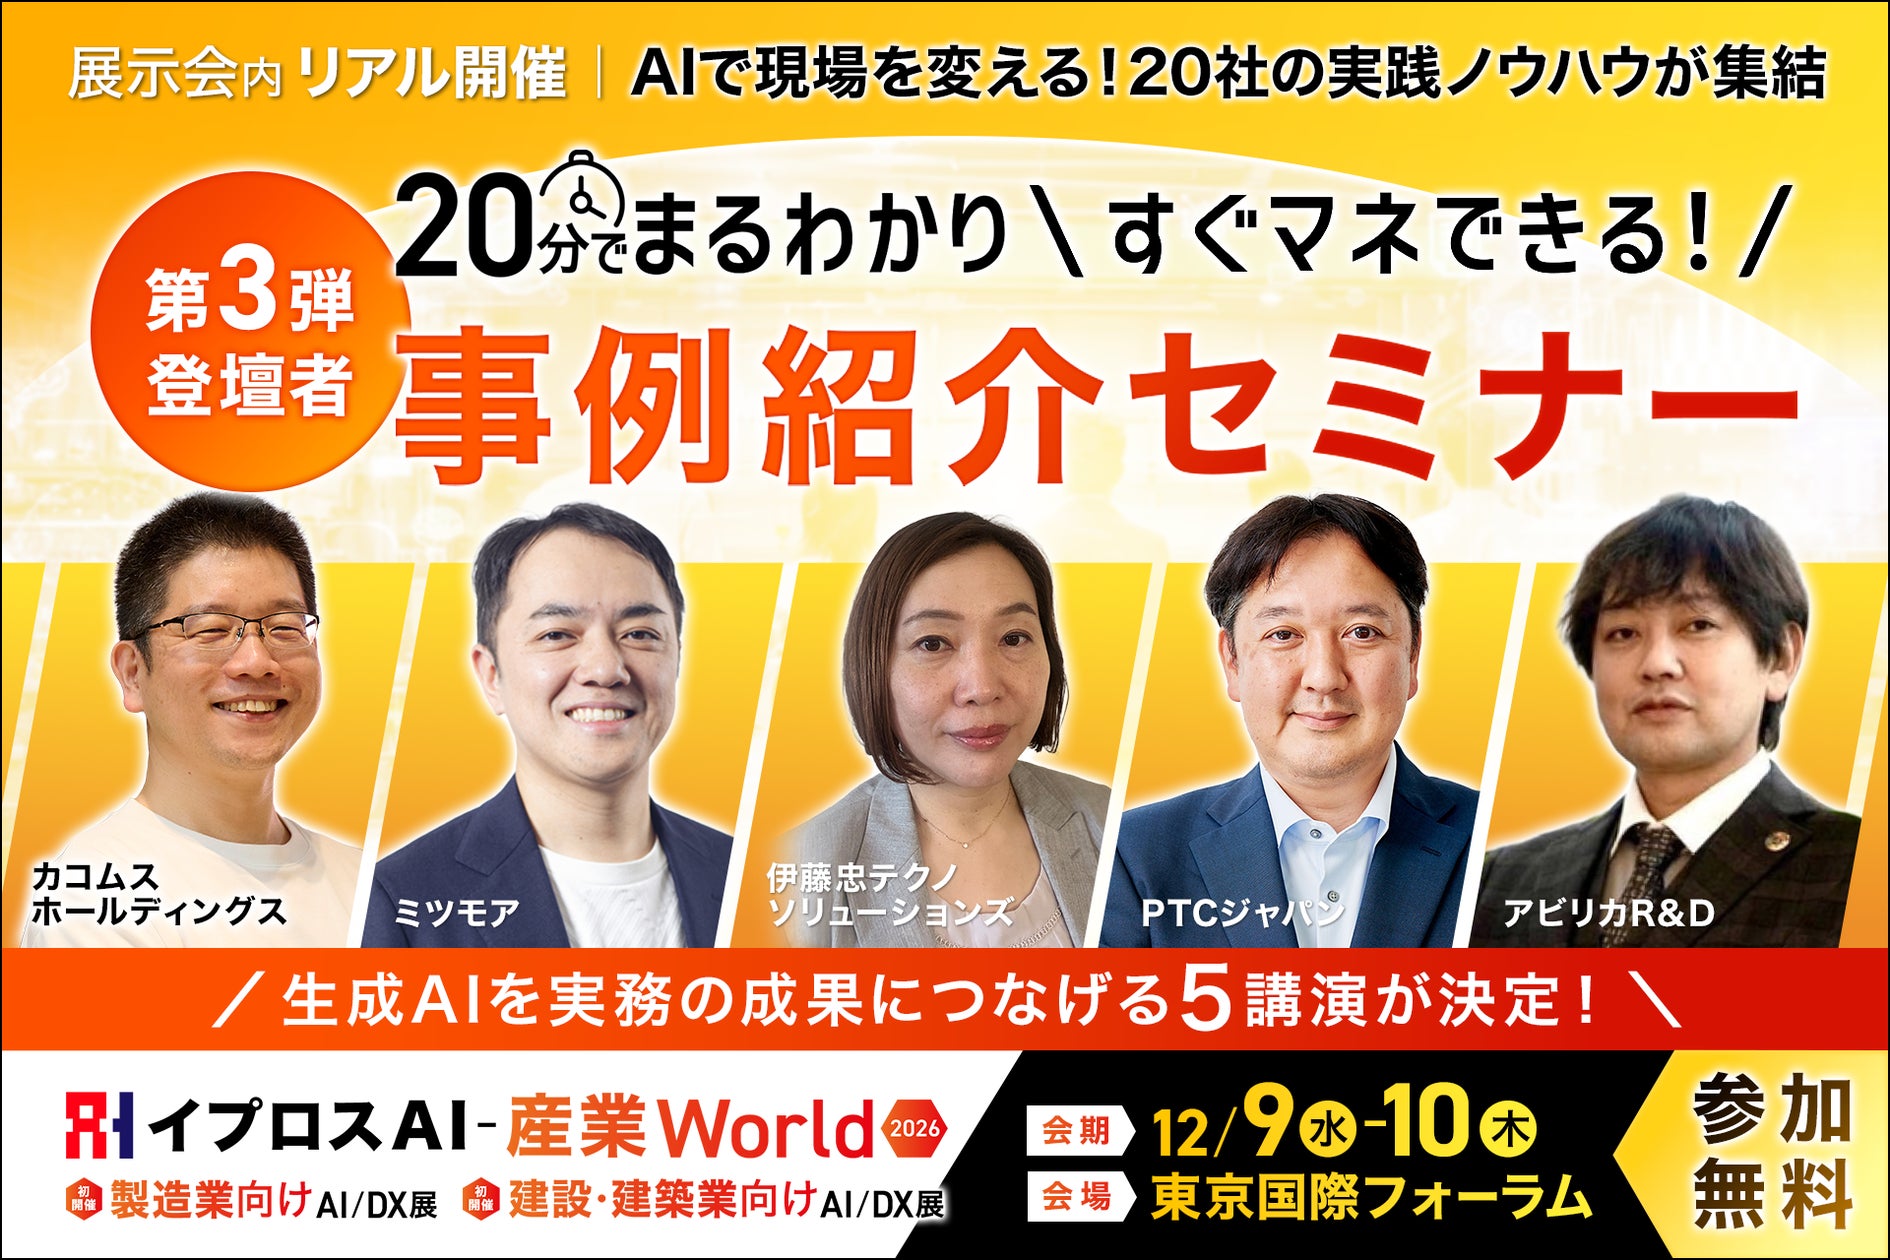
IPROS announced five free 20-minute sessions at AI-Industry World 2026, covering Microsoft 365 Copilot, busine…
Stratistics MRC forecasts the AI accelerator and AI semiconductor market will reach $285 billion by 2034, up f…