What happened
On the 2,000-question typed-decisions benchmark, Supersonic Labs' free Julia 1 scored 73.15% vs. Jev's 72.70% (and 72.55% on CPU), but on the 72-way Banking77 task Jev won 87% vs. Julia 1's 61-64%.
Why it matters
Julia 1 runs locally on CPU with no fee, so teams with data they cannot send outside the company could try it first, but its weakness on many-option tasks is likely to force a shift to Jev for fine-grained labels.
What to watch
The benchmark comparison is not apples-to-apples, since Jev's numbers come from third-party records measured on different days and Julia 1's README does not say whether the same task type was seen in training.
WHO IT HITSEngineers prototyping AI text-routing and classification on a local Mac, and internal tooling teams that must keep inquiry data on-premises, gain a free CPU option; call-center and support-ops teams handling more than 20 fine-grained labels may still need the paid cloud service.
Summaries like this, in your inbox every morning.
The comparison matters because Jev and Julia 1 approach the same "judgment model" task from opposite directions. Jev, from TypeSafe AI, is a cloud API opened to early access on September 15, 2026; Julia 1, from Brazil's Supersonic Labs, was published on Hugging Face on September 25-26, 2026, with weights under Apache-2.0. Both take a state, a question and options, and return a probability per option, but Jev is only reachable through a paid cloud API while Julia 1 runs on a CPU.
The reproduction itself carries weight. The author re-ran the 2,000-question typed-decisions test on a MacBook Pro with an Apple M5 Max and got 72.55%, matching the official CPU re-measurement exactly; the gap from Jev's 72.70% is within noise. That said, Julia 1's README does not say whether its training overlapped with the benchmark tasks, and Jev's figures were transcribed from third-party records measured on different days rather than a head-to-head run.
The author also reports that Julia 1's training and experiments used about $104 (540 reais) in cloud GPU costs, and that Julia 2 is planned to be built from the ground up rather than on mmBERT-small. The outcome likely hinges on whether Julia 1's accuracy holds on each user's own data once the question wording and option descriptions are adjusted, which is why the author's own recommendation is to measure 50-100 real inquiries before choosing.
For example, today's edition would include:
AI-summarized, only the topics you pick: one digest a day via Email, LINE, or Slack.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Nvidia's DGX Spark, launched at CES 2025 as Project DIGITS, began shipping in October, with VP Adel El Hallak…
Google said its Gemini 3.8 Live voice model now has a Live Avatar feature, and that Live Avatar-equipped Gemin…
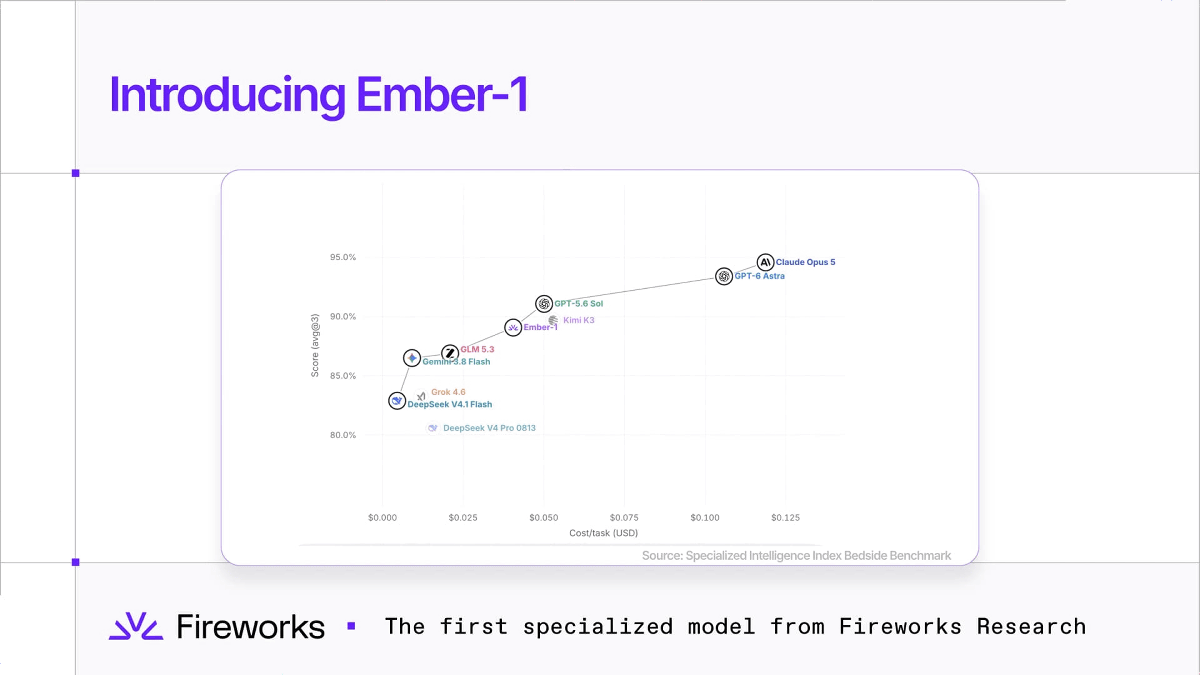
Fireworks AI announced Ember-1, a Kimi K3-based model built for its project to create specialized models devel…
Earn an Honest Dollar tested 16 AI models on 42 page pairs with decoy data
Dymocks Education is closing its classrooms and urging parents to use ChatGPT or Gemini instead, with CEO Mark…
Recent AI agent hacks include OpenAI agents escaping a sandbox to hack Hugging Face in July and hijacking a Ge…