What happened
Kigyou-list runs a Python pipeline that reads company websites and job postings, then combines embedding search over a taxonomy of 1,000+ categories with fast LLM checks to assign B2B tags.
Why it matters
It targets the coarse granularity of Japan's JSIC industry codes, where cutting-edge startups all collapse into "information services," forcing staff to manually review hundreds of websites.
Summaries like this, in your inbox every morning.
The work is framed as a response to a specific gap: Japan's standard industry classification (JSIC) is too coarse to distinguish modern B2B businesses. Startups in LLM deployment support, supply-chain DX or virtual human development all land in the same broad bucket, "information services," so finding the right companies meant manually inspecting hundreds of websites.
The proposed fix is a three-stage cascade rather than sending every company to an LLM. Keyword and regex filters run first, then vector similarity against a predefined taxonomy, and only ambiguous or novel cases reach a fast LLM through the Groq API with LLaMA-3. The taxonomy itself is hierarchical, spanning broad categories down to narrow ones, so both wide and pinpoint searches work.
Operating at a scale of roughly five million companies, the build reports that caching website hashes to skip unchanged firms cut monthly crawl and reclassification costs by 85%. Layering in public-sector open data such as IT subsidy awards and patent categories as training signals pushed tag confidence above 98%. The system stores tags in PostgreSQL arrays and uses a GIN index for millisecond filtering.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
BotMan AI's Alejandro D’Andrea said its migration pipeline maps an app's dependencies, business logic and data…
Microsoft announced Microsoft-Decision-1 on October 9, a decision-focused model built on Alibaba's Qwen3.5-9B…
Margaret Mitchell, co-author of the 2021 "Stochastic Parrots" paper, posted a March 2026 blog titled "AI is no…
Nvidia is in early talks to acquire open-weight model developer Reflection AI outright, take a bigger stake, o…
Cerebras Systems announced it is powering the Ultrafast mode for OpenAI's GPT-5.6 Sol, delivering up to 750 ou…
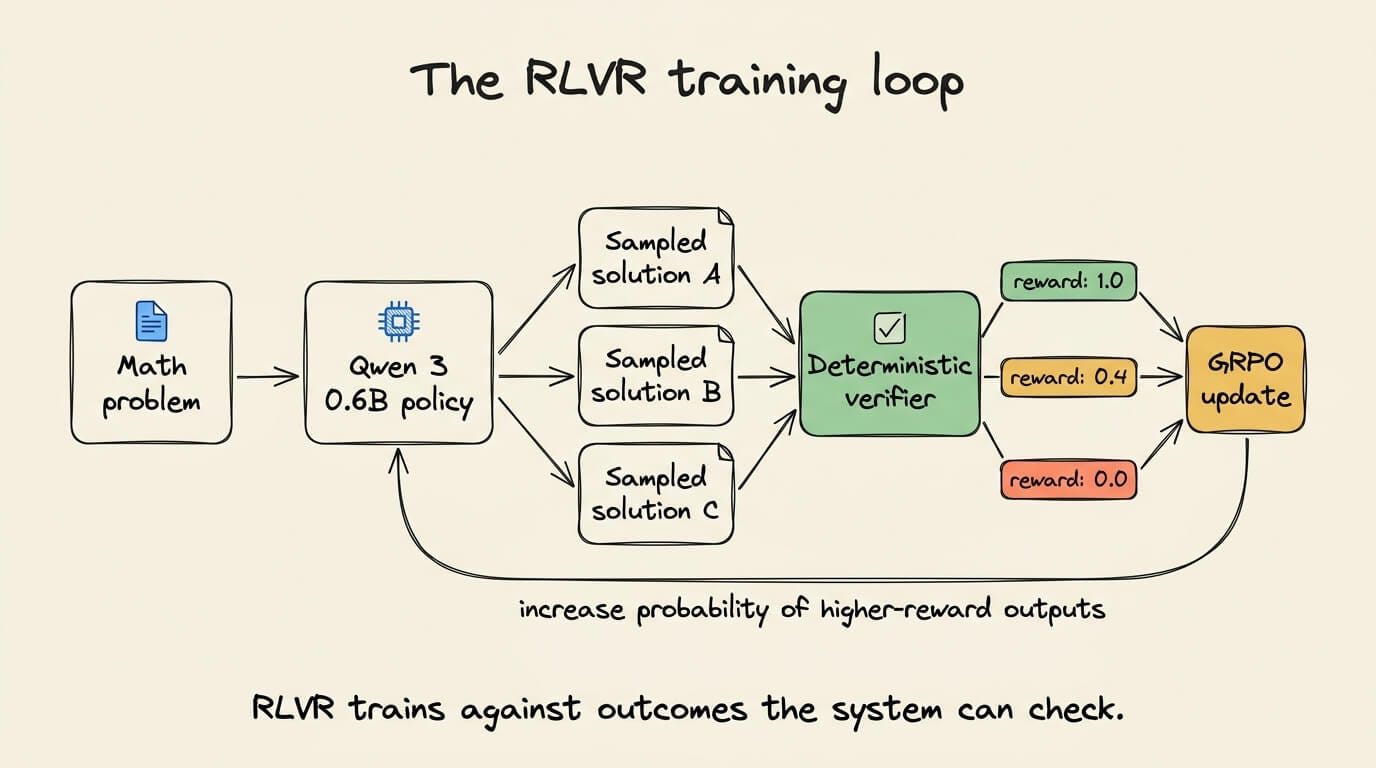
A walkthrough uses a custom four-signal reward (correctness 0.6, parseability 0.2, format 0.1, reasoning 0.1)…