What happened
MCPMark V2 benchmarks showed that production LLMs achieve 54% higher token usage when reasoning through backend tasks, not because the models are less efficient but because they must discover system state that isn't handed to them cleanly. When an agent built a full-stack RAG app on Supabase, it consumed 10.4M tokens and required 10 manual interventions; the same app on InsForge (an agent-optimized open-source backend) consumed 3.7M tokens and completed without errors.
Why it matters
Most backends were designed for human developers using dashboards, so they return overly broad information (Supabase's OAuth docs include 5–10× more tokens than needed) and ambiguous error codes that force agents into retry loops. A smarter model tries harder to fill these gaps—triggering more discovery queries and reasoning—which is why token cost rises with a better Claude. The real fix is not a better model but a backend designed with agents in mind, offering structured context upfront and semantic exit codes.
What to watch
InsForge demonstrates the agent-first approach—a single CLI call returns the full backend topology in ~500 tokens before coding begins, with four narrowly scoped skills (CLI, debug, SDK, integrations) that activate only when needed. The GitHub repo has 14k+ stars. For teams building agent systems, this suggests that optimizing inference-time reasoning alone ignores the infrastructure gap: agents need backends that anticipate their information needs.
Summaries like this, in your inbox every morning.
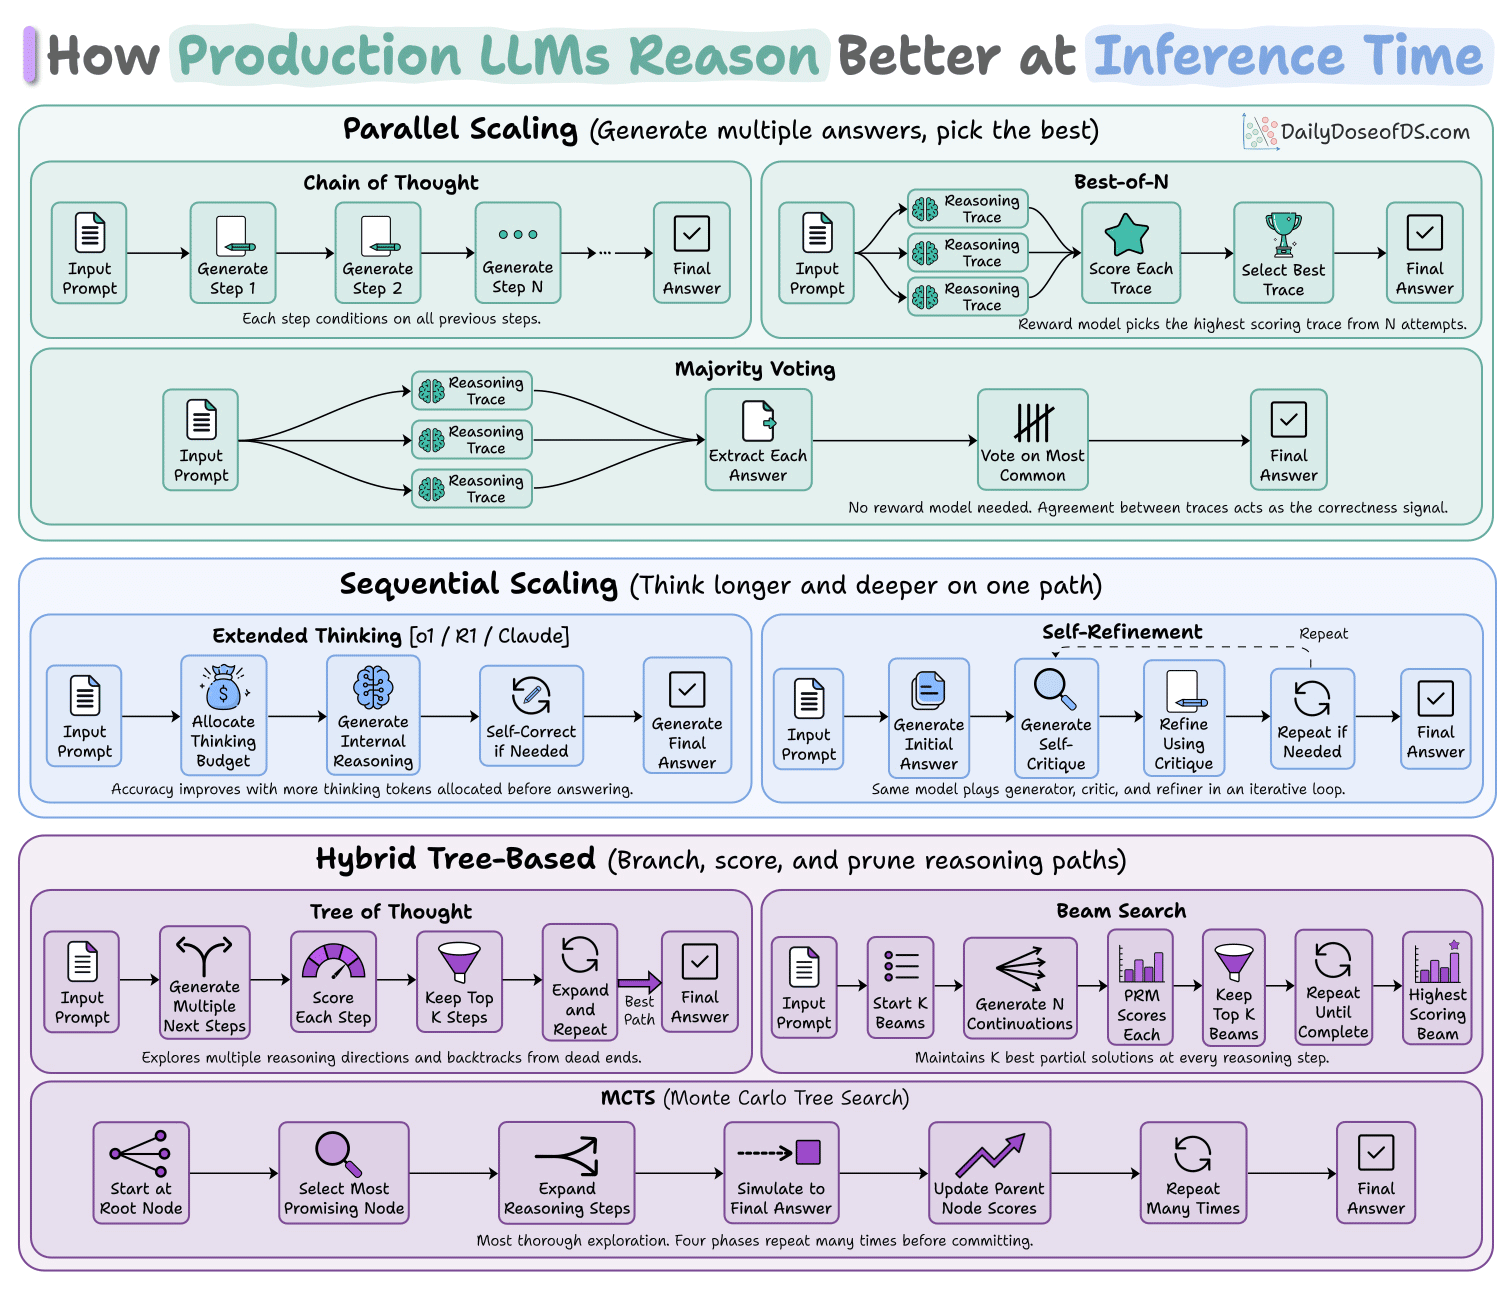
The article reveals a counterintuitive cost dynamic in inference-time reasoning: smarter models don't always mean cheaper inference. The culprit is architectural—most backend infrastructure (like Supabase) was built for human developers who can read dashboards and interpret errors, not for autonomous agents that must query for every piece of context. When a better LLM encounters missing information, it doesn't give up; it reasoning harder, runs more discovery calls, and enters retry loops when error codes are ambiguous. This behavior is rational from the model's perspective but expensive from the user's.
The token-cost spike from 3.7M to 10.4M in the same full-stack task demonstrates that the problem is not model intelligence but information design. InsForge's approach—returning the entire backend topology in a single ~500-token CLI call, using structured JSON, and assigning semantic exit codes—removes the discovery overhead. The agent's cognitive load stays lean because it only loads the skills it needs (CLI for table creation, debug for code failures, SDK for frontend, integrations for third-party auth), and it never faces ambiguous 401 errors that could mean three different things. This suggests a broader lesson: as inference-time reasoning becomes standard, teams will face diminishing returns from model scaling alone and must instead optimize the infrastructure agents operate on.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Circlia started a proof-of-concept for TASTE SIGNAL: visitors to Holland Village Cafe FUKUOKA taste cookies an…

In a webinar hosted by French Mathematical Society president Isabelle Gallagher, Fields Medal winner Hugo Dumi…

NVIDIA released Nemotron 3.5 Super VL, an open-weight model with 120 billion parameters that handles text, ima…

NVIDIA released Nemotron 3.5 Bolt 74B-A9B 24GB, an AI model for local agents that hits over 80 tokens per seco…

NVIDIA published a blog post titled "AI Security Is an Engineering Problem - How to Solve It at Every Layer of…

In the test, Haiku 5.5 on medium setting averaged scores close to Sonnet 5.5 on routine documents at about 1/1…


