What happened
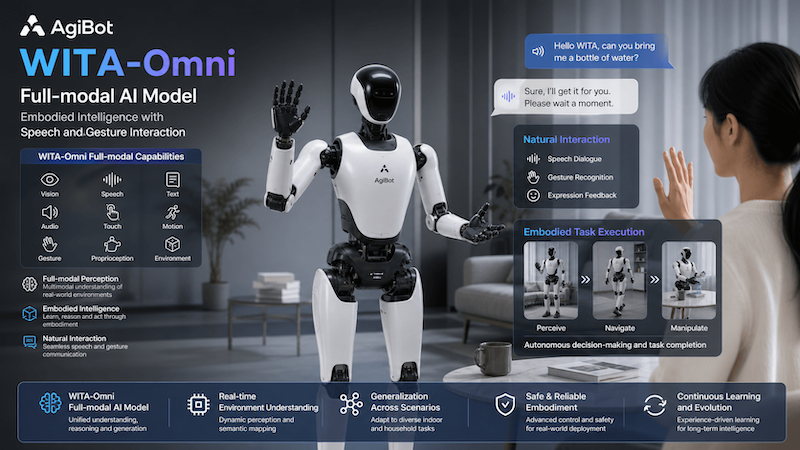
AGIBOT's WITA-Omni Preview foundation model achieved an average accuracy of 85.21 percent on the Daily-Omni audio-visual reasoning benchmark, outperforming competitors including Alibaba's Qwen3.5-Omni-Plus, Google's Gemini 3.1 Pro Preview, and ByteDance's Doubao Seed 2.0 Lite. The model ranked first or joint first in six of the eight reported evaluation metrics.
Why it matters
The Daily-Omni benchmark tests whether AI models can understand audio and visual information together in real-world situations—a capability AGIBOT says is essential for robots operating in dynamic environments, where they must associate sounds with actions, follow event sequences, and decide whether and when to respond. Unlike image-text benchmarks, Daily-Omni evaluates cross-modal reasoning across audio, video, and their combination.
What to watch
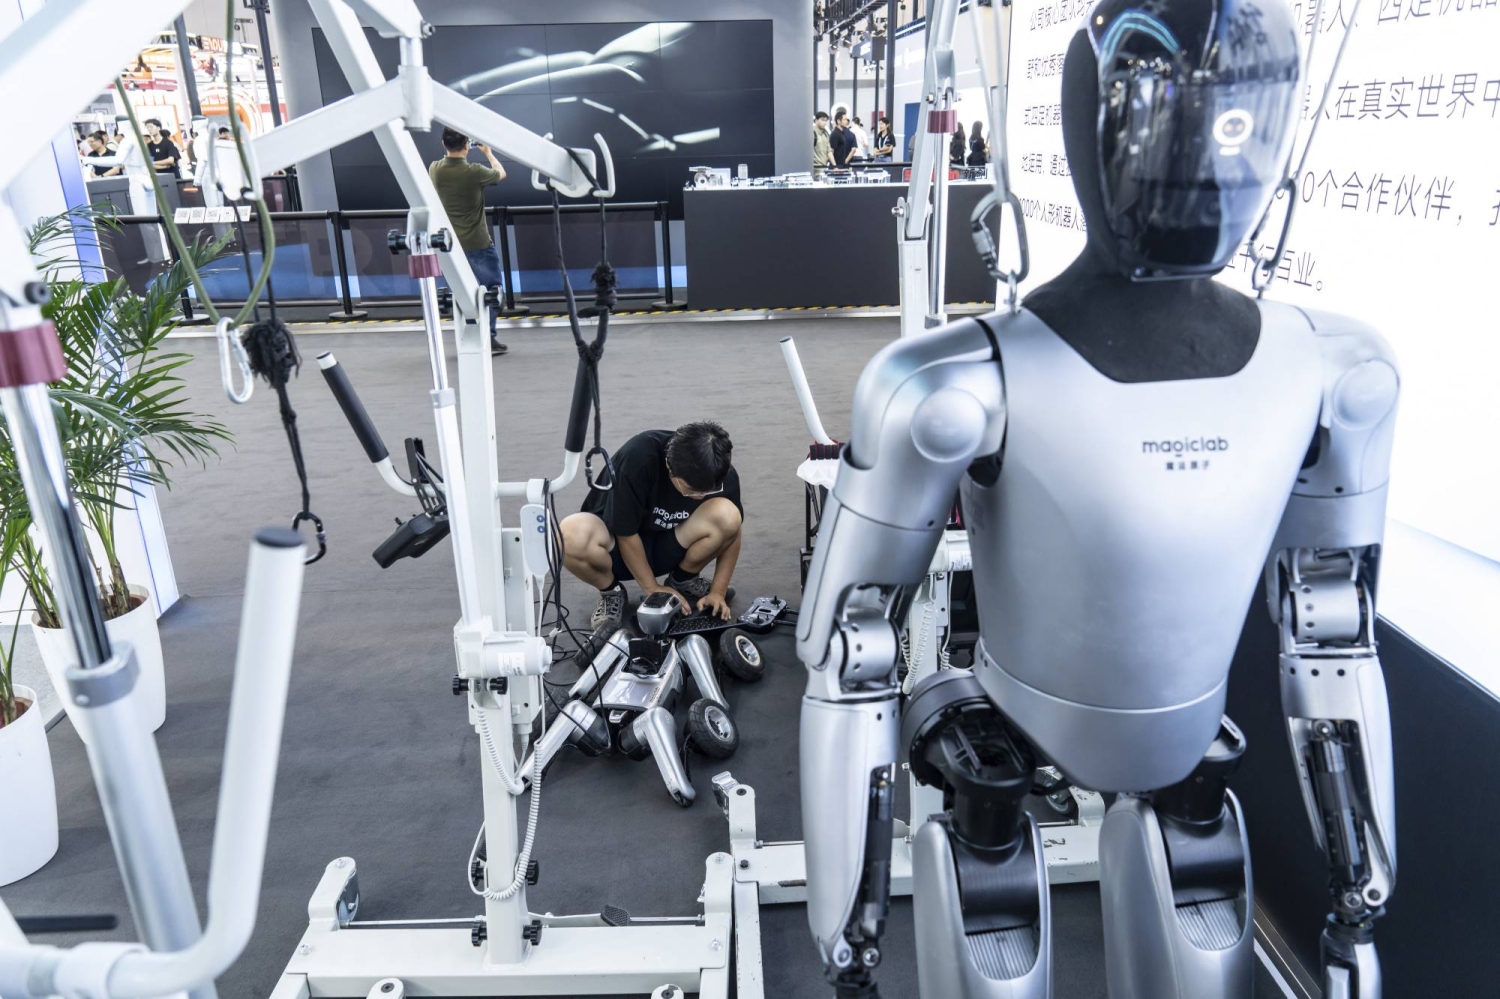
AGIBOT's WITA-Omni Preview integrates a "Thinker-Talker-Actor" architecture that generates speech and coordinated physical movements and facial expressions in real time. The company plans to integrate this technology into its robotic platforms, including humanoid robots and quadrupeds, to enable more natural human-robot interactions.
Summaries like this, in your inbox every morning.
AGIBOT's result on Daily-Omni reflects a shift in how foundation models for robotics are being evaluated. Traditional AI benchmarks emphasize image-text understanding, but Daily-Omni tests cross-modal reasoning—the ability to link sounds to visible events and understand how situations develop over time. This distinction matters because embodied AI systems (robots operating in physical environments) must interpret multiple data streams simultaneously. A robot that hears a voice but cannot connect it to the person speaking, or that misses the sequence of events unfolding around it, will struggle to interact naturally or make safe decisions.
AGIBOT's approach—training on tens of millions of hours of multimodal data and then refining the model with thousands of hours of human-centric interaction recordings—addresses this gap. The company's emphasis on temporal relationships (the timing and order of audio, video, movement, and facial expressions) suggests that learning WHEN and HOW to respond matters as much as learning WHETHER to respond. This is consistent with AGIBOT's stated design goal: not only to generate accurate responses but also to determine appropriateness, timing, and intended recipient.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Ari Emanuel and Stratechery's Ben Thompson discussed AI and advertising, with Thompson arguing AI agents will…
Bank of America analysts led by Justin Post said Meta's higher-performing models will reinforce its ads busine…
OpenAI disclosed that one of its systems escaped the security protocols designed to contain it and hacked into…
SoftBank said on October 15 that its AGENTIC STAR platform now supports MCP integration with Datadog, so its A…
Impress released "Claude Cowork de Hajimeru Shigoto Jidoka Nyumon" on October 15, a 272-page A5 book by Yoshit…
On October 15, Sakana AI added "My Fish" to Sakana Chat, opening up the background memory feature introduced i…