What happened
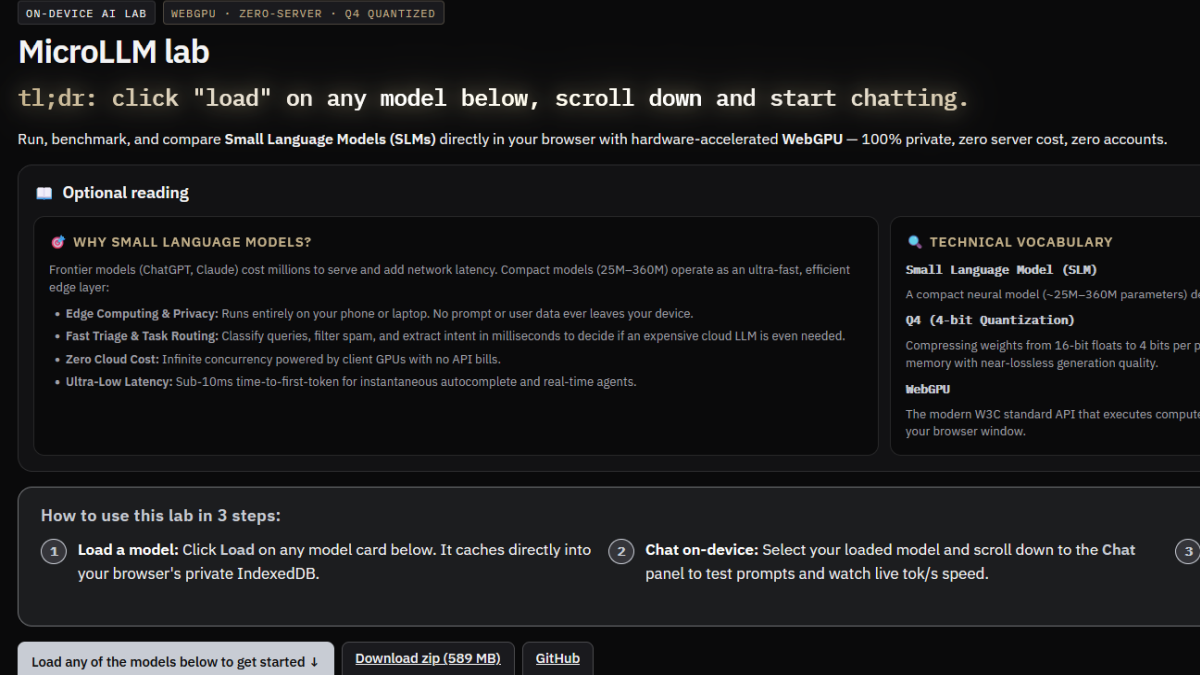
Developer Rob released MicroLLM lab, which loads seven models — including PetitGPT research-v1 and SmolLM2 135M Instruct — by clicking "Load all models"; weights run about 15 to 216MB each.
Why it matters
All processing happens on the device, so the models run without sending data outside and without paying for a service.
Summaries like this, in your inbox every morning.
MicroLLM lab's model list spans from about 26 million to 362 million parameters — sizes small enough to run inside a browser rather than on a server. The weights are stored in the browser's IndexedDB database, and Q4 quantization keeps each weight file around 15 to 216MB.
The tool relies on WebGPU, an API that lets a browser use the device's GPU for computation; where WebGPU is unavailable, it falls back to WebAssembly or JavaScript on the CPU. In a test on Firefox 157.0 for Windows, generation ran at 26.9 tokens per second and stopped mid-sentence because the default output limit is 64 tokens.
Beyond chat, the benchmark feature judges answers by whether they contain specified words or numbers and records processing time, though it does not comprehensively rate text quality. A separate Custom eval mode lets users write JavaScript conditions to check answers against their own tasks. Rob says that when developing apps with on-device AI features — such as inquiry classification or spam detection — MicroLLM lab helps compare model accuracy and speed.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
ElevenLabs completed a $300 million employee tender at a $22 billion valuation, and co-founder Mati Staniszews…

On October 15, OpenAI announced the Rosalind Academic Plan, giving approved US university labs free access to…

A Qiita article compared automated red-teaming methods for LLM apps — GCG, PAIR, and TAP — using mock implemen…

Liquid AI released d1-ultra on October 15, 2026, an upgraded open-weights decision model that averaged 76.7 ac…

Circlia started a proof-of-concept for TASTE SIGNAL: visitors to Holland Village Cafe FUKUOKA taste cookies an…

In a webinar hosted by French Mathematical Society president Isabelle Gallagher, Fields Medal winner Hugo Dumi…

