What happened
Hitachi announced on August 25, 2026 a selective re-encoding technology that reduces the average processing time for image data in AI analysis by half while maintaining accuracy, verified using Vision Transformer (ViT).
Why it matters
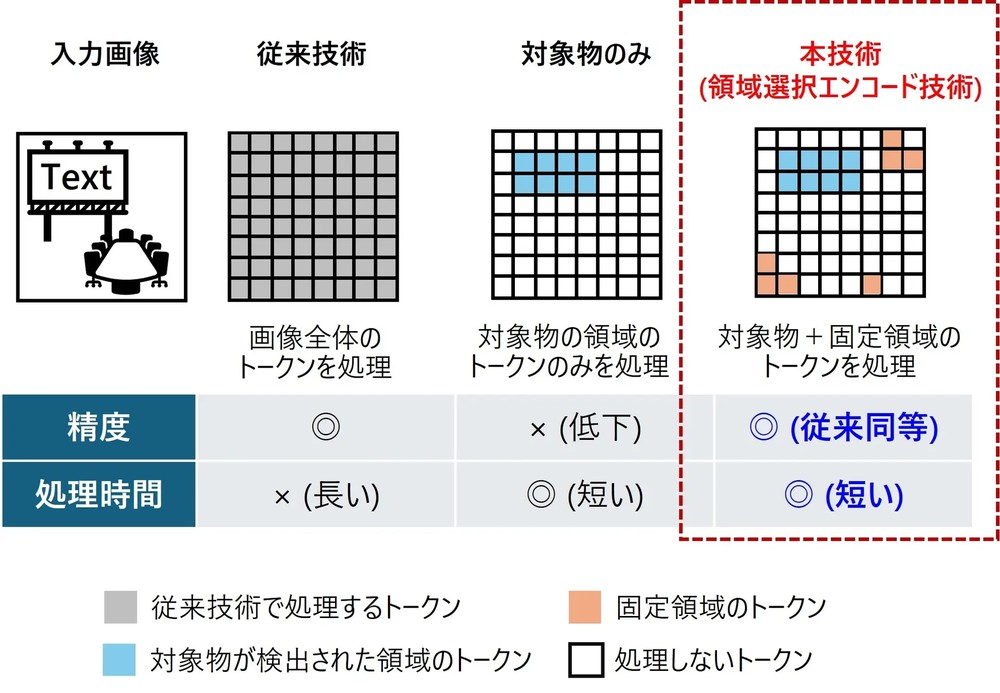
Previously, ViT generated tokens for the entire image, leaving the processing time and computational load as a major challenge; the new method re-encodes only the tokens corresponding to regions deemed necessary, cutting token counts and halving processing time.
What to watch
The value of the technology will be tested in real-world use cases, starting with image and video recognition AI, toward application to AI and social infrastructure; watch for deployment linked to Hitachi's AI strategy 'Lumada 3.0'.
WHO IT HITSEnterprise AI teams deploying image and video recognition, especially in OT (operational technology) fields such as defect detection and equipment abnormality monitoring, may benefit from reduced GPU and other computational resource requirements.
Ask the AI about this article →
Summaries like this, in your inbox every morning.
Hitachi's announcement on August 25, 2026, centers on a technical bottleneck that has long affected image analysis with AI: Vision Transformer (ViT) models generate tokens for the entire image, which increases processing time and computational load. The new selective re-encoding technology addresses this by identifying which regions of the image contribute to fixed regions in the model's internal representation, and re-encoding only the tokens corresponding to those regions. This approach allows the system to maintain accuracy while reducing the number of tokens it must process.
The company verified the effect through trial calculations assuming image analysis, finding that the average processing time was halved while accuracy was maintained. This is particularly relevant for OT (operational technology) fields that use large amounts of image and video data, such as defect detection in manufacturing or abnormality monitoring from surveillance camera footage, where reducing GPU and other computational resource requirements could enable more efficient AI deployment.
Hitachi says it will now evaluate the technology's value in actual use cases, starting with image and video recognition AI, and expand application to AI and social infrastructure, linked to its AI-driven strategy plan 'Lumada 3.0'. The outcome hinges on whether real-world deployments can replicate the trial results and whether the approach integrates smoothly with existing infrastructure. For teams managing image-heavy AI workloads, the promise of halved processing time could ease resource constraints, though the full impact will depend on adoption and scaling beyond the initial verification.
For example, today's edition would include:
AI-summarized, only the topics you pick — one digest a day via Email, Slack, or Discord.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. Q&As are published on this page for other readers too.
A Korean office worker wrote on the community "リメンバー" that he asked ChatGPT about chest tightness and breathin…
Fortinet acquired Virtue AI, a move aimed at extending its AI security and strengthening real-time protection…

SCREEN and Lasertec both fell to lower revenue and profit in their latest fiscal years, but now forecast reven…
Lowe's Senior Director of AI Sravan Vadigepalli sat down to explain how the retailer is building in AI, aligni…
Advocates writing for The Progressive called for a halt on new data centers and computing capacity for frontie…
Salesforce has recently been in talks to buy Listen Labs, an AI customer research platform, for around $2 bill…