MiniMax M3 is a natively multimodal model (text, image, and video input, text output) with a 1 million token context window. It features MiniMax Sparse Attention, a mechanism that selectively processes key-value blocks to achieve roughly 9× speedup on prefill and 15× on decode at 1M tokens.
On coding tasks, M3 scores 59.0% on SWE-Bench Pro (behind Claude Opus 4.7 at 64.3% and ahead of Gemini 3.1 Pro at 54.2%), and in code audits matched GPT-5.5's rigor without filler. On abstract reasoning, the model scores in low single digits on ARC-AGI-2, consistent with the broader Chinese model family.
Pricing is $0.60 per million input tokens and $2.40 per million output tokens, with a 50% launch promo for the first week. The model is available through the MiniMax API, OpenRouter, and launch partners. Parameter count remains undisclosed, and weights were promised within 10 days of launch.
Summaries like this, in your inbox every morning.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
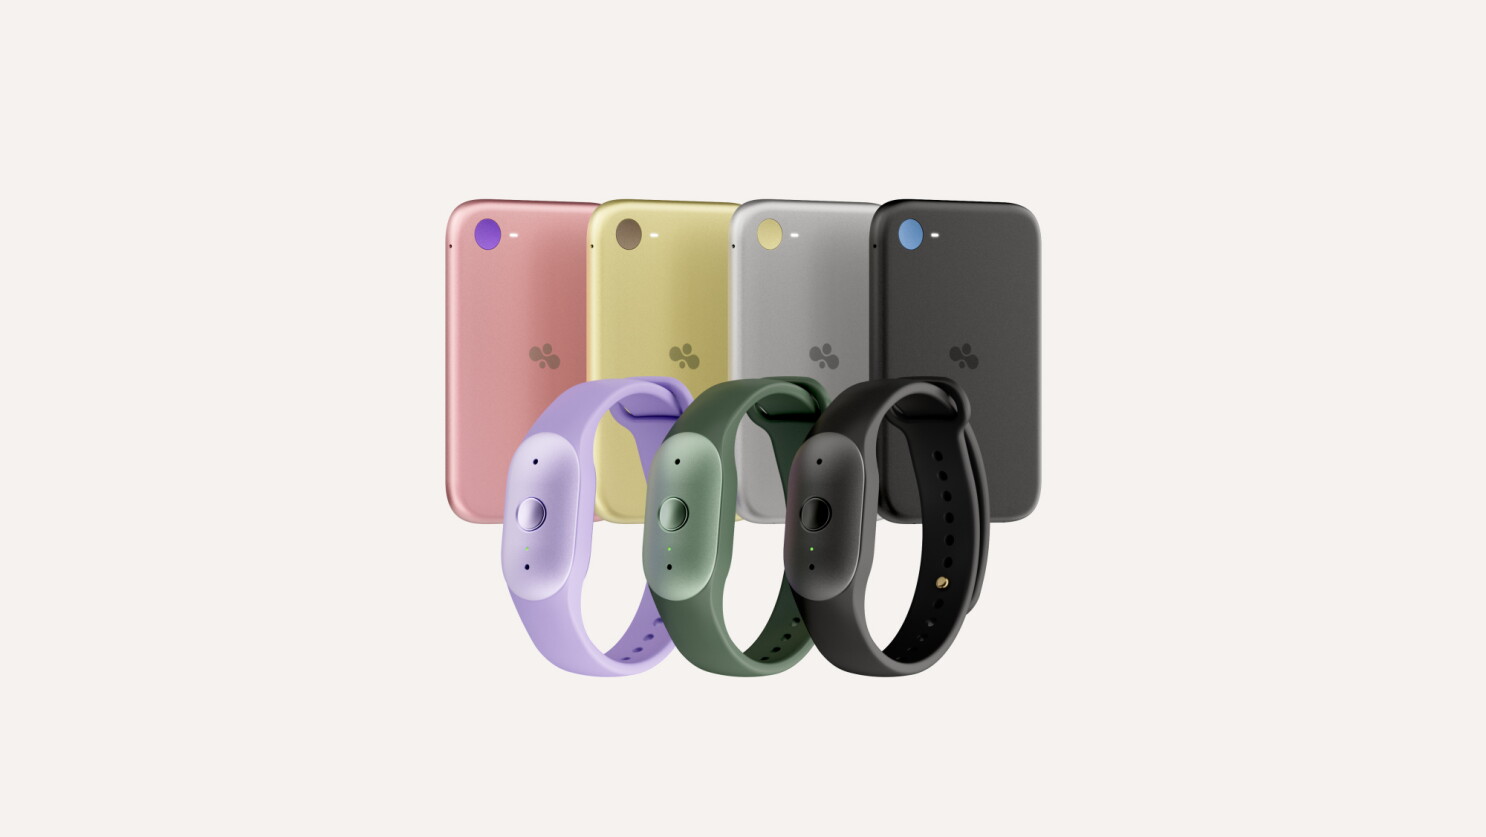
Amazon introduced Bee Frontier, a wearable personal AI, for $74.99 in Onyx, Lavender and Sage, and Bee Eclipse…
Citi has become the latest US bank to restrict AI agents from accessing accounts, per the Financial Times
Aparna Nair, IBM's chief talent, leadership, and culture officer, said generalists alone "will cut it" in the…
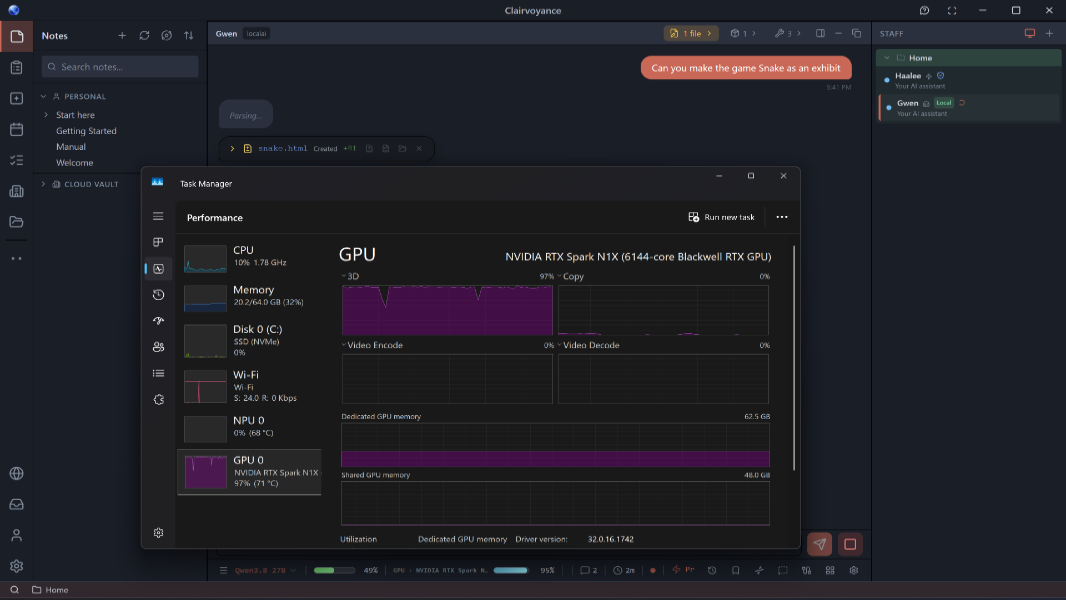
Microsoft and Nvidia are promoting RTX Spark, a new class of Windows PCs for local AI, with a top configuratio…
Dell says its AI Data Platform uses a four-engine architecture and a Unified Semantic Layer to connect siloed…
Microsoft AI CEO Mustafa Suleyman told employees that MAI-Base-2, announced Thursday, is a stronger pre-traine…