What happened
OpenAI published copy-ready prompts for GPT-6.2 Astra and Sol covering writing style, initiative, and coding, and warns that Responses API edits to conversation history can discard earlier reasoning content.
Why it matters
Developers moving to the new models may see shorter answers and more confirm-seeking unless they rewrite system prompts, and losing prior reasoning can raise token use as the model repeats work.
WHO IT HITSDevelopers and engineering teams building on OpenAI's API are the immediate audience, since system prompts and reasoning-level settings may need rewriting when they move to GPT-6.2 Astra or Sol.
Summaries like this, every morning.
OpenAI's new templates read as a course correction for behaviors the company says it observed in both GPT-6.2 releases. Astra, built for the most demanding tasks, writes more briefly and directly by default than earlier models, so instructions like "be concise" may no longer serve developers well. On long tasks, the model can also carry shorthand from its reasoning or from other agents' messages into the final answer, which is why one template tells it to write a fully self-contained response rather than a continuation of intermediate commentary.
The initiative guidance targets a different habit: when user intent is unclear, GPT-6.2 sometimes suggests a next step and waits for confirmation. OpenAI's prompt tells the model to carry out authorized steps itself, pausing only for a major scope change, a real blocker, a user decision, or an irreversible action. The coding template follows the same logic, asking the model to reuse existing logic, skip new tests unless requested or needed for a specific regression, and favor readable code over fewer lines.
The API changes add a practical wrinkle. Editing conversation history, switching models, or changing the end user or organization can now discard earlier reasoning content, which OpenAI says can hurt quality and increase token usage. Pricing context matters too: Astra starts at $8 per million input tokens and $40 per million output tokens up to 272,000 tokens, then jumps to $16 and $60, and Codex automatically compresses context at that cap.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Seramount's survey of more than 1,800 U.S
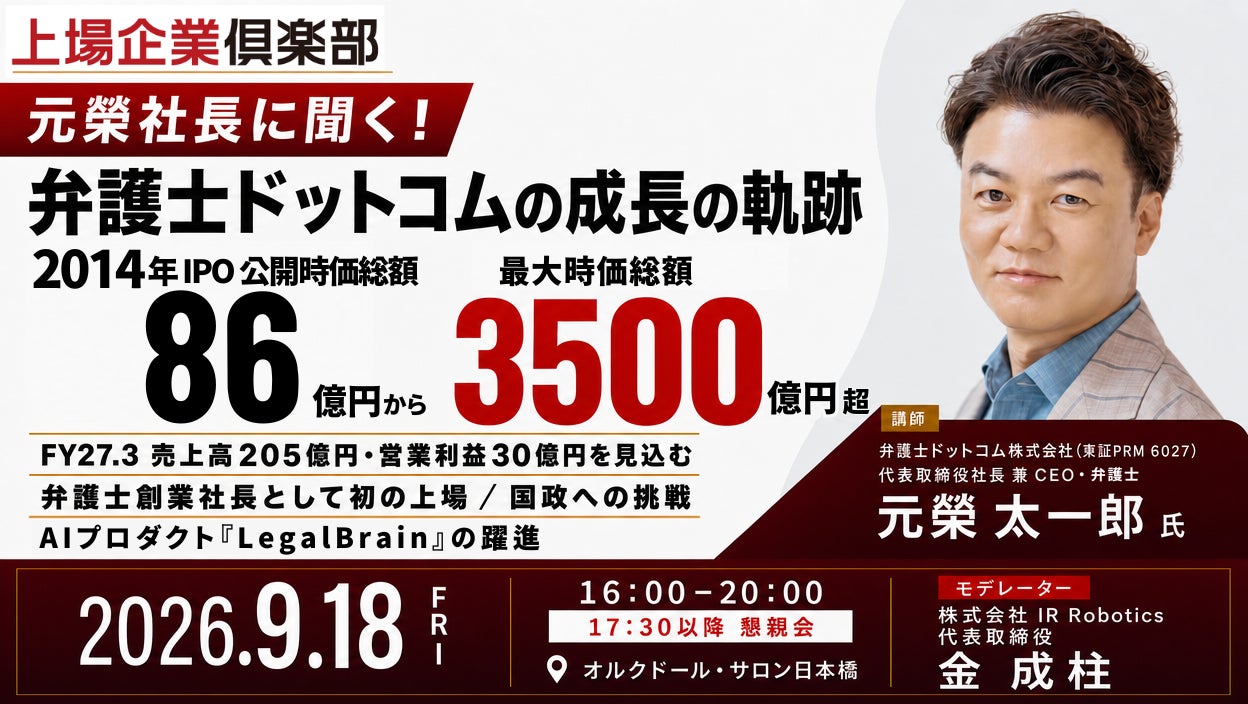
At the 73rd Listed Company Club on September 18, Bengoshi Dotcom CEO Taichiro Motoe traced an eight-year push…
Levent Alpöge said he and Claude proved the Riemann Hypothesis and the Generalized Riemann Hypothesis; the Lea…
A Fortune commentary notes OpenAI's terms leave delivery and returns with merchants and keep existing card dis…
Google said K-12 accounts that block its AI tools will lose Google Search entirely, with VP for education Chri…
SolidWizard Technology says rising investment in AI, semiconductors, and high-performance computing is driving…