What happened
Researchers led by Aude Billard conducted a year-long review of papers in Learning from Demonstration (a subfield of robotics) and found that of more than 300 papers examined, only about 20% qualified as offering highly notable contributions; the rest were incremental improvements or new applications.
Why it matters
Staying current in robotics research is becoming unmanageable—IEEE alone published 46,968 robotics or automation papers in 2024, with submissions to robotics journals surging 26% in 2023 and 31% in 2024. The study reveals that automated tools like large language models (LLMs) and scripts can summarize papers and extract data reliably, but they cannot identify true novelty or catch overstated claims, making human judgment still essential for separating genuine breakthroughs from incremental work.
What to watch
The authors recommend creating a research engine that ranks papers by peer-review status and journal reputation (rather than citation count or downloads), establishing blind publication models to reduce bias toward authors' names and institutions, and using LLMs strategically for summarization and data collection rather than novelty assessment—a hybrid approach to manage the paper deluge without losing important work.
Summaries like this, in your inbox every morning.
The explosion of scientific publishing in robotics reflects both opportunity and crisis. IEEE's 46,968 robotics and automation papers in 2024—coupled with a 31% year-over-year surge in submissions in 2024—makes it mathematically impossible for even specialized researchers to review all relevant work. The study's choice to focus on a narrow subfield, Learning from Demonstration, underscores how daunting the challenge has become: even within one robotics methodology, researchers must sift through hundreds of papers annually to identify the few that actually advance the field.
The research design itself reveals a critical limitation of machine assistance. Large language models excel at the clerical tasks of literature review—summarizing content, extracting numbers, and flagging key findings—yet they cannot perform the expert judgment that separates genuine innovation from incremental tweaking or overclaimed results. An LLM cannot recognize when a paper restates a problem already solved, nor can it detect when an abstract overpromises relative to the actual contribution. This asymmetry is consequential: papers with genuine breakthroughs do not necessarily accumulate more citations or downloads, so automated ranking by popularity alone misses important work and wastes researcher time on redundant efforts.
The authors' recommendations point toward a structural solution: replace popularity-based discovery (Google Scholar, IEEEXplore) with reputation-weighted engines that honor journal and conference peer review; introduce blind publication to shift focus from author prestige to content; and recalibrate the role of AI in literature synthesis—keeping it in its lane of summarization and data extraction while preserving human expertise for novelty assessment. The study thus frames the 'paper deluge' not as a tool problem (AI will not solve it), but as an incentive problem rooted in how research is valued, discovered, and filtered.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Skild AI used Nvidia Isaac Sim to give its S1 model one objective — score a goal — and let it compete against…

Yamazaki Mazak and ABEJA said on the 16th they will start joint development of physical AI, using ABEJA's ABEJ…
Toyota Motor's Japan Mobility Show Bizweek 2026 booth centers on its AI basketball robot CUE7, has no other ex…
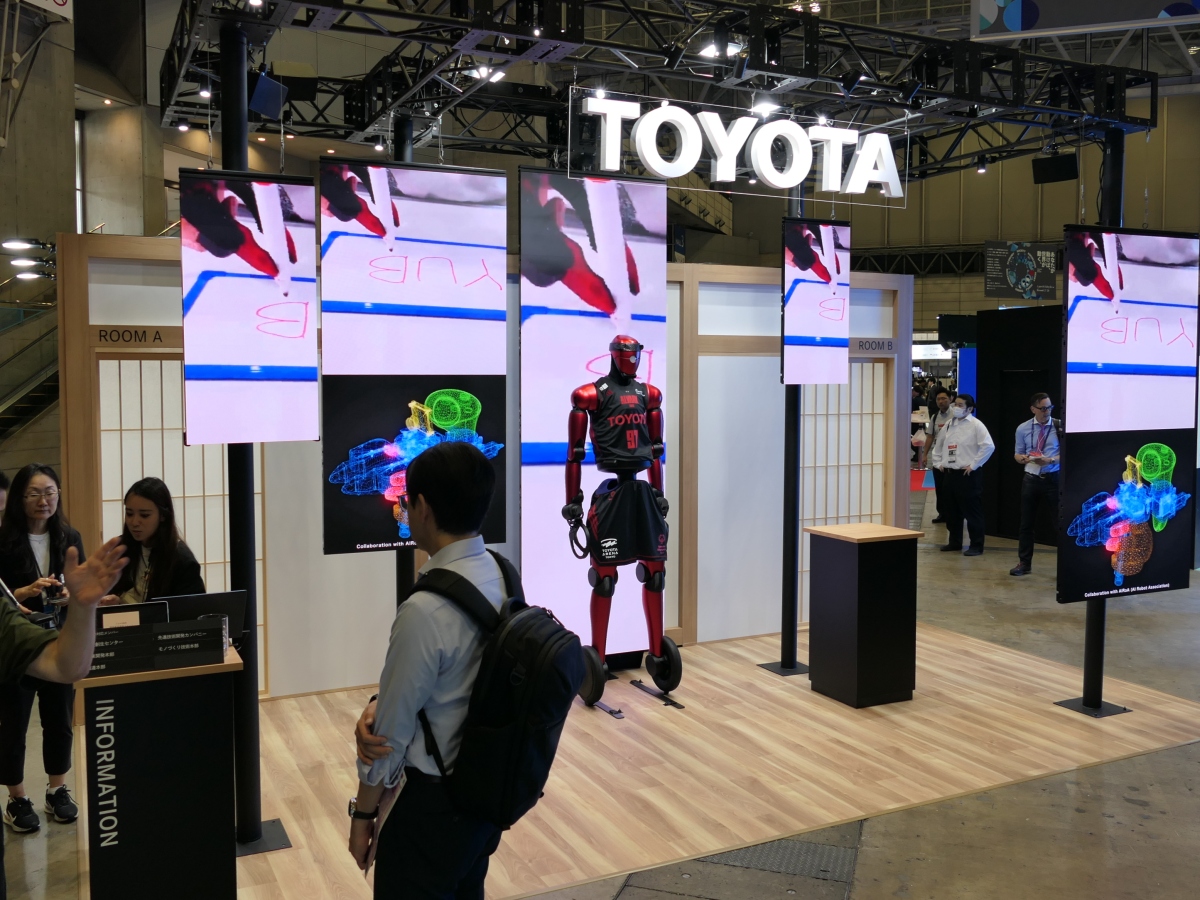
Japan Mobility Show Bizweek 2026 showcased Physical AI applications, including Toyota's basketball-playing rob…
Google pitched Gemini 4 Argon as one model for robot control, simulation and training-data review, saying it s…
Researcher Sammy Azdoufal discovered Energize Lab's Eiliko robot stores 13 million conversations from 68,000 t…