A Reddit user on r/AI_Agents asked how teams running agents in production handle inference, noting one agent task can mean dozens or hundreds of model calls and that Nvidia has said memory/HBM constraints could last through 2028.
Summaries like this, in your inbox every morning.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Infineon Technologies said on October 21 it is expanding work with Nvidia on 800-volt direct current power arc…
BloFin Research outlined three defensive moves for a potential 2027 AI correction: shift some S&P 500 exposure…
Shares fell 6.9% Thursday, extending the drop from the June 2 peak to 50%, with market capitalization at about…
Schneider Electric, Nvidia and HPE formed a strategic collaboration to launch Industrial AI Agents at the Edge…
Anthropic released Claude Duet, built on Claude Opus 5.5
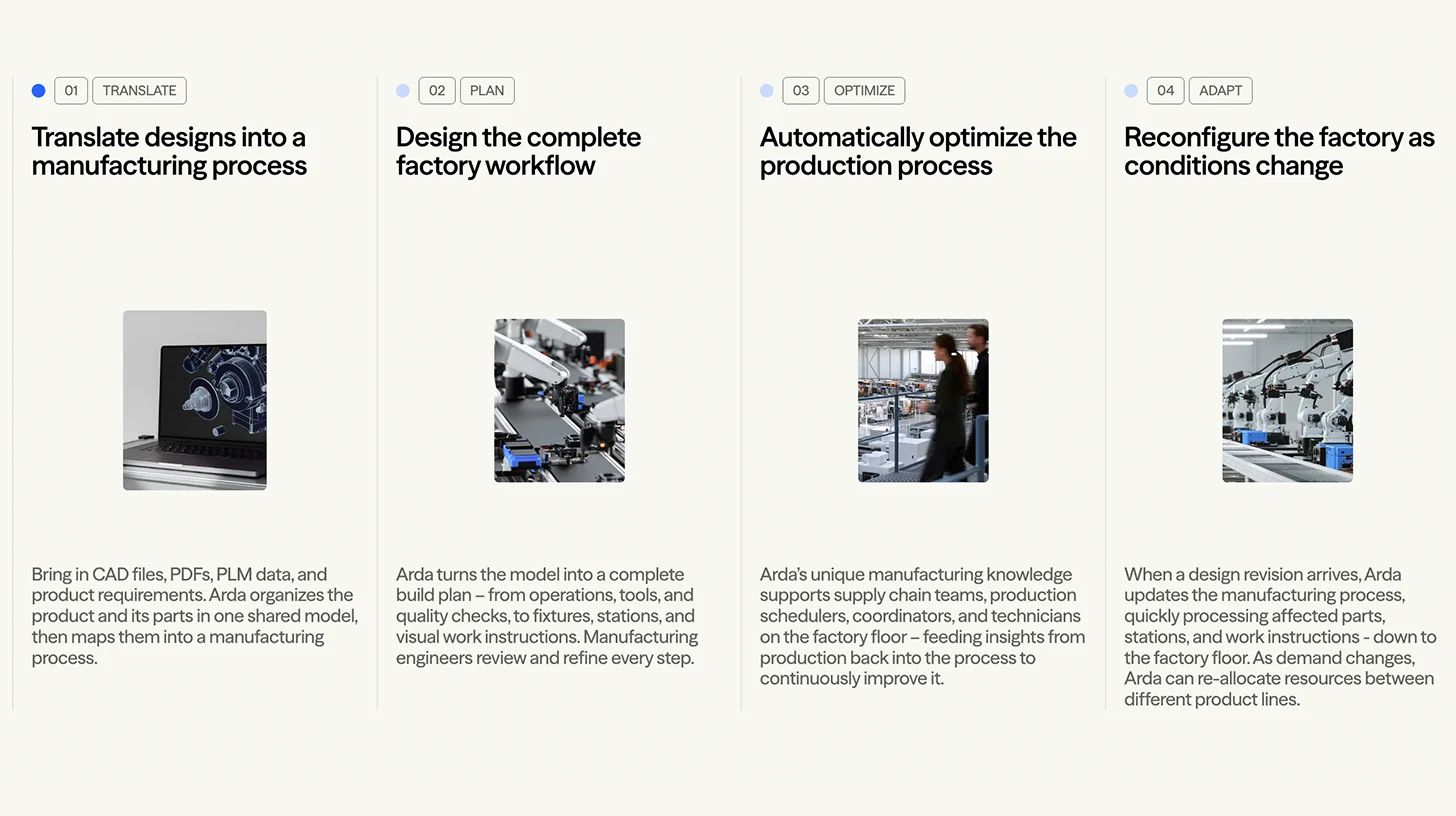
Bob McGrew's Arda launched Oct