What happened
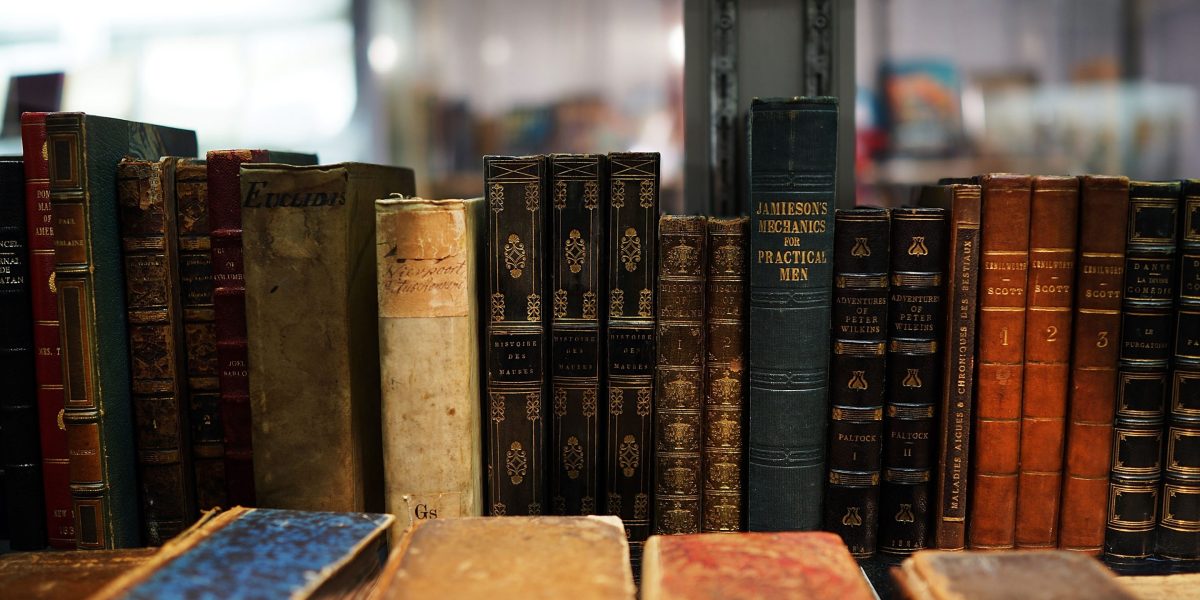
A Dutch bookseller received an email from a company called 2077AI requesting 3,001 book titles—mostly academic works published between 2020 and 2021—for shipment to China, but dismissed it as spam until a journalist revealed the request's connection to artificial intelligence. Similar bulk book orders have surfaced in Germany and Switzerland, suggesting AI companies are building physical supply chains to source books at scale.
Why it matters
Court records showed Anthropic purchased millions of physical books, cut their spines, scanned them, and discarded the originals to train AI models—a practice a federal judge ruled was fair use under copyright law. The hidden procurement networks reveal how AI companies are systematically acquiring secondhand books outside public view, raising questions about the sourcing of training data for large language models.
What to watch
Earlier this year, ISBNdb advertised services to help AI labs source bulk book purchases ranging from 1,000 to 1 million copies, though the company later said the service was never launched and the webpages reflected only an exploratory concept. The extent of ongoing book acquisition by AI companies remains unclear, as 2077AI did not respond to requests for comment.
Summaries like this, in your inbox every morning.
The email to Dutch bookseller Pieter de Vries offers a concrete example of how AI companies are building physical supply chains to acquire training data. While the public debate around AI training data has focused on web scraping and copyright disputes over digital libraries, this procurement request reveals a parallel, largely invisible operation: the systematic acquisition of physical books through secondhand markets. The request itself—3,001 academic titles shipped to China—bears the hallmarks of deliberate sourcing rather than casual purchasing, yet was designed to look innocuous enough that multiple booksellers dismissed it as spam.
The connection to Anthropic's "Project Panama" provides crucial context. Court records revealed that the company purchased millions of physical books, destructively scanned them, and disposed of the originals—a process that federal courts later sanctioned as fair use. This legal outcome may have emboldened broader procurement efforts across the AI industry. The discovery that ISBNdb, a metadata company, advertised bulk book sourcing services for "LLM training needs" at scales of "1,000 to 1 million books" suggests that infrastructure for large-scale acquisition is being built, even if ISBNdb later claimed the service was never operational. Similar orders reported in Germany and Switzerland indicate this is not an isolated incident but part of a coordinated, international supply strategy.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
ElevenLabs completed a $300 million employee tender at a $22 billion valuation, and co-founder Mati Staniszews…

On October 15, OpenAI announced the Rosalind Academic Plan, giving approved US university labs free access to…

A Qiita article compared automated red-teaming methods for LLM apps — GCG, PAIR, and TAP — using mock implemen…

Liquid AI released d1-ultra on October 15, 2026, an upgraded open-weights decision model that averaged 76.7 ac…

Circlia started a proof-of-concept for TASTE SIGNAL: visitors to Holland Village Cafe FUKUOKA taste cookies an…

In a webinar hosted by French Mathematical Society president Isabelle Gallagher, Fields Medal winner Hugo Dumi…

