What happened
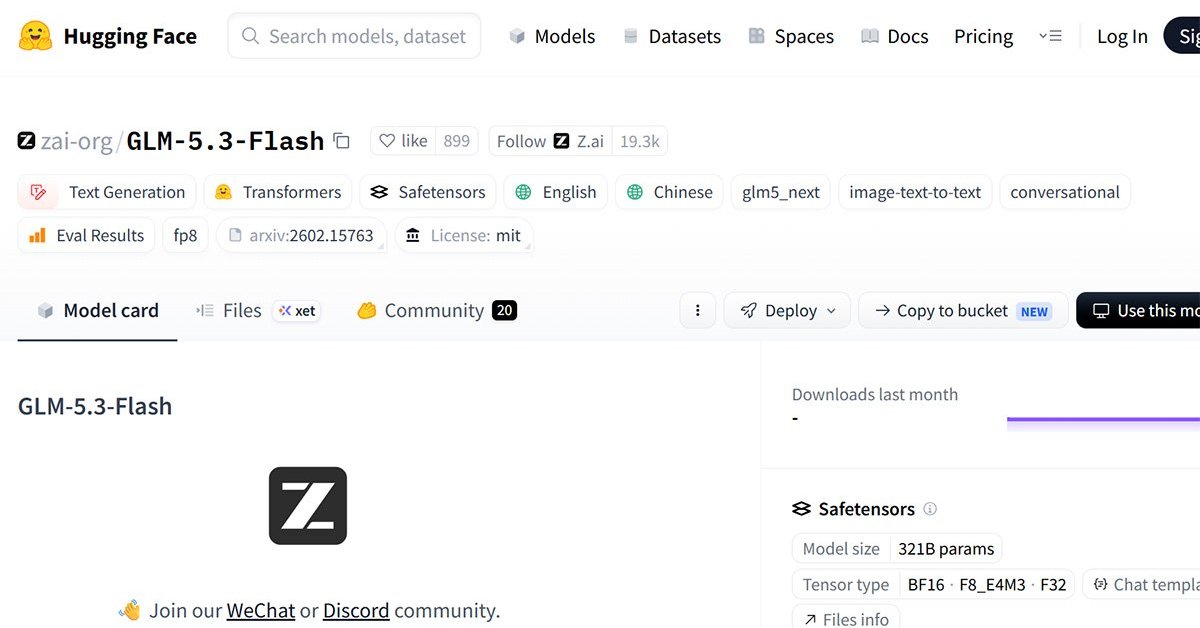
Z.ai revealed on August 26 that the anonymous model "Ox Alpha" was actually its own GLM-5.3-Flash, and that inference during the validation period ran on a cluster of China-made AI chips. The model's weights were released under a commercial-use MIT license the same day.
Why it matters
GLM-5.3-Flash accumulated 17.5 trillion tokens on OpenRouter since August 20, ranking #1 in the weekly chart. Z.ai says the cluster of tens of thousands of China-made chips handled this demand at a per-token cost on par with Nvidia GPUs, arguing it shows China-made chips can support state-of-the-art inference at scale.
What to watch
The model has 320B total parameters and 18B active, supports text, image, and video input, and up to 1M token context. It scored 57 on the Artificial Analysis Intelligence Index, just 3 points behind the top model GLM-5.3, with about 7.5x lower cost per task.
Summaries like this, in your inbox every morning.
Z.ai has been offering GLM-5.3-Flash anonymously on OpenRouter since August 20, sparking speculation about its origin. The reveal on August 26 that it is a Z.ai model running on a cluster of tens of thousands of China-made chips is significant because it demonstrates that domestic hardware can serve frontier-level inference at a cost comparable to Nvidia GPUs. The model's performance—scoring 57 on the Artificial Analysis Intelligence Index, just 3 points behind the top model GLM-5.3—and its lower cost per task suggest that the combination of efficient architecture and China-made chips could offer a cost-effective alternative in the AI inference market. This development may encourage further investment in domestic chip ecosystems, though the article does not speculate on broader market impacts.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Supermicro Computer appointed Mark Long as chief financial officer, bringing an experienced technology finance…

Holtek Semiconductor unveiled its 2026 product roadmap on October 15, focusing on four core areas: smart prote…

TSMC reported about NT$763.1b in Q3 net profit and confirmed that demand for advanced processors is running ah…

Nvidia-backed CoreWeave steadied Thursday after a sharp slump, as investors worried about the debt financing b…

Circlia started a proof-of-concept for TASTE SIGNAL: visitors to Holland Village Cafe FUKUOKA taste cookies an…

Weathernews said on October 15 it implemented its own AI weather-forecasting model, AI-Nowcast, in its Weather…