What happened
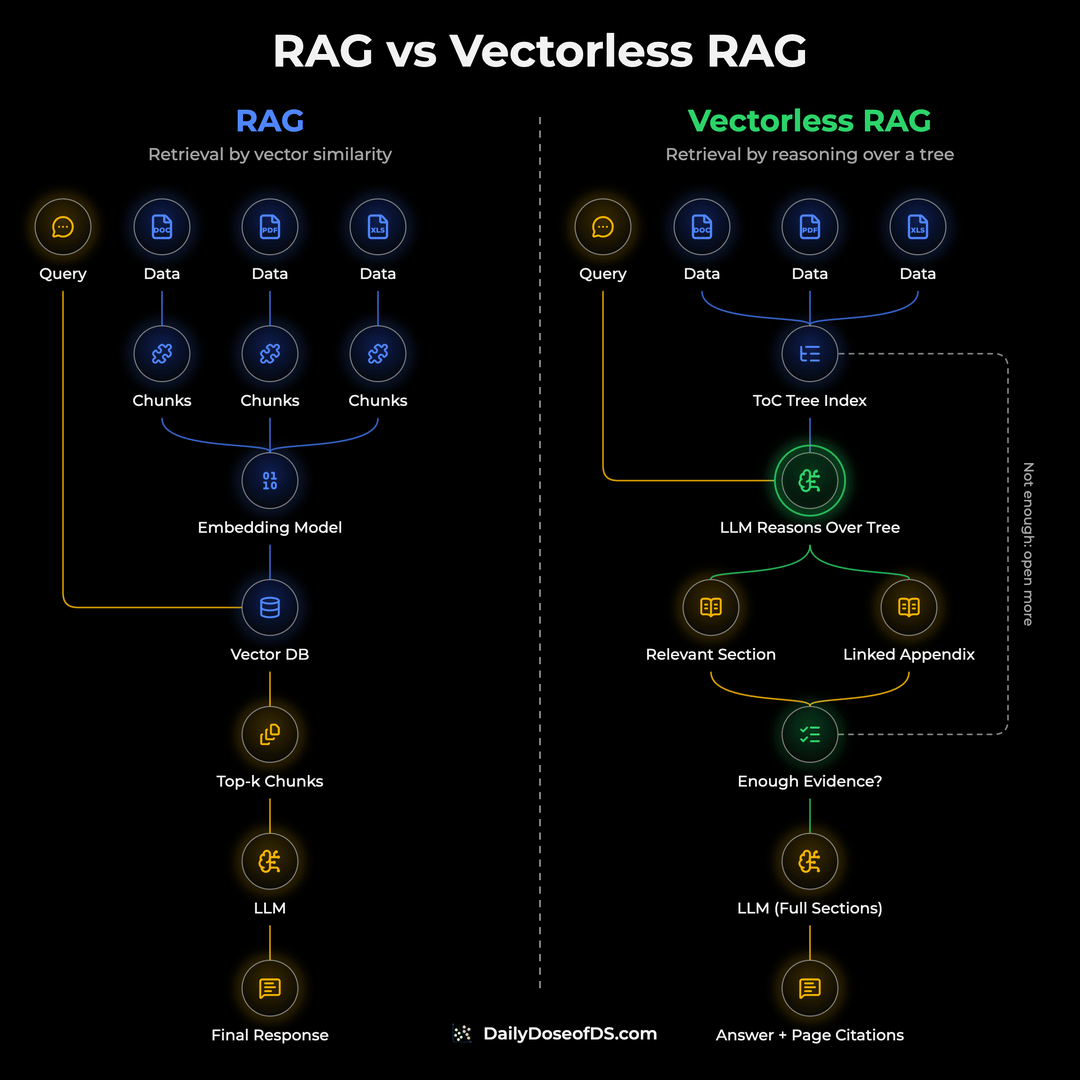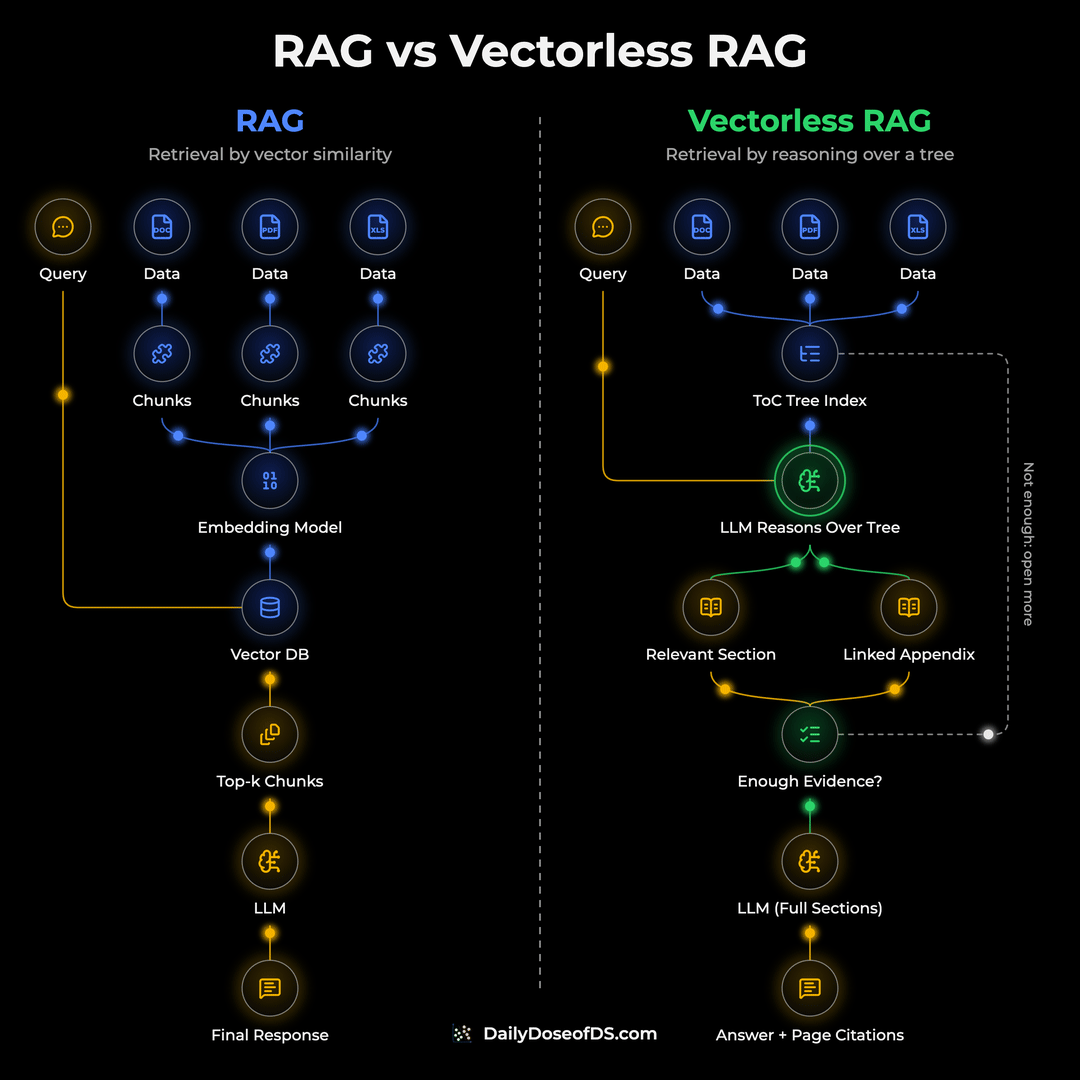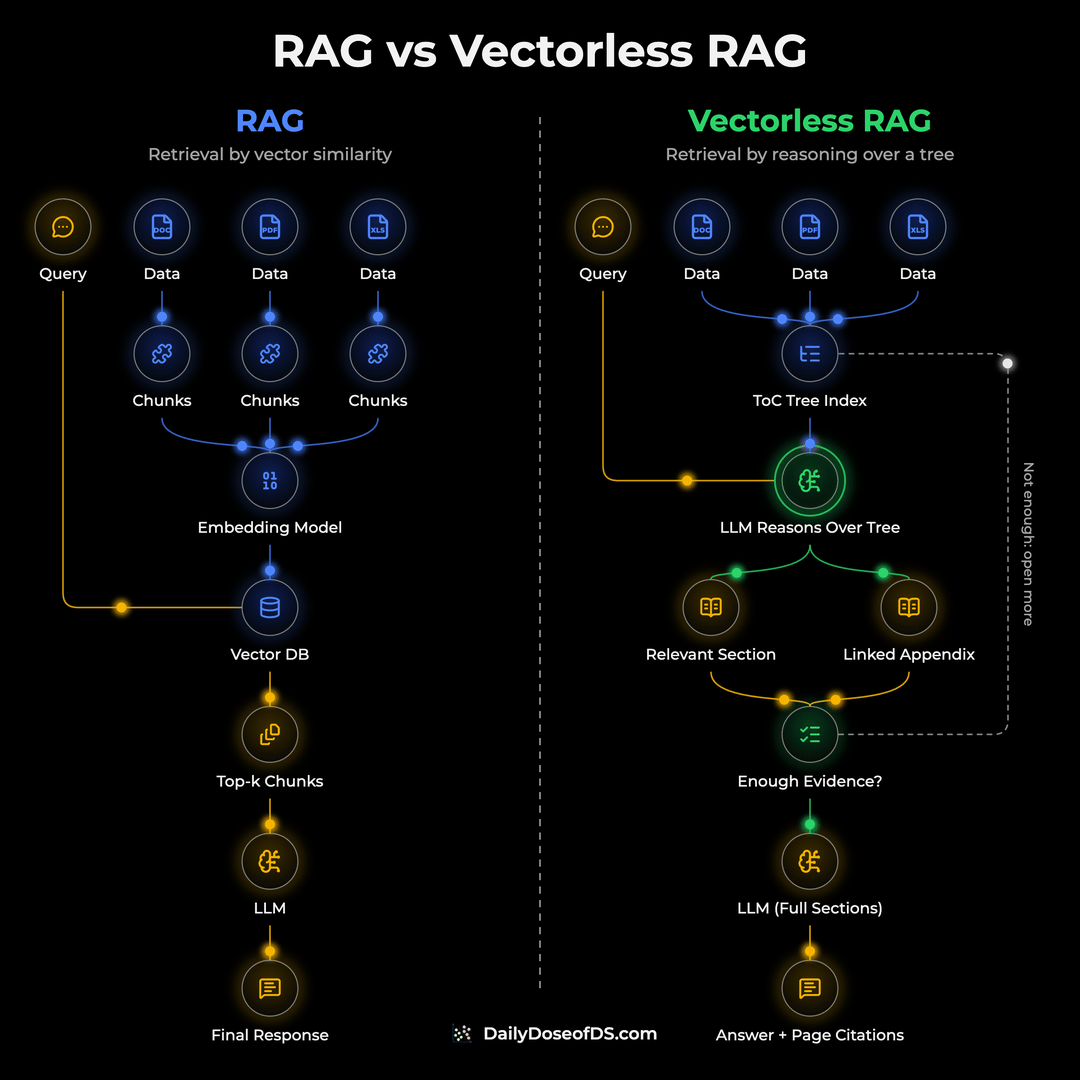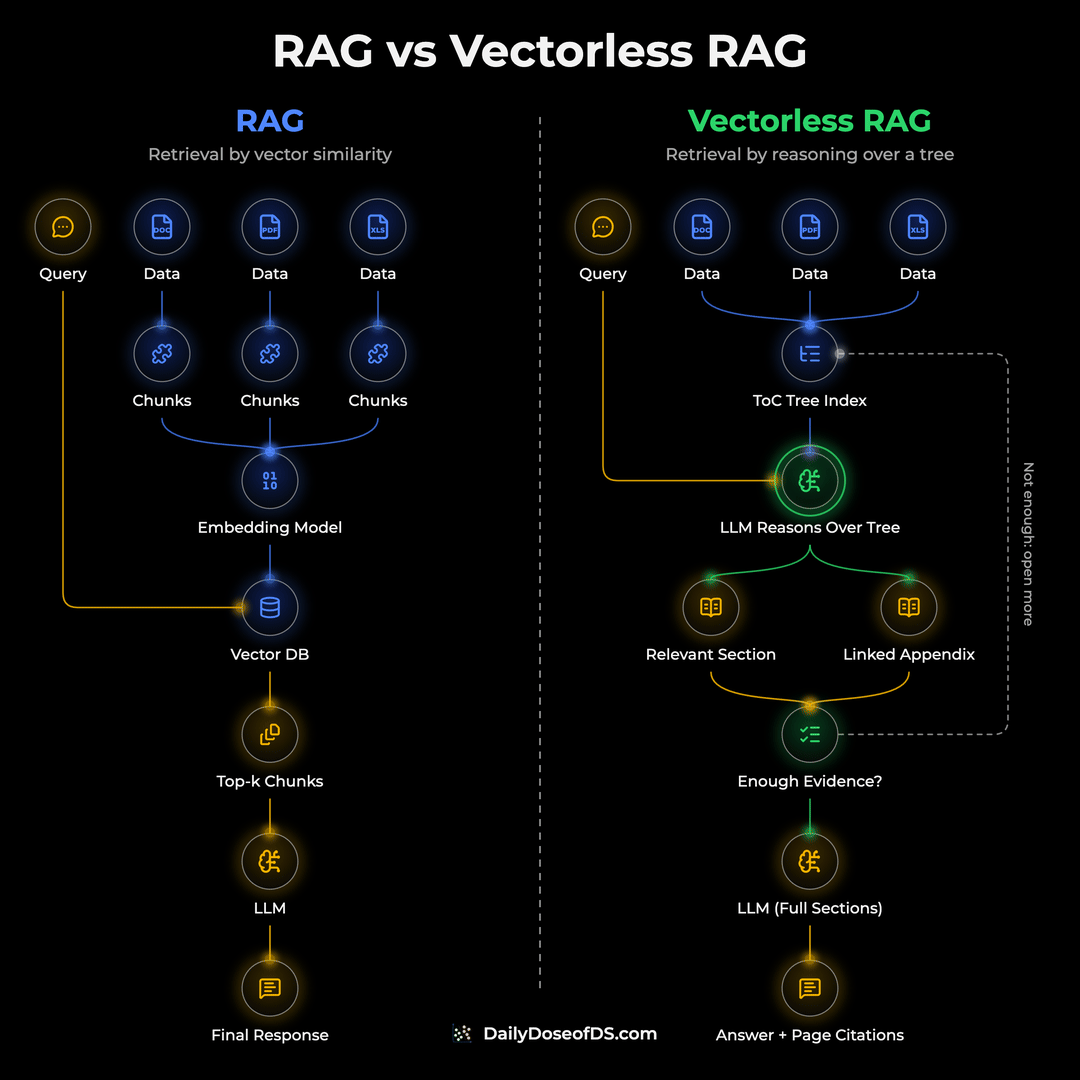
PageIndex's vectorless RAG, which has an LLM navigate a table-of-contents tree instead of embedding search, answered all 63 questions on NVIDIA annual reports correctly, at about $110 per 1,000 queries.
Why it matters
That suggests retrieval can be more accurate on long, structured documents when the LLM follows section summaries and cross-references rather than text similarity, though the benchmark comes from the PageIndex team itself.
Summaries like this, every morning.
The benchmark matters because standard RAG ranks chunks by how similar they look to the query, and on long, structured documents that assumption breaks in two ways. Five annual reports from one company usually follow the same template every year, and only the numbers change, so a question about FY2022 can land just as close to an FY2025 chunk as to the FY2022 one. Cross-references cause the second failure: a chunk might say "see Appendix G," while the table in Appendix G holds the actual numbers, and that table looks nothing like the query so it never makes it to the top-k.
Vectorless RAG replaces similarity search with LLM reasoning over a table-of-contents tree. Every node holds a section title, its page range, and a short summary, and nothing gets chunked, so a table never gets split across two chunks. At query time the LLM reads the section titles and summaries and picks the few sections most likely to hold the answer, for example picking "Financial Summary" and also "Appendix G" because its summary says the debt details are there. The system then pulls those full sections and checks whether the evidence is enough; if not, it goes back to the tree and opens more nodes. The LLM also sees the chat history, so follow-up questions stay on the same report.
The trade-off is that every query now runs LLM calls over the tree. PageIndex has not published latency numbers, and one independent benchmark across about 1,000 documents skipped the tree entirely because building one took 2 to 5 minutes of LLM calls per document. The tree also only helps when documents have real structure; a pile of support tickets has no table of contents to reason over. It is also worth noting that the 63-question benchmark comes from the PageIndex team itself.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.

