What happened
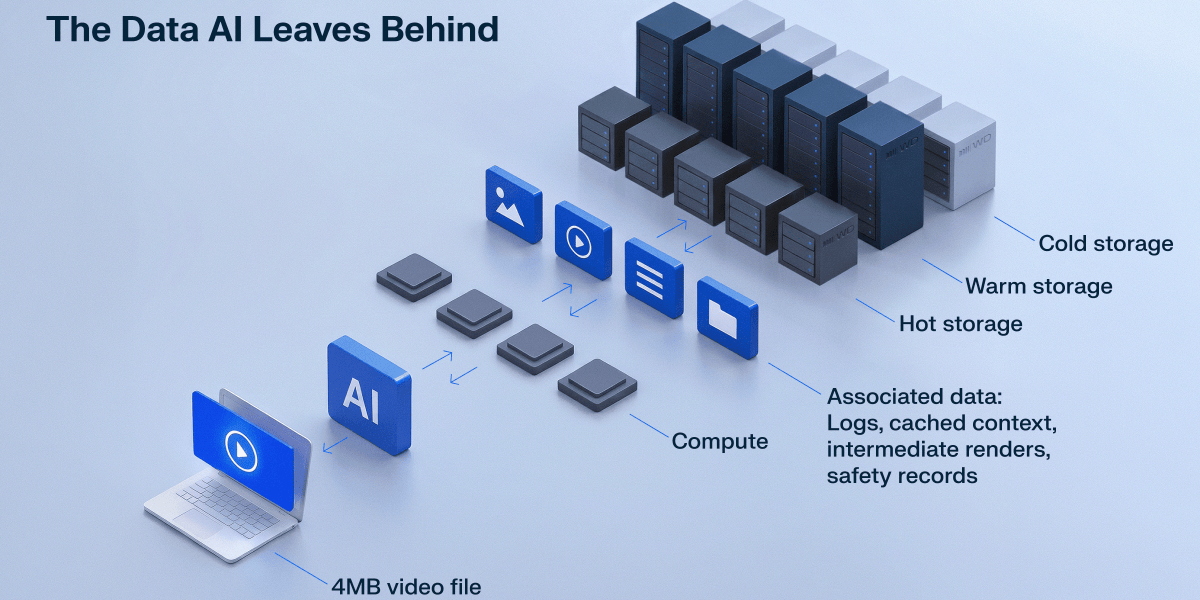
WD measured that an 8-second AI video (a 3.97MB 720p file for the user) generated more than 500MB of back-end data — logs, cached context, renders, backups, safety records — a 130x increase over the visible output.
Why it matters
If storage costs compound with every inference while compute budgets stay cyclical, the storage line can quietly outgrow the compute line that gets all the planning attention.
Summaries like this, in your inbox every morning.
A distinction between training and inference matters for how AI budgets are built. Training is finite: a run starts, burns through compute, and ends, so it can be budgeted and retired. Inference runs continuously, and every request leaves data behind. WD's measurement of an 8-second video makes that abstract point concrete: the user sees a 3.97MB 720p file, while the back end retains more than 500MB, a 130x multiplier. At enterprise scale, with longer or higher-resolution video, the back-end footprint can grow into the hundreds of gigabytes per clip. The piece also notes that retained data is taking on a new role, as archives that once sat untouched become inputs for retrieval-augmented generation and future inference. That shifts the planning question from raw capacity to how dynamically the stored data will be accessed.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.

