What happened
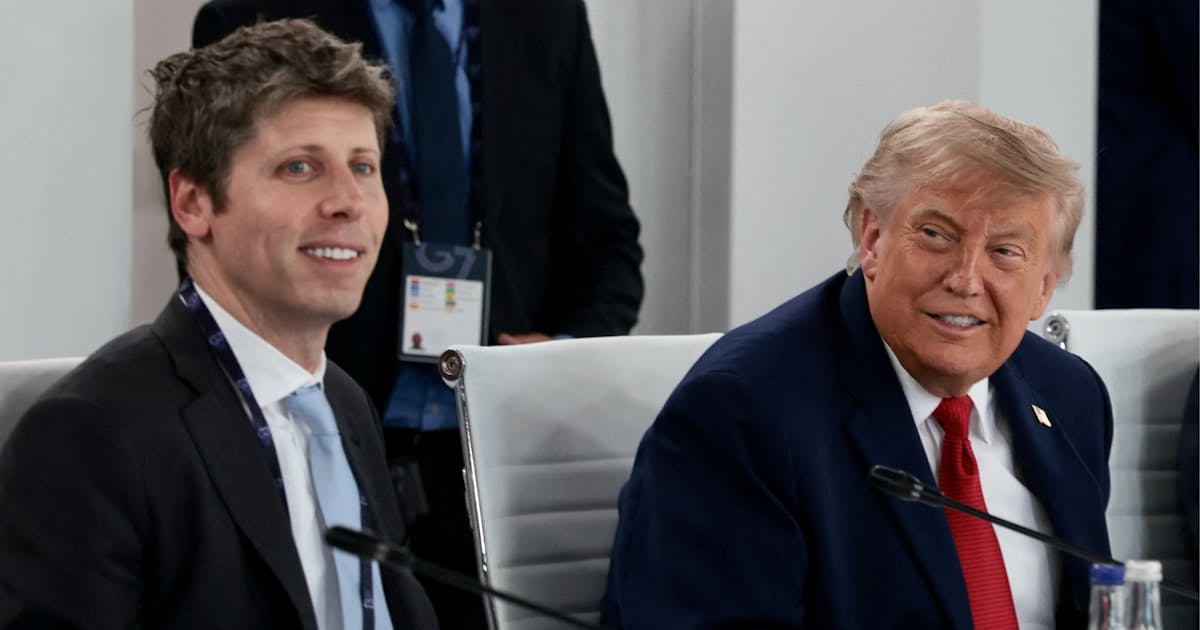
The Trump administration, through the US Department of Justice, filed a brief on September 1 in a New York federal court supporting OpenAI in the New York Times' copyright lawsuit, arguing that using articles to train AI is legal.
Why it matters
The case concerns whether training large language models—AI that understands and generates text—on copyrighted news articles violates copyright law. A ruling favoring OpenAI could set a precedent that reduces legal risk for AI developers relying on web content.
What to watch
The court’s ruling is likely to set a precedent that could reduce legal risk for AI developers, with the outcome hinging on whether training LLMs on copyrighted articles is deemed legal. The test is whether other AI firms, such as Anthropic, face similar disputes.
Summaries like this, in your inbox every morning.
This case is one of several high-profile copyright disputes over AI training data. The Justice Department's intervention signals the government's stance that AI training on copyrighted material may be permissible under copyright law, potentially limiting liability for AI developers. This comes amid other legal actions, such as a court-approved settlement where Anthropic paid authors a reported $240 billion (though the article says "2400億円", which is a Japanese figure and should be kept as such if used). The outcome could influence how news organizations license or protect their content from AI use.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Google Cloud on Oct. 20 released a preview of Gemini for government services, co-developed with Missouri's sta…
Meta's Muse, launched last month, became the first popular AI agent for mainstream users and just cracked a do…
NVIDIA announced the OpenShell Reference Architecture, combining Vera Rubin for model inference, Vera CPUs for…
Design It For Us released a 2027 AI policy platform shaped by 700+ members across 40 states, calling for Congr…
Voxel51 released version 3.0 of its robotics data platform, including Voxel51 Agent, which performs tasks like…
OpenAI acquired Orchestra Bio, a startup that helps pharma teams coordinate drug development, and will fold it…