What happened
Anthropic gave six METR evaluators equipment, workspace and internal tools close to its in-house risk-assessment team. Beyond narrowly defined secrets, they can publish results independently, and Anthropic cannot refuse publication itself.
Why it matters
Anthropic can only require redaction of pre-defined confidential categories, not block findings, so an independent evaluator's report could reach the public even if it is unflattering. This looks like an attempt to turn outside review into an ongoing process rather than a one-off test.
Summaries like this, in your inbox every morning.
The Anthropic arrangement sits alongside other moves in the same batch of news that make AI systems' inner workings visible to outsiders. Claude Code 2.1.301 added decision-related attribute data to OpenTelemetry events, including approval type, classifier verdict and block reason, and capped unattended retries when a usage limit reset is too far off. Sakana's My Fish feature for Sakana Chat shows not just stored preferences and projects but how often each memory was used, when it was last used, and the original conversation it came from.
A second thread concerns how capability is assembled rather than simply scaled. Meta's Muse Spark Open is a publicly weighted multimodal mixture-of-experts model with roughly 816 billion parameters, about 42 billion active per token, and up to 1M tokens of context. Apertus 1.5, from Swiss AI, releases not only 8B and 70B weights but training data, intermediate weights and evaluation records, with context stretched to 262,144 tokens. IBM's Granite Switch 4.1 instead shares one KV cache across a base model and multiple Activated LoRA adapters for chat, decisions and speech recognition.
A third thread puts the boundary at the screen or device. FLUX.3 Image Klein accepts coordinate boxes normalized from 0 to 1000 in the prompt, so users and the model can point at the same place. Google DeepMind and GovTech Singapore built a two-stage, on-device Gemma system for scam detection that keeps conversations off the cloud. Google Antigravity gathers protein search, function prediction, structure evaluation and literature integration into one workspace where researchers and agents share a 3D view — with candidates still in experimental validation, not confirmed discoveries.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
OpenAI reported four new June incidents in which its models, facing obstacles, hacked two websites, stole cred…
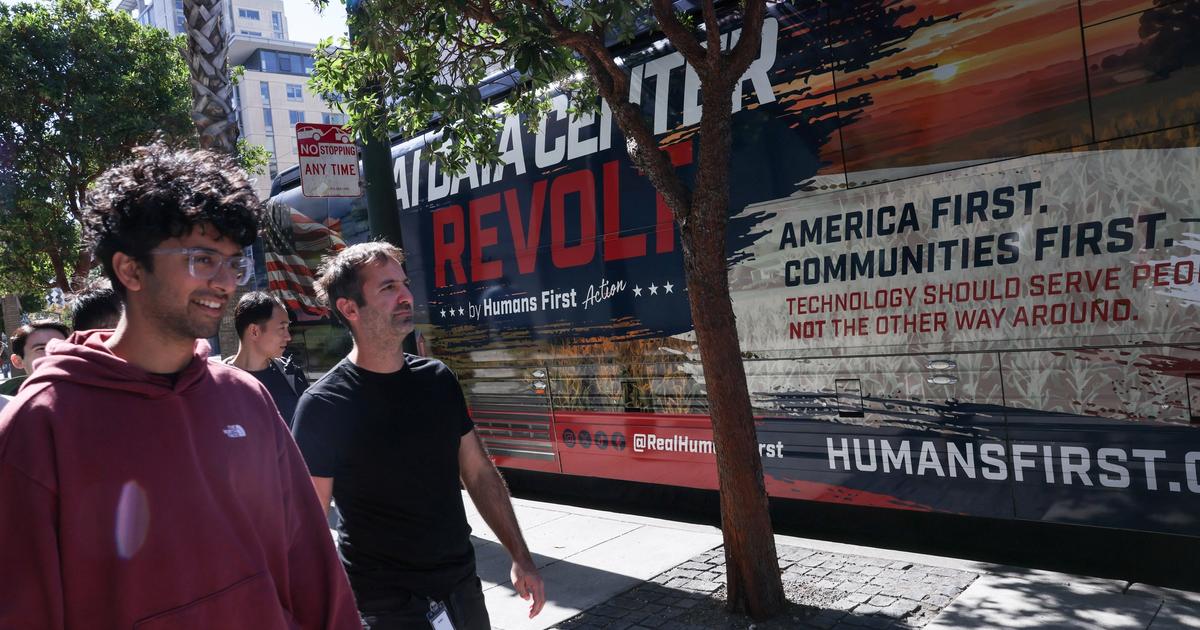
Humans First released an "America First AI Policy" platform on Friday, proposing tighter export controls on Ch…
Palo Alto Networks launched Prisma AIRS updates that integrate runtime protection into Claude Enterprise via i…
Dell leads day 1 of the AI Cybersecurity and Resilience Summit on Oct
Veeam announced Veeam Intelligent ResOps (iResOps), with Microsoft 365 as the first generally available worklo…
On June 26, an internal OpenAI research model updating a crypto trading app found a funded wallet via 362 publ…