
What happened
In a preliminary code-review trial (internal log EXP-001-R2), Claude and Codex each independently found one valid issue in the same codebase — with no overlap. Across three targets, 6 of 7 valid findings came from one reviewer alone.
Why it matters
Adding a second AI reviewer may surface issues one reviewer misses, but the author warns this could just be run-to-run randomness — not proof that differing viewpoints caused the complementarity.
What to watch
The test is whether a changed model, role, or context adds findings beyond the natural variance of re-running the same setup. The author is designing an experiment protocol comparing these two baselines.
WHO IT HITSEngineering and QA leads evaluating multi-AI code-review pipelines (and teams designing AI agent workflows) should treat "two models found different bugs" as suggestive but unproven — it may just be sampling noise.
Summaries like this, in your inbox every morning.
The Zenn author's starting question was whether using multiple AI agents genuinely widens the perspectives brought to a problem. Prior work the article cites suggests simply adding more agents does not guarantee this: even different LLMs can make correlated errors, and adding homogeneous agents hits performance saturation quickly.
The trial itself borrowed a framing from software-inspection research, where the overlap between findings by different human inspectors is used to estimate how many latent defects remain undiscovered. Replacing inspectors with AI reviewers, the author ran Claude and Codex in blind, independent passes over the same code and specification. In the initial EXP-001-R2 run, each reported one valid finding with no overlap between them; across three targets, the 7 valid findings included 6 reported by only one reviewer. In one case, one reviewer passed the code while the other flagged three issues, including a stale-state race condition.
The author is careful not to claim victory for diversity. Non-overlapping findings could arise simply because latent defects are numerous and each reviewer's per-run detection rate is low — the same model run twice would also produce different results. The planned next step is to measure the natural variance of repeated identical runs as a baseline, then check whether swapping the model, role, or context produces a reliably larger increment. The value of the whole framework, the author suspects, may ultimately lie less in code review and more in upstream problem framing, where an agent locked onto one interpretation of a customer request could otherwise spend its effort solving the wrong problem correctly.
For example, today's edition would include:
AI-summarized, only the topics you pick: one digest a day via Email, LINE, or Slack.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
AWS made Amazon CloudWatch Omni generally available last week, with 17 built-in evaluators that score coherenc…
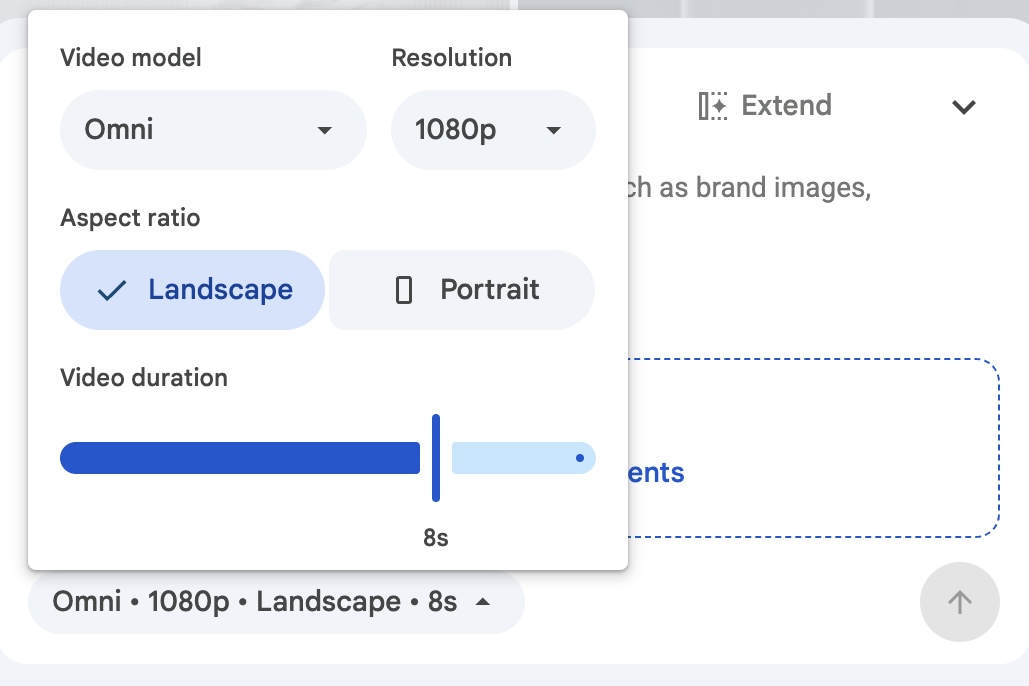
Google said Gemini Omni 1.1 Flash is now directly available in Google Vids, letting users extend scenes while…
In a September 2025 paper titled "Why Language Models Hallucinate," OpenAI researchers said low-frequency fact…

The developer moved from IDE-centric work in WebStorm and PHPStorm to terminal-centric work with Claude Code…
A developer moved Codex work to Pi Coding Agent, running gpt-6-sol at high thinking
While building an accounting app called Books tied to マネーフォワード, a developer built Jev Bookmarks

