What happened
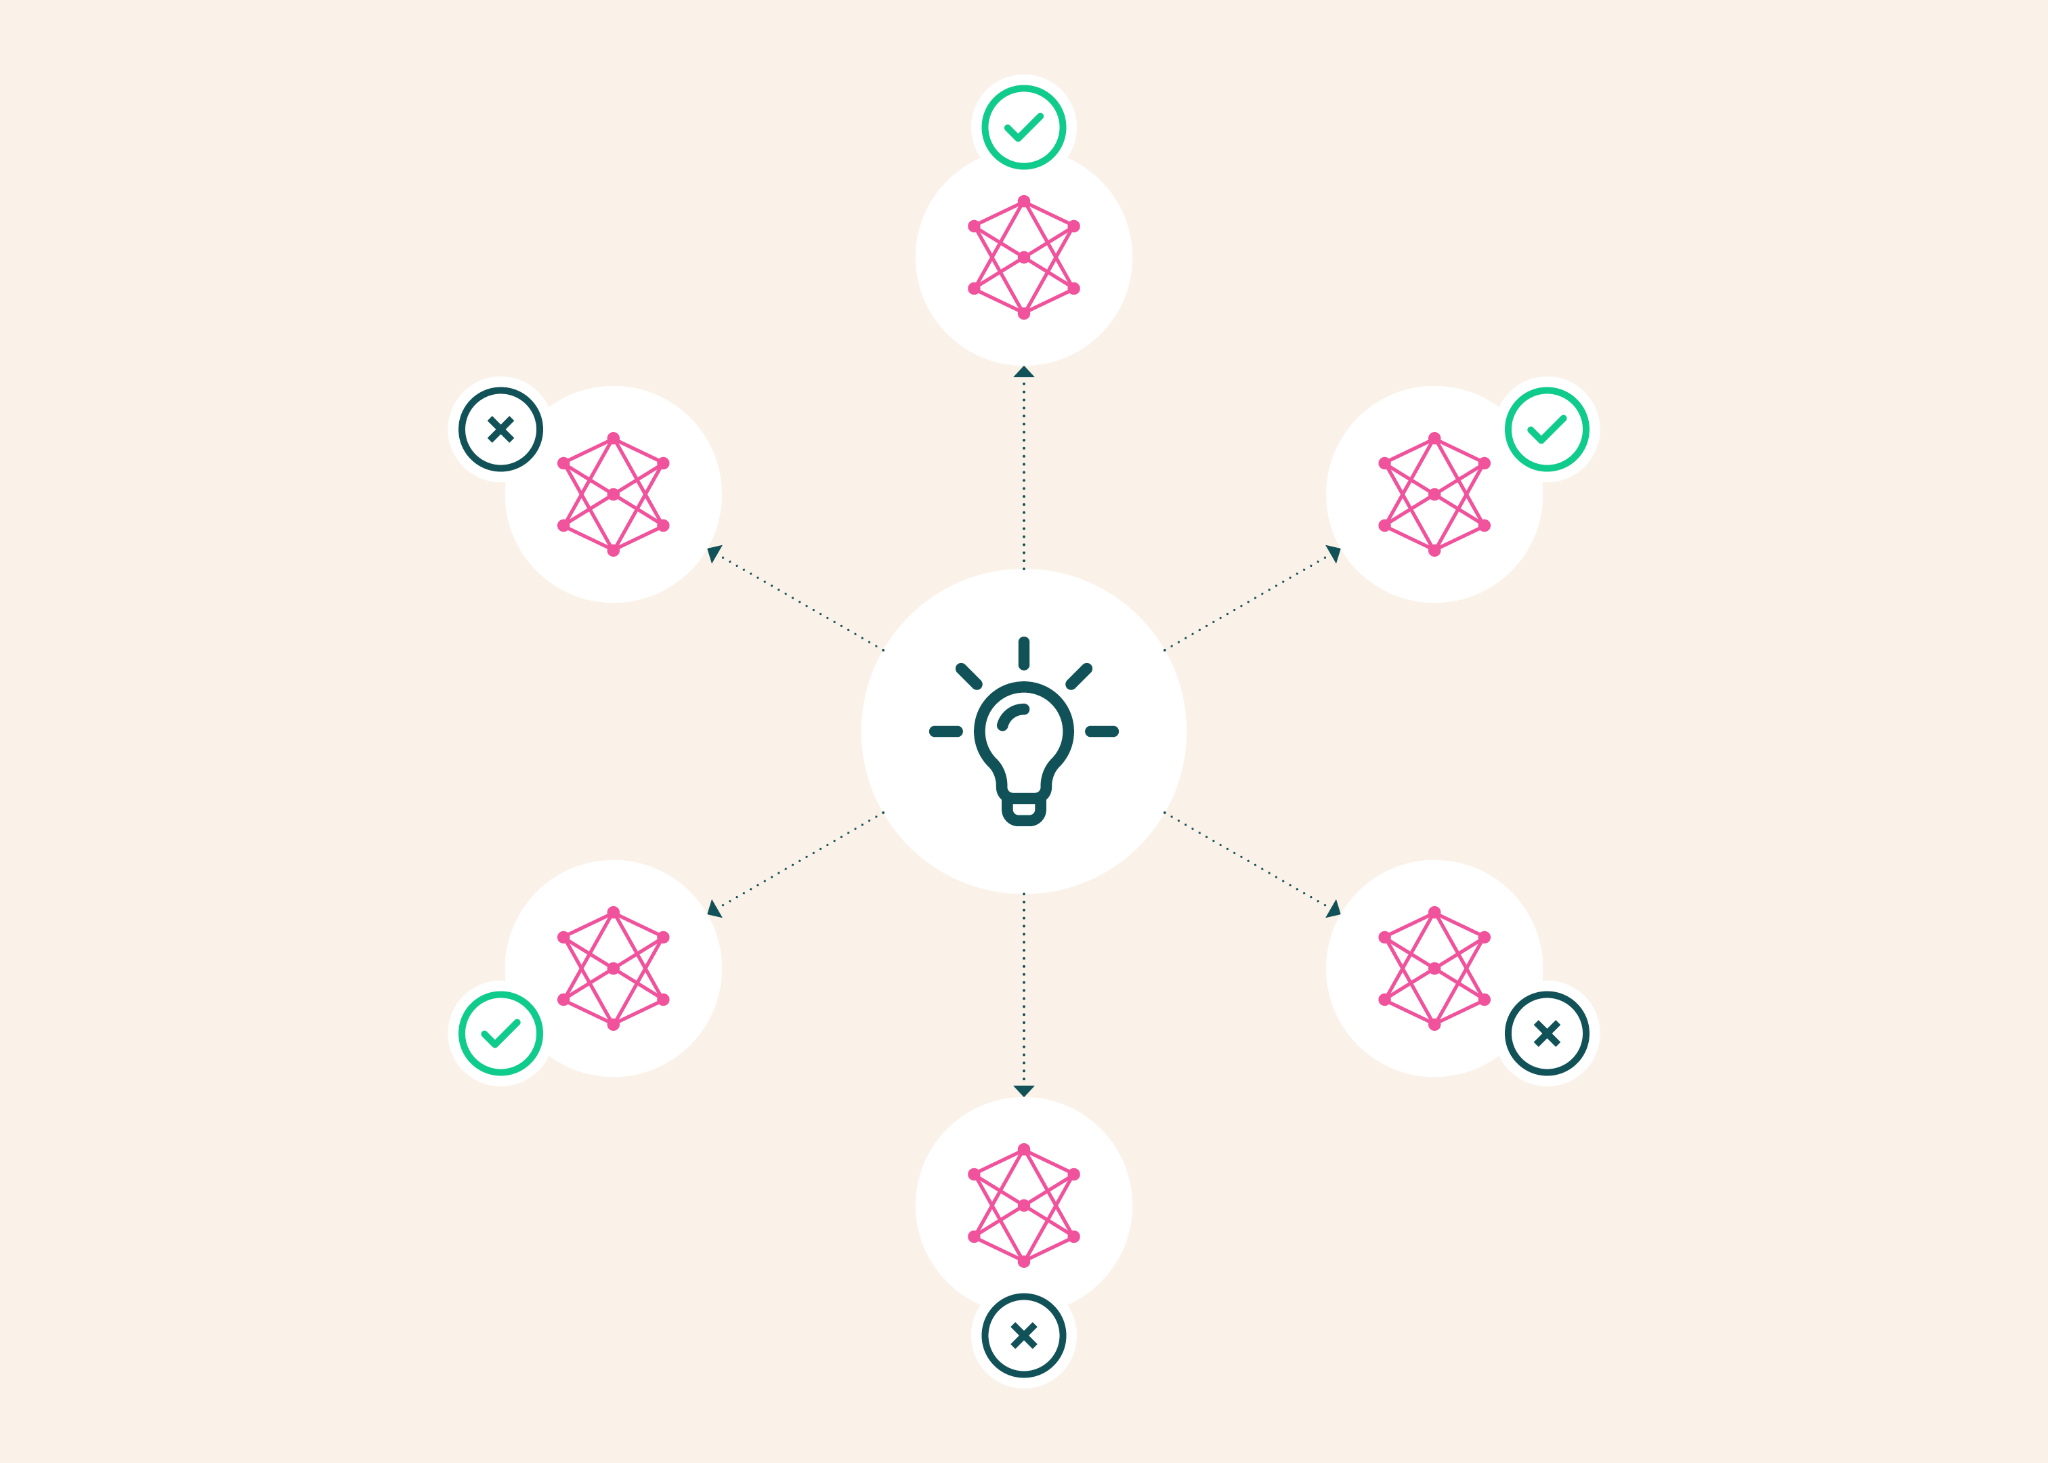
Ai2 released Old Ideas, Novel Problems, a benchmark built from ICLR 2026 peer reviews, and found six LLM judges — including GPT-5.4 and Claude Opus 4.6 — gave sharply different novelty verdicts when prompts changed; GPT-5.4's accuracy fell from 93.5% to 40.9% on one prompt swap.
Why it matters
If a single reworded prompt flips more than half a judge's verdicts on AI-generated ideas, teams using these judges to compare ideation systems may be reading noise as signal — and stability seen on human-written papers may not carry over.
WHO IT HITSResearch teams and product groups that use LLM judges to score or rank AI-generated research ideas — for example when comparing ideation systems — face verdicts that shift with prompt wording, so their comparisons may not hold up.
Summaries like this, every morning.
Ai2's study sits inside a broader push to automate parts of scientific discovery. The lab already runs DataVoyager for structured-data exploration, AutoDiscovery for generating and testing hypotheses, Theorizer for synthesizing evidence into candidate theories, and Asta alongside them. Those systems can propose ideas, but judging whether an idea is genuinely new is typically handed to another LLM — a novelty judge whose model, prompt, evaluation format, reasoning budget and retrieval setup are chosen ad hoc by each team.
The benchmark's construction reflects that concern about validation. Instead of treating paper acceptance as a proxy for novelty, Ai2 mined ICLR 2026 reviews for passages where reviewers explicitly praised or disputed originality. Accepted papers in the top 10% of their area whose reviewers positively identified novelty, with no dispute, formed a 154-idea high-novelty pool; rejected papers in the bottom 10% with originality concerns and no positive novelty signal formed a 145-idea low-novelty pool. An annotator agreed with the extracted signal polarity in 47 of 50 cases.
A second setting paired the 154 human ideas with 154 produced by a simple LLM generator, with the caveat that the generated ideas are assumed less novel — weak labels, not verified judgments. An expert who reviewed 30 such pairs, weighted toward cases the strongest judge got wrong, preferred the human idea in all 30 and judged none of the generated ideas novel. Ai2 notes that many core findings do not depend on the labels at all: if two reasonable evaluation setups give opposite answers for the same pair of ideas, that disagreement itself reveals instability.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Paul Gillin said at EVOLVE26 that Cloudera is positioning itself as an "anywhere cloud for AI," extending clou…
On Latent Space, Anthropic's Katelyn Lesse and Angela Jiang detailed the Claude Platform's architecture, inclu…
Google Deepmind introduced Genie 4, a real-time world model that generates sound directly, including backgroun…
Oracle said it will deploy Google TPU AI chips in Oracle Cloud Infrastructure, providing the power, cooling an…
OpenAI released GPT-6.1 Terra, pitched at image and screen understanding, PC operation, and natural writing, a…
Apple's Oct 27 refresh brings the M6 to a $1,499 iMac and $1,999 14-inch MacBook Pro, both shipping Nov 6 with…