What happened
Apple researchers have introduced Visual Concept Inference from Sets (VICIS), a task that evaluates whether AI vision-language models can learn shared visual concepts from sets of example images and apply those concepts to new inputs. The researchers found that current state-of-the-art models perform poorly on this task, often ignoring visual context or producing biased outputs.
Why it matters
Vision-language models are widely used but struggle with reasoning from visual examples alone—a capability needed for tasks like generating variations of a concept shown through images. The work identifies a concrete gap in how these models learn from visual context rather than text, which could inform development of more capable AI systems for image understanding and generation.
What to watch
The researchers propose a training framework and architecture to address this gap. Their model was tested on synthetic data and large-scale ImageNet/WordNet datasets, and showed improved accuracy and diversity in outputs while generalizing to unseen concepts and modalities such as sketches.
Summaries like this, in your inbox every morning.
Vision-language models have become central to modern AI applications because they can follow complex textual instructions. However, this strength in text-based reasoning masks a fundamental weakness: the ability to reason from purely visual examples. The VICIS task targets this gap directly. Rather than relying on language descriptions, a model must observe visual patterns across multiple example images and extract the unifying concept—then apply it consistently to generate new images.
The poor performance of current state-of-the-art models on VICIS reveals that visual concept learning from examples is not an emergent property of scaling or instruction-following capability. The models either discount the visual examples in favor of textual biases or generate outputs that lack coherence with the provided context. This suggests that the architecture and training dynamics of today's vision-language models are not well-suited to this type of visual reasoning, a challenge the researchers address through a new training framework and architecture design.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
TOPPAN Holdings and Keio University ran a quantum-computer and generative-AI proof-of-concept from February 1…

Black Forest Labs released FLUX 3 Image Klein as open weights on October 15, 2026 — a 5.6B-parameter model for…

Krea opened the beta for Krea 3, which does end-to-end 2K edits in under 8 seconds, accepts up to 8 reference…
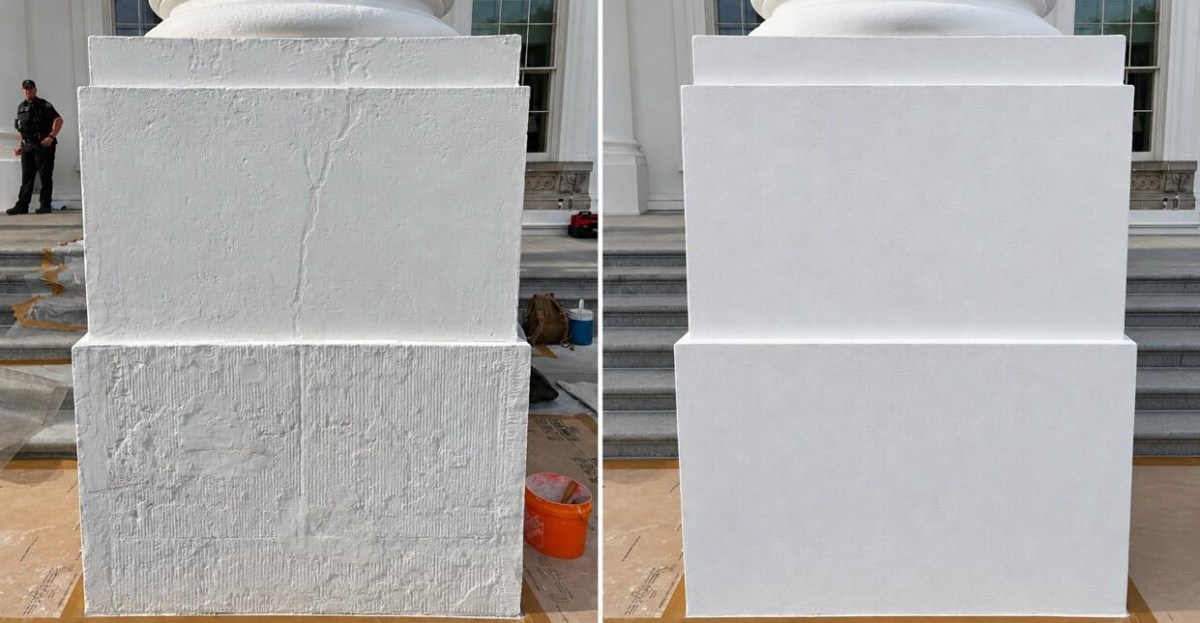
President Donald Trump posted photos on Truth Social showing White House renovations, but one comparing an old…
Universidad de Córdoba (UCO) has published a guide titled "AI NSFW 2026: reference tools, reusable workflows a…
Black Forest Labs released FLUX 3 Image Klein, a 5.6-billion-parameter open-weights model for text-to-image ge…