What happened
Researchers applied SimpleLoRIF to Tulu 3, removing the top 20% of examples most gradient-aligned with unsafe outputs to build SafeTulu, which cuts GCG attack success by up to 22% across Qwen, Llama, and OLMo.
Why it matters
Standard content screens evaluate surface signals and cannot spot ordinary-looking examples that push a model toward unsafe gradient directions, so fine-tuning teams may need gradient-space inspection to catch hidden safety erosion.
WHO IT HITSAI safety teams and engineers fine-tuning instruction models on curated but unvetted datasets are most directly affected, as the method offers a way to screen training data before a run locks in weakened guardrails.
Summaries like this, every morning.
The research addresses a gap in fine-tuning safety: standard content filters and LLM-as-judge screens check surface-level signals and cannot tell which training examples push a model toward unsafe gradient directions. SimpleLoRIF closes part of that gap by restricting backpropagation to the final four transformer blocks to embed training examples, making gradient-space inspection scalable to datasets of roughly one million examples. Applied to Tulu 3, it removed the top 20% of examples most gradient-aligned with unsafe model outputs, creating SafeTulu.
The resulting dataset reduced GCG adversarial attack success by up to 22% across Qwen, Llama, and OLMo model families, with detection AUC reaching up to 0.865, while largely preserving or improving downstream capabilities. The authors also flag tool-execution failures and narrative arithmetic as under-studied sources of safety degradation in instruction-tuning data. SafeTulu and a Hugging Face Space for custom filtering are publicly released alongside the paper, which is attributed to Saket Reddy, Amro Abbas, Anshuman Suri, Ari Morcos, David Schwab, and Pratyush Maini.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
In a bicycle-route decision test on an Nvidia DGX Spark, TypeSafe AI's Jev finished first against Ollaya runni…
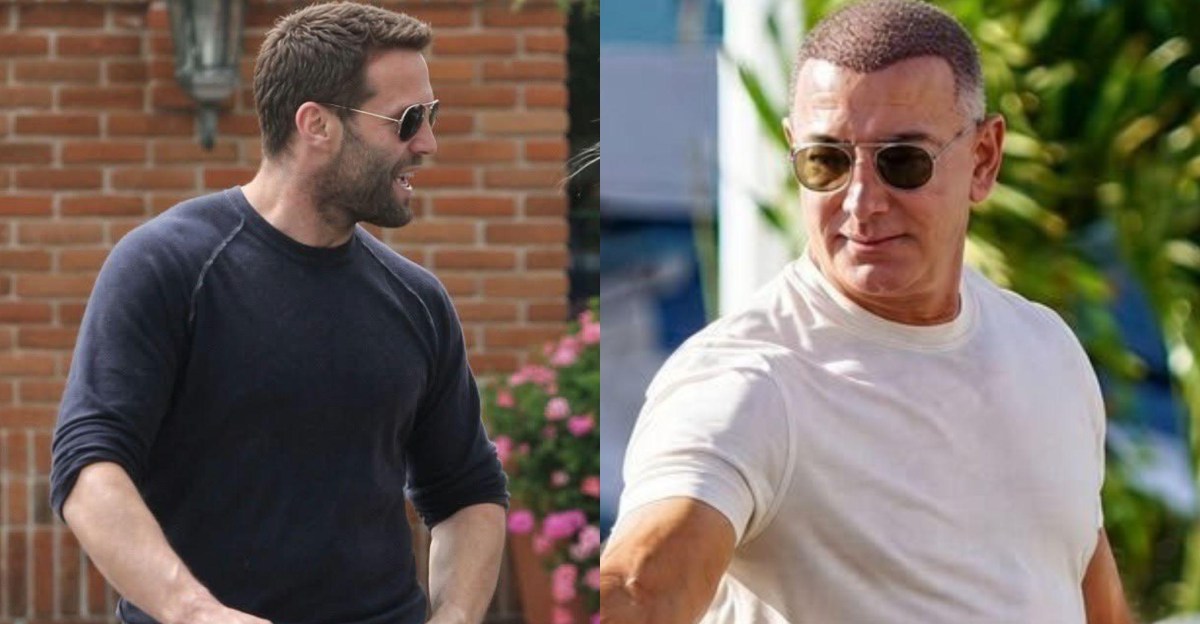
Viral images of Jeff Bezos and Jason Statham with fuller hair are fake, The Verge's Jess Weatherbed confirmed…
Nexus Mods will require mod authors to declare whether AI was used in their work; 'AI-assisted' mods must incl…
Anthropic published research, code and a technical spec on GitHub for FlashProve, an open source system that g…
Google will turn off Search for schools that reject its A.I
Dell and Microsoft expanded their partnership to integrate Dell Automation Platform and Private Cloud with Azu…