Researchers propose DualOpt, a novel optimizer that uses different strategies for two training paradigms: real-time layer-wise weight decay for training from scratch, and weight rollback integrated into the optimizer for fine-tuning pre-trained models.
For fine-tuning, weight rollback is incorporated into each weight update step to maintain consistency in weight distribution between upstream and downstream models, mitigating knowledge forgetting. Layer-wise weight decay dynamically adjusts rollback levels across layers to adapt to varying downstream task demands.
Experiments across image classification, object detection, semantic segmentation, and instance segmentation demonstrate state-of-the-art performance. Code is available at the provided URL.
Summaries like this, every morning.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Amazon added AI agents to AWS Marketplace that find products, review contract terms, check vendor security and…
In a Databricks blog series, Principal Forward Deployed Engineer Molly Nagamuthu described four patterns — det…
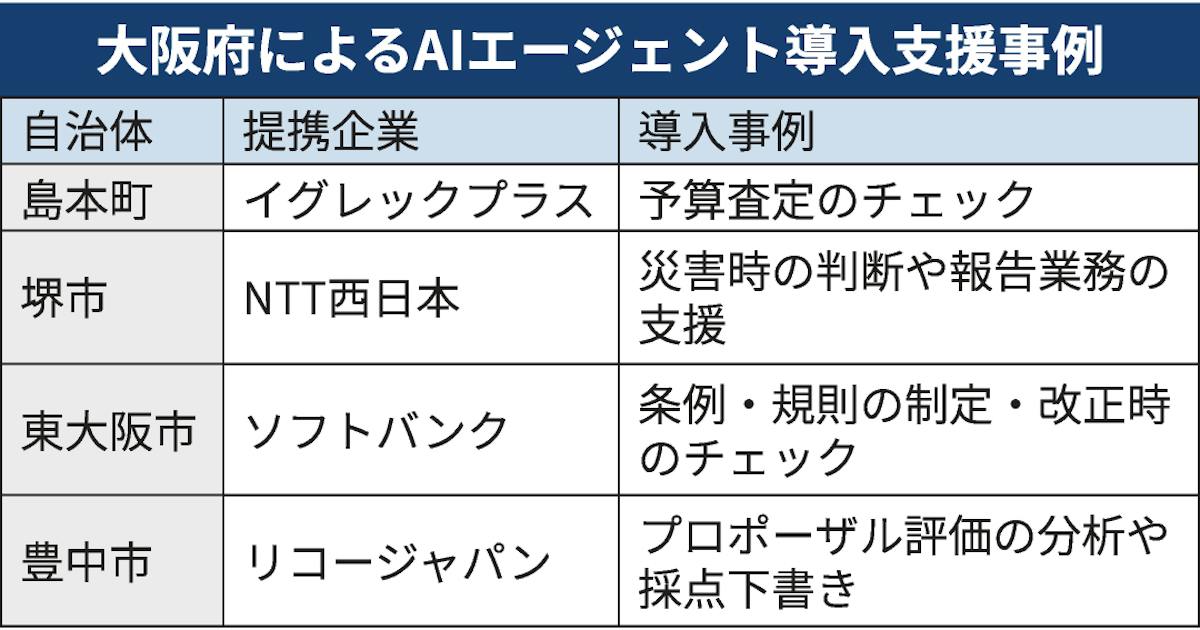
Osaka Prefecture is offering to help municipal governments adopt AI agents (software that acts on tasks autono…
On a post-earnings call, Tencent President Martin Lau said Commerce's Nov 16 interim rule curbing remote acces…

Google added a collapsible sidebar to its desktop homepage worldwide, showing users' AI Mode search history wi…
The Information reports Meta plans to price the Muse Charm, a small screen device for chatting with its Muse A…