What happened
GIGAZINE installed Ollama on a Windows PC with an Intel Arc Pro B70 32GB and ran Qwen3.8-27B, confirming via 'ollama ps' that it loaded '100% GPU'.
Why it matters
A single desktop with that graphics card can hold the entire 27-billion-parameter model in GPU memory, so one machine can act as a local AI server for others.
Summaries like this, every morning.
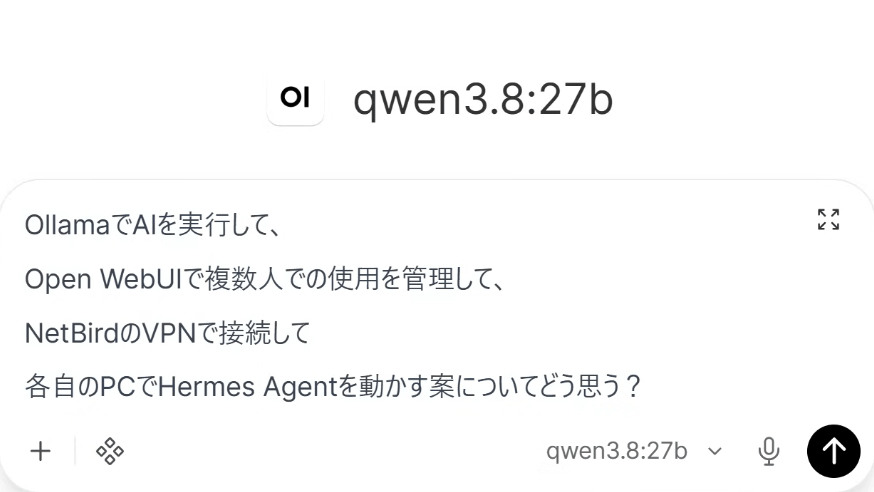
The first part of a planned build is one high-performance Windows PC acting as an AI server for other machines, with browser control handled by an AI agent called Hermes Agent and only the inference work delegated to the server. The intended stack pairs Ollama for running models with Open WebUI for API relay, user management and usage logs, plus NetBird for VPN connectivity.
In this installment the author installs Ollama and runs Qwen3.8-27B on a PC with an Intel Arc Pro B70 32GB. After the test, a second PowerShell window running 'ollama ps' showed '100% GPU', meaning the model fit entirely in graphics memory. The default context size was 32k, which the author raised to 64k because Hermes Agent requires it. The test prompt also showed a limitation: the model did not know its own name but still worked out VRAM needs from the 27B parameter count and 4-bit quantization, and token output was very fast.
The remainder of the setup, including individual user accounts, is left for the next installment.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Meta deployed Catching JiTTests — LLM-generated tests designed to fail on buggy code — and says they caught 74…
Ben Tossell wrote that he has felt stuck for about 10 months, circling on business ideas, and will spend the n…
Anthropic filed its S-1 to list on the Nasdaq, targeting a valuation of $1.5 trillion to $2 trillion, and disc…
Anthropic's S-1 discloses revenue grew fourteen times to $16.3 billion between the first half of 2026 and the…
Wabi, now describing itself as a 'personal agent,' said it raised $55 million at a $1.25 billion valuation, in…
Crux Labs launched with over $6 million in funding led by Benchstrength and Misneach, with Analog Ventures and…