What happened
A Japanese edition of Machine Learning for High-Risk Applications (O'Reilly Japan, 2025) describes how Zillow's algorithmic iBuying switch led to over $500 million in write-downs and about 2,000 layoffs in 2021, and shows an XGBoost model whose overall AUC of 0.78 hid a segment with a false positive rate of 1.0, meaning it mispredicted every non-delinquent as delinquent.
Why it matters
The book argues that good test-data performance and intended real-world effect are fundamentally different problems, so engineers and model owners who rely on aggregate scores may miss severe, localized failures.
What to watch
The book notes its own limitations, including a reliance on pandas 1.3 and a deliberate exclusion of generative AI, while the EU AI Act takes effect in August 2024 and will be phased in from August 2026, so practitioners need to assess whether its framework can be adapted to their own models and regulatory context.
WHO IT HITSEnterprise IT teams and data scientists deploying or managing ML models in high-risk areas such as hiring, credit, and biometric identification will need to move beyond aggregate accuracy metrics and plan for segment-level checks and kill switches.
Summaries like this, in your inbox every morning.
The book builds its argument from case studies of real incidents. Zillow's iBuying failure is presented as an example of raising a system's importance without raising its governance, after the company removed expert review and later took over $500 million in write-downs and laid off about 2,000 employees. A separate XGBoost example shows how an acceptable overall AUC of 0.78 can conceal a segment where the false positive rate is 1.0. The book sets these against a regulatory backdrop that includes the EU AI Act's 2024 effective date and phased enforcement from August 2026, and it deliberately declines to cover generative AI because the authors believe failure modes and controls are not yet well established there. A red-teaming exercise reports that a constrained model was easier to extract than an unconstrained one, illustrating that defenses can create new attack surfaces. The outcome likely hinges on whether organizations treat documentation, independent testing, and team diversity as core engineering requirements rather than afterthoughts.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Anthropic CEO Dario Amodei is reportedly targeting a pre-Thanksgiving IPO, even as Oura postpones its offering…
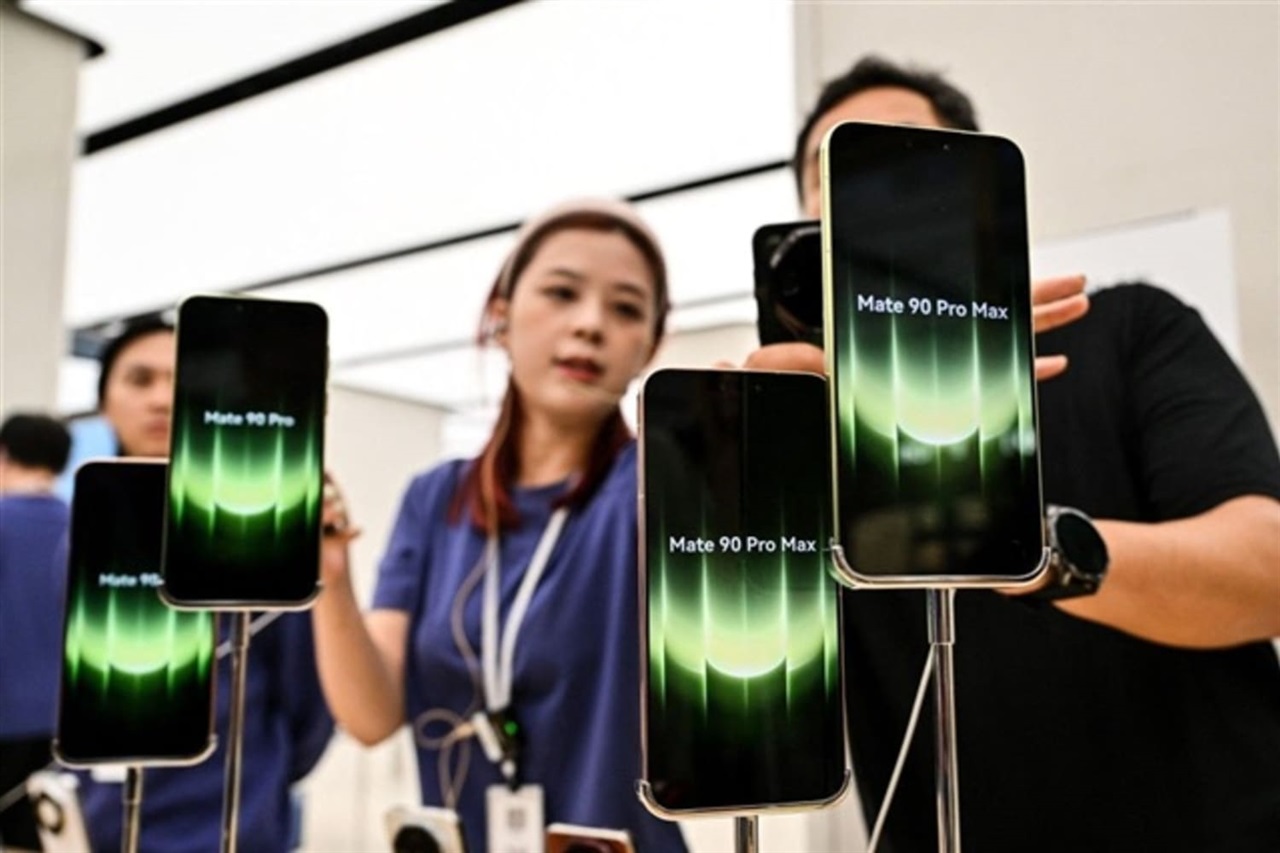
Huawei raised flagship prices by up to US$200, citing an average US$200 rise in per-unit manufacturing costs…
SpaceX stock rose 6.1% through 11 a.m
Airbnb CTO Ahmad Al-Dahle said about half of support tickets are now resolved purely by AI, 60% of code is AI-…
At Fortune's AIQ Summit, Booking Holdings CFO Ewout Steenbergen said hyperscalers spending hundreds of billion…
Ben Affleck told Bloomberg that once people actually use AI, the "It's going to kill us all" narrative looks l…