What happened
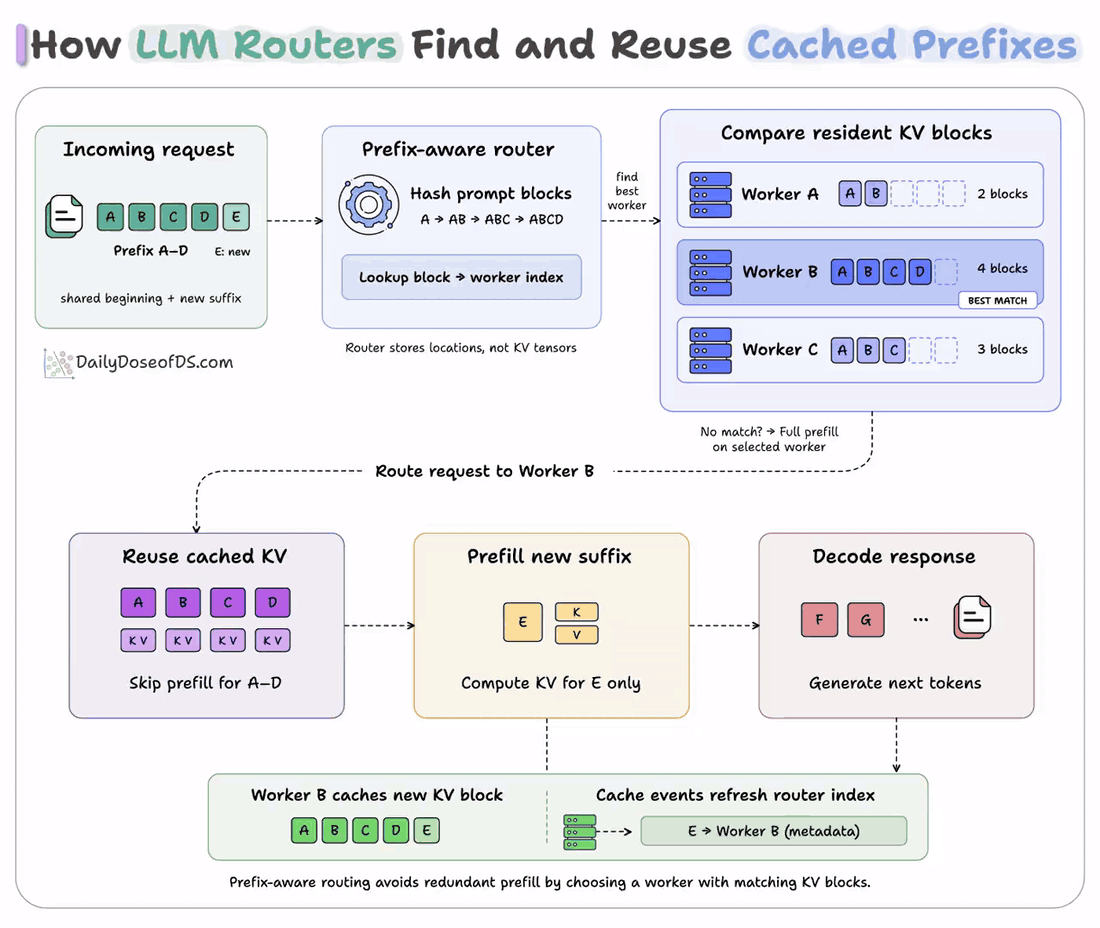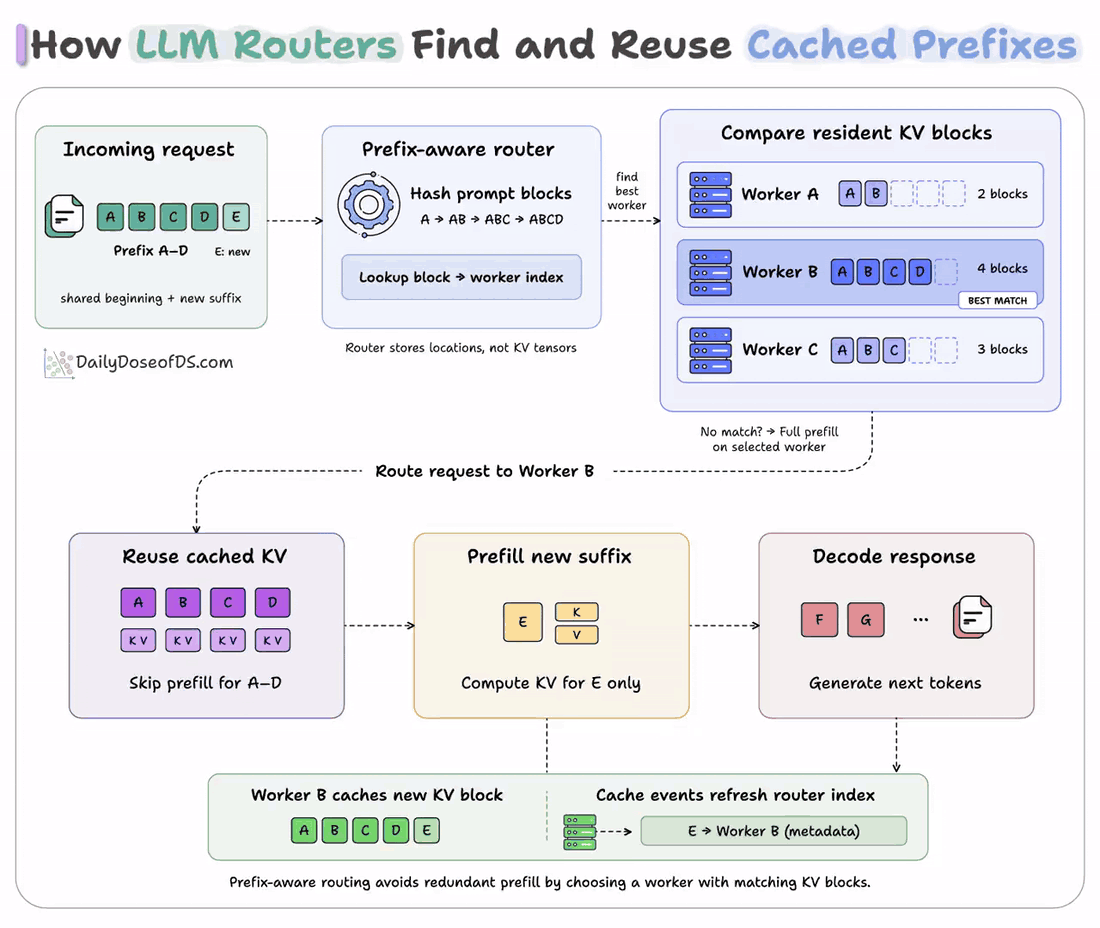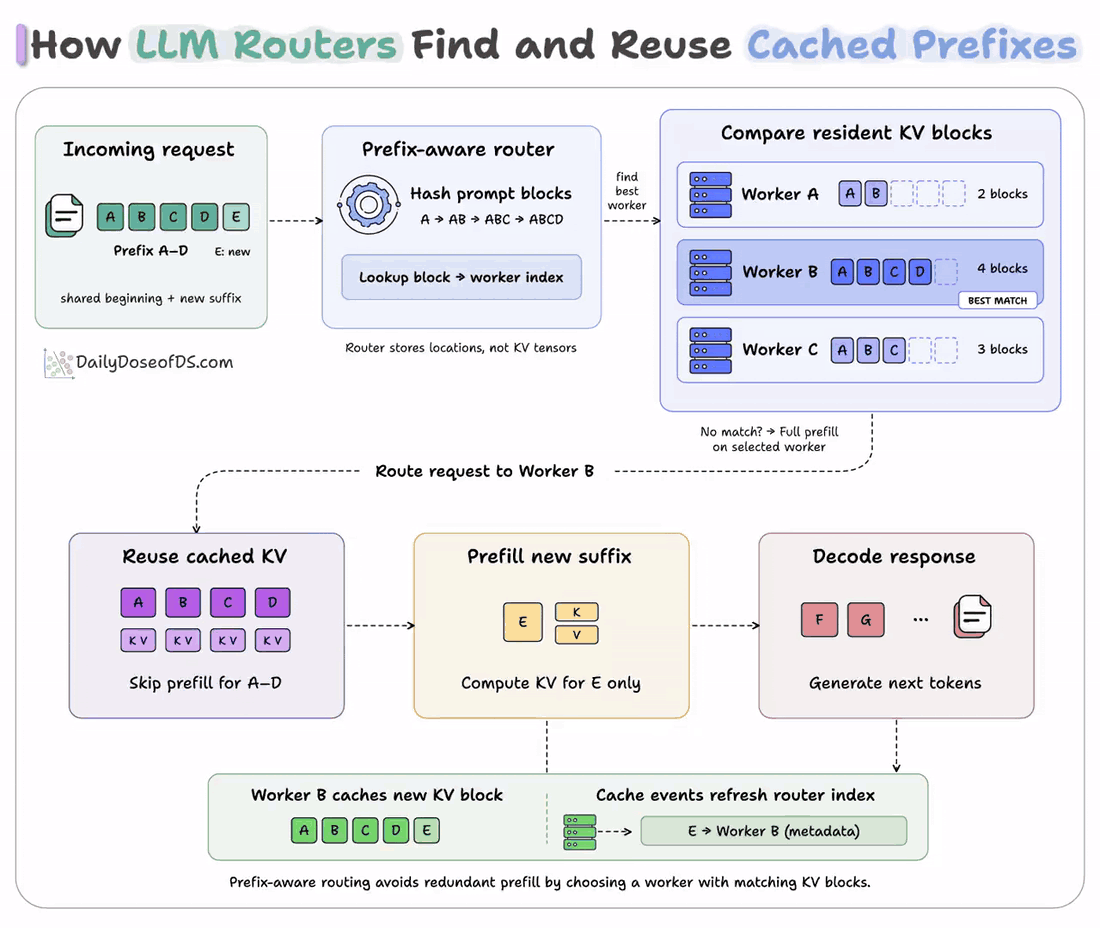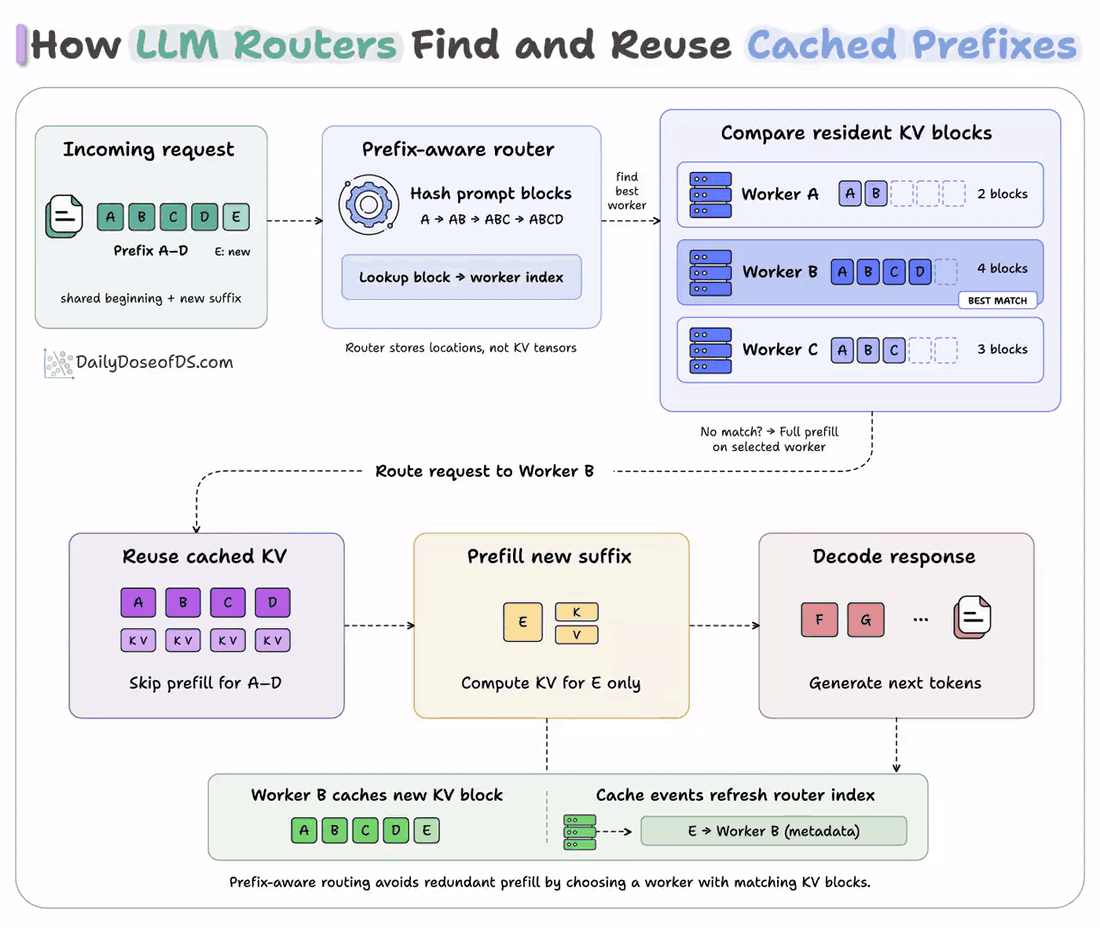
In llm-d tests on 8 vLLM pods across 16 H100s, precise prefix-aware routing cut p90 time to first token from 92.6 seconds to 0.54 seconds versus random routing, and throughput roughly doubled from 4,429 to 8,730 tokens/s.
Why it matters
The benchmark shows that where a router sends a request can matter more than how evenly work is spread, since avoiding a full recompute of shared prompt prefixes is what produces the speedup.
Summaries like this, every morning.
The llm-d benchmark places routing decisions at the center of LLM serving performance. The test workload simulated 150 customers, each with a 6,000-token shared context and 5 users sending 1,200-token questions, at 3 to 60 QPS. Those shared prefixes needed about 73% of the cluster's KV cache, roughly 6x what one pod could hold, which is the condition under which routing choices matter most.
The gap between routing strategies was wide. Random routing produced a p90 time to first token of 92.6 seconds, load-aware only 94.9 seconds, approximate prefix-aware 31.1 seconds, and precise prefix-aware 0.54 seconds. Load-aware routing did no better than random in this test, because each request landed on a GPU that had to recompute its prefix.
A later llm-d rerun on a newer vLLM, against a plain Kubernetes round-robin Service, showed a smaller gap, but p90 time to first token still dropped by more than 99%. All of this depends on the prefix cache itself working, and a timestamp at the top of a prompt breaks every block after it.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
WeSales launched the free "Gem 移行チェック" tool, which asks three questions and shows what carries over, what does…
Aries Zhou released Howler, an open-source macOS app that summons a parchment-style letter with Option+H, writ…
OpenAI doubled Work and Codex quotas on the Pro 100 and Pro 500 plans, and on Pro 200 doubled the lower quota…
Sources say an Accenture employee gave their personal Claude Code account administrative access to a DOD NIPRN…
Google Gemini now lets all users generate, preview, and edit PDFs, Google Docs, Google Sheets, slide decks, Ma…
Dream, founded by ex-Palantir executives Andy Elder and Arjun Mathur, emerged from stealth with $17 million in…