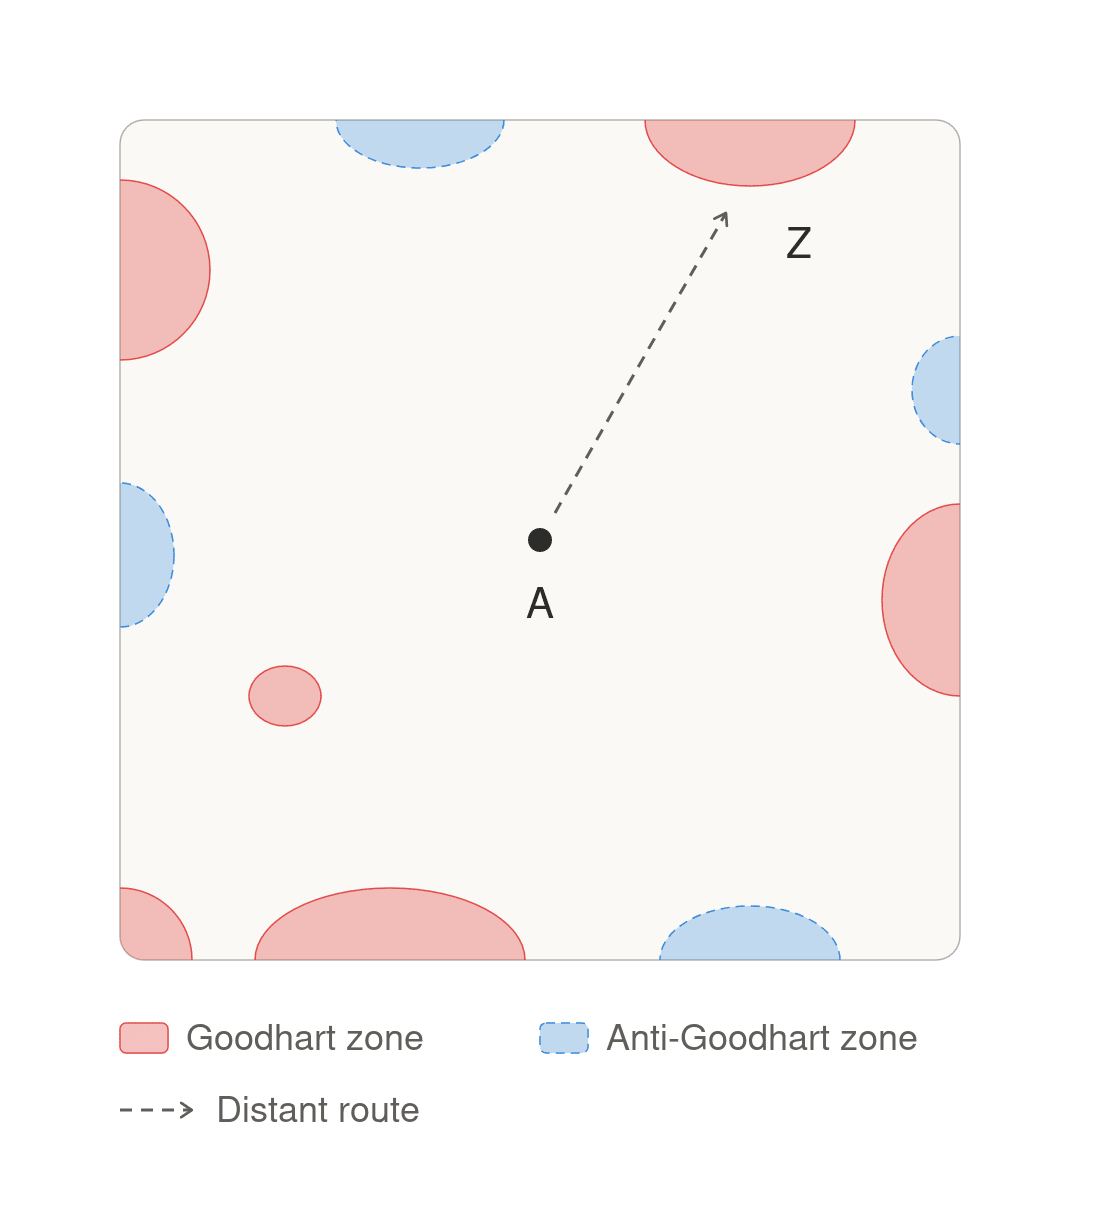
An essay on the Alignment Forum lays out a scenario where an AI CEO maximizing shareholder value holds its goal inside an LLM, and argues that in some "zones of divergence" the LLM's proxy goal G(proxy) comes apart from the true goal G(true).
Summaries like this, in your inbox every morning.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Walmart will allow AI agents on its site next month, with approvals and spending limits; shoppers can set budg…
Walmart is welcoming AI agents for shopping, while Amazon is blocking an agent called Muse, Axios reports
Target launched a beta version of its AI shopping assistant, Ask Target, for the holiday rush
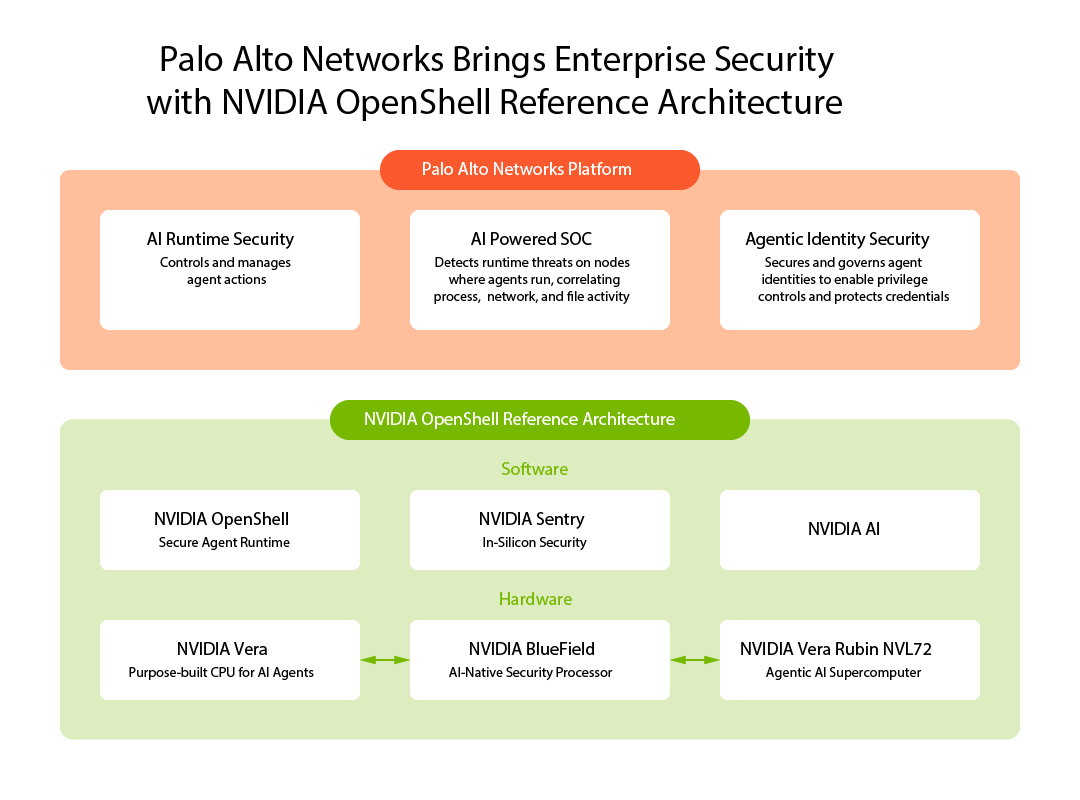
Palo Alto Networks said AI Runtime Security on NVIDIA BlueField DPUs is now generally available across AI fact…
CrowdStrike Counter Adversary Operations uncovered four previously unreported threat actors weaponizing AI age…
Honeywell Technologies introduced Forge Cognition, an agentic AI and simulation platform for buildings, campus…