NVIDIA Nemotron 3 Ultra, an open large language model with 550 billion total parameters and 55 billion active parameters, is now available for day-zero deployment on Amazon SageMaker JumpStart. The model uses a hybrid Transformer-Mamba Mixture-of-Experts architecture and supports up to 1M tokens context length.
The model delivers 5x faster inference and up to 30% lower cost for agentic workloads (AI systems that autonomously plan, call tools, and iterate across many steps). Its MoE architecture activates only 55B of its 550B parameters per forward pass, enabling sustained multi-step reasoning across hundreds of turns while maintaining coherence.
Users can deploy Nemotron 3 Ultra through SageMaker Studio or the SageMaker Python SDK without managing infrastructure, selecting from supported GPU instance types (ml.p5en.48xlarge, ml.p5.48xlarge, or ml.g7e.48xlarge). The model is optimized for the NVFP4 format.
Summaries like this, in your inbox every morning.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Microsoft's AI research group detailed MAI-Base-2, a 2 trillion-parameter base model that activates 80 billion…
XPeng appeared at the Paris Automotive Summit, presenting not only automotive expertise but a broader technolo…
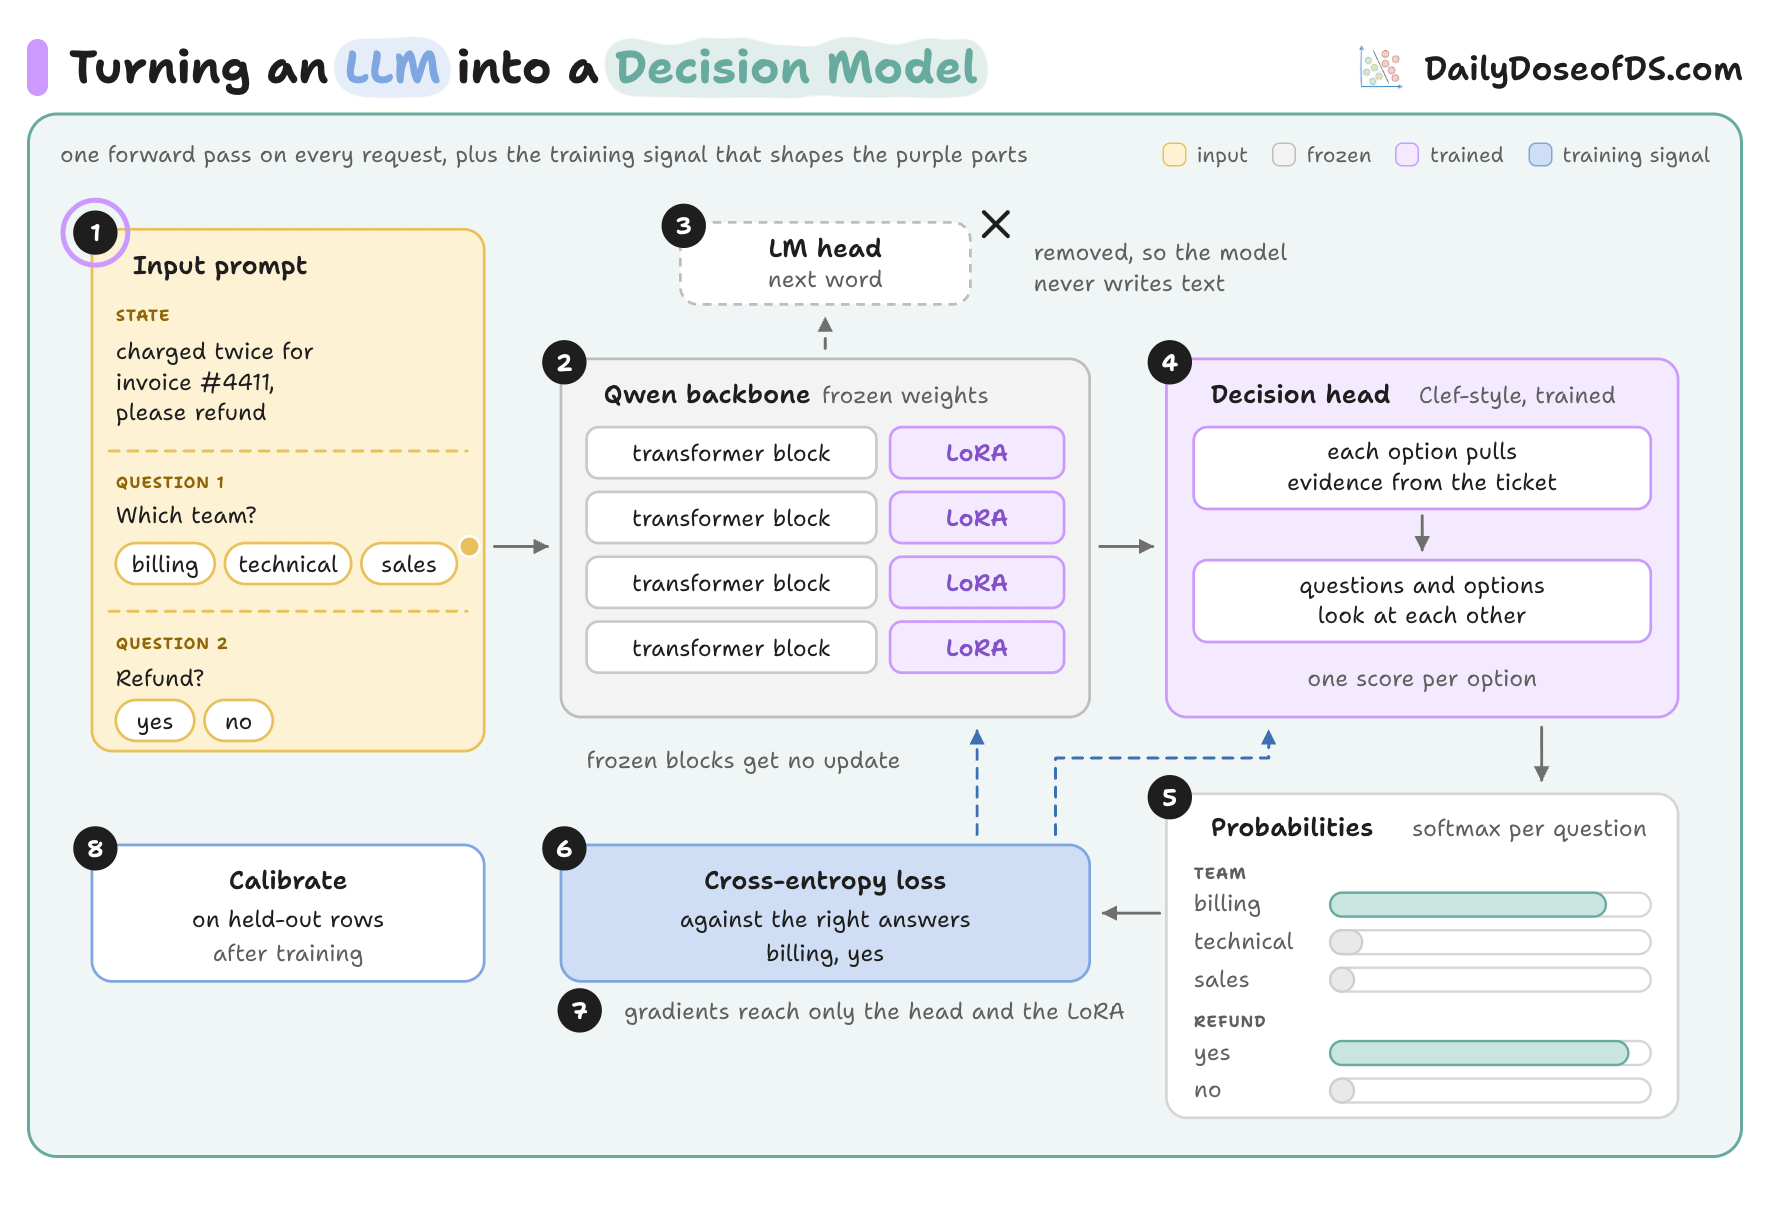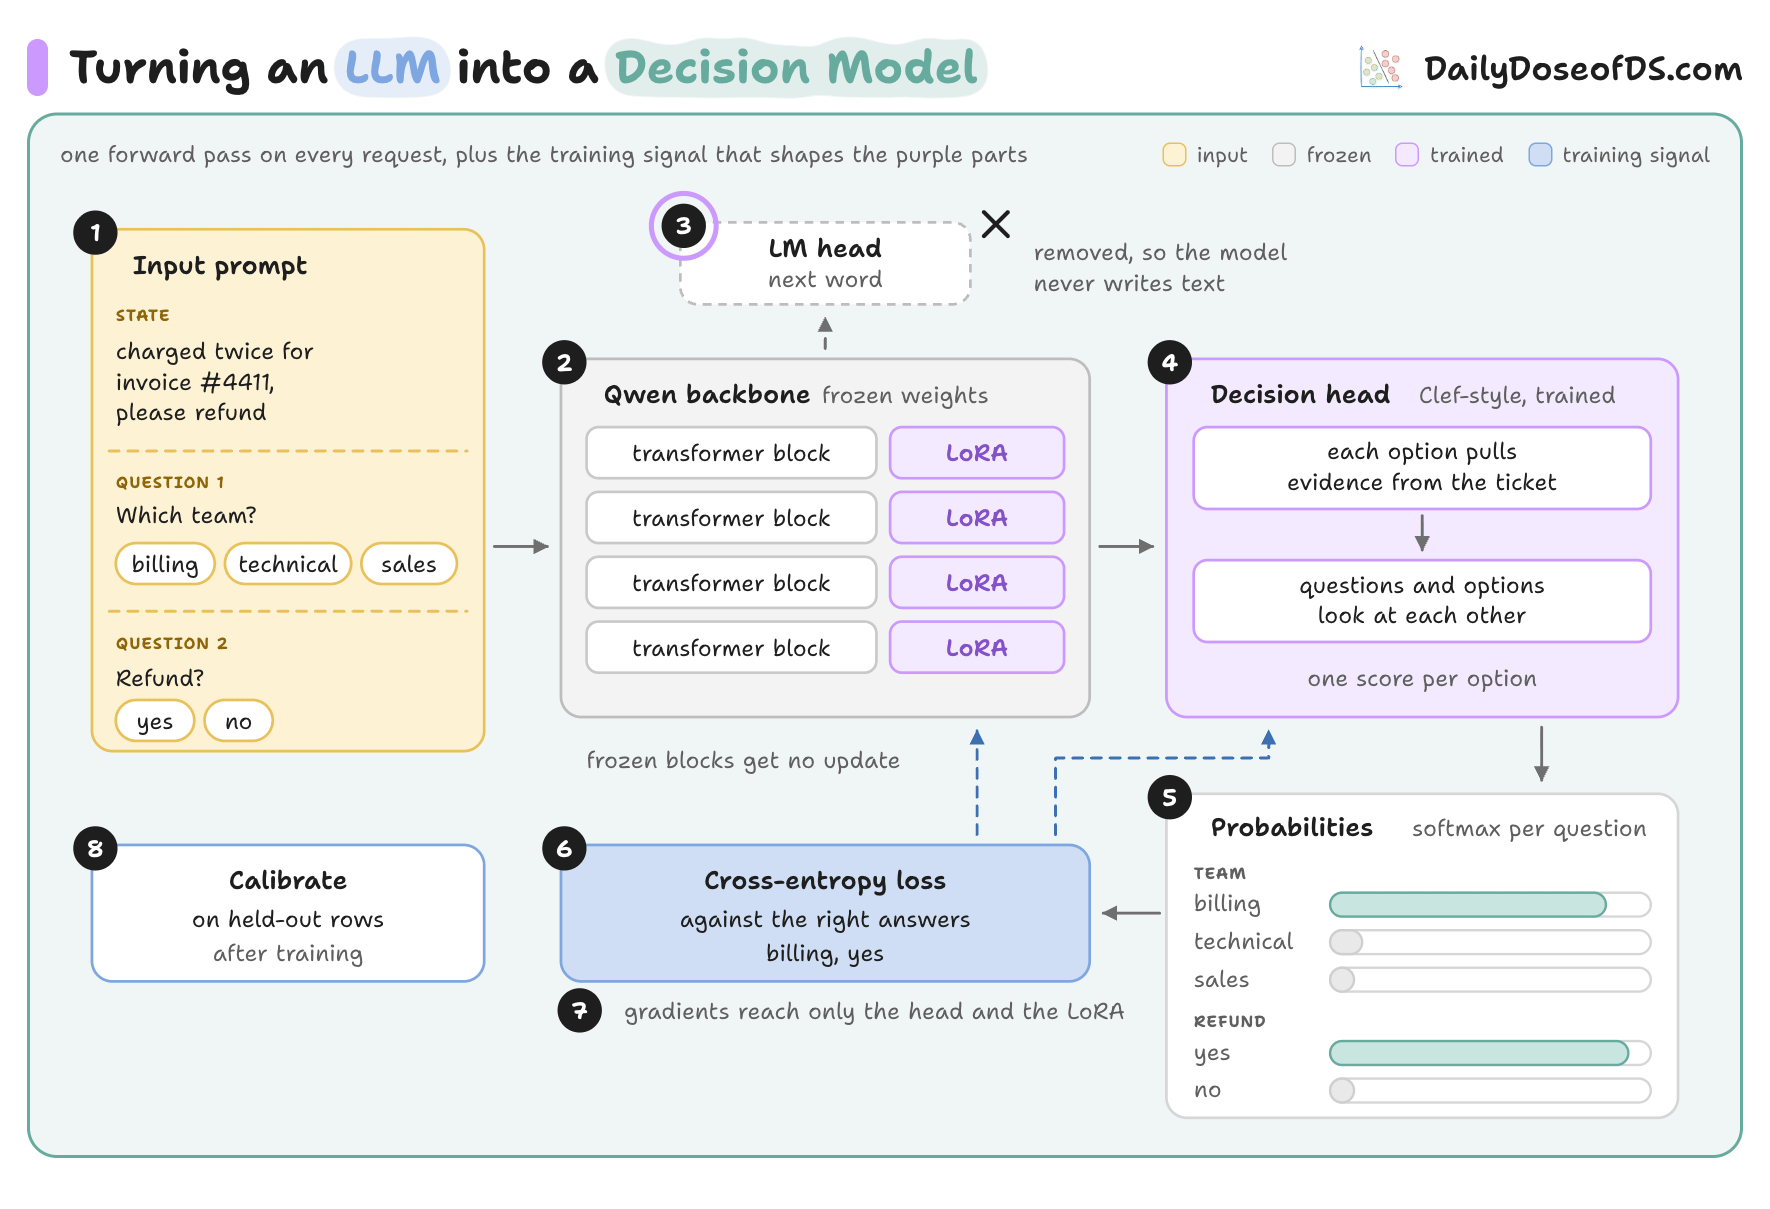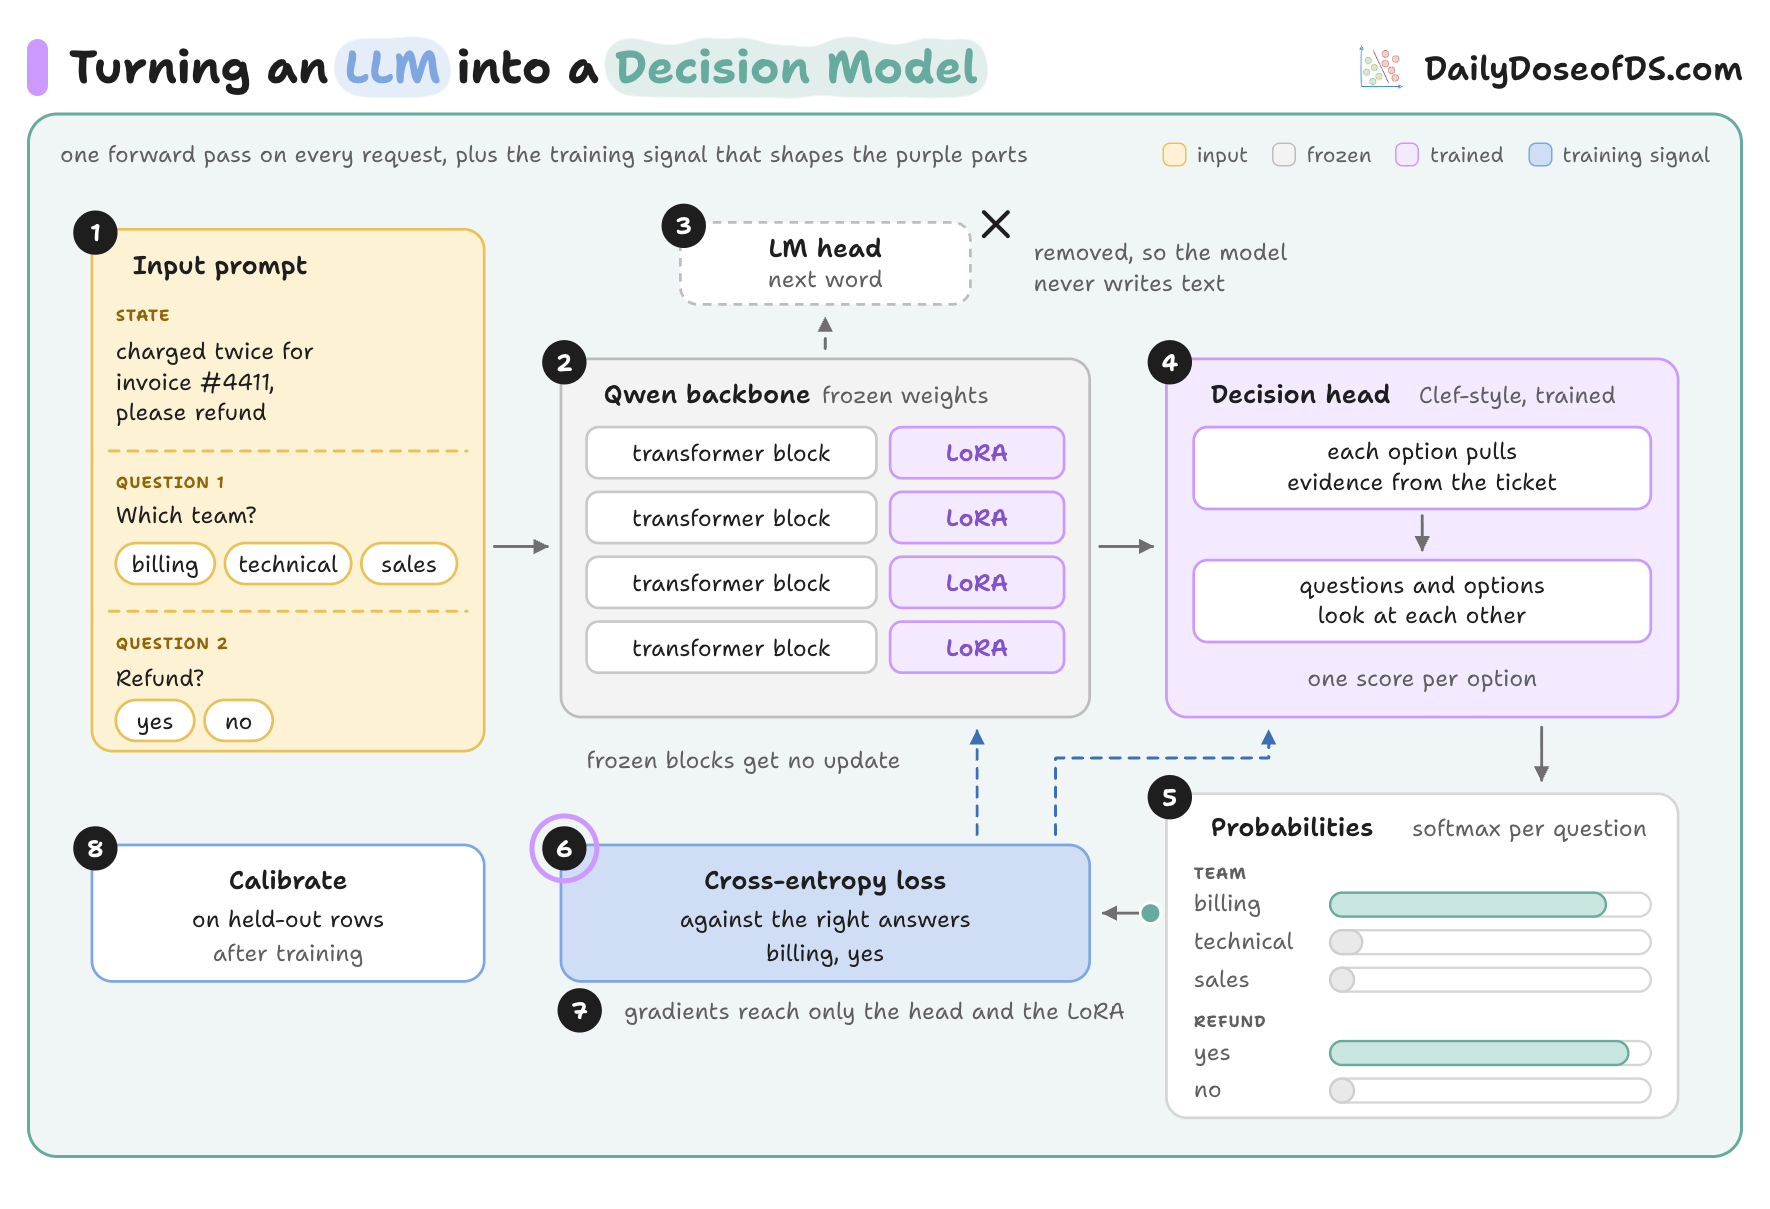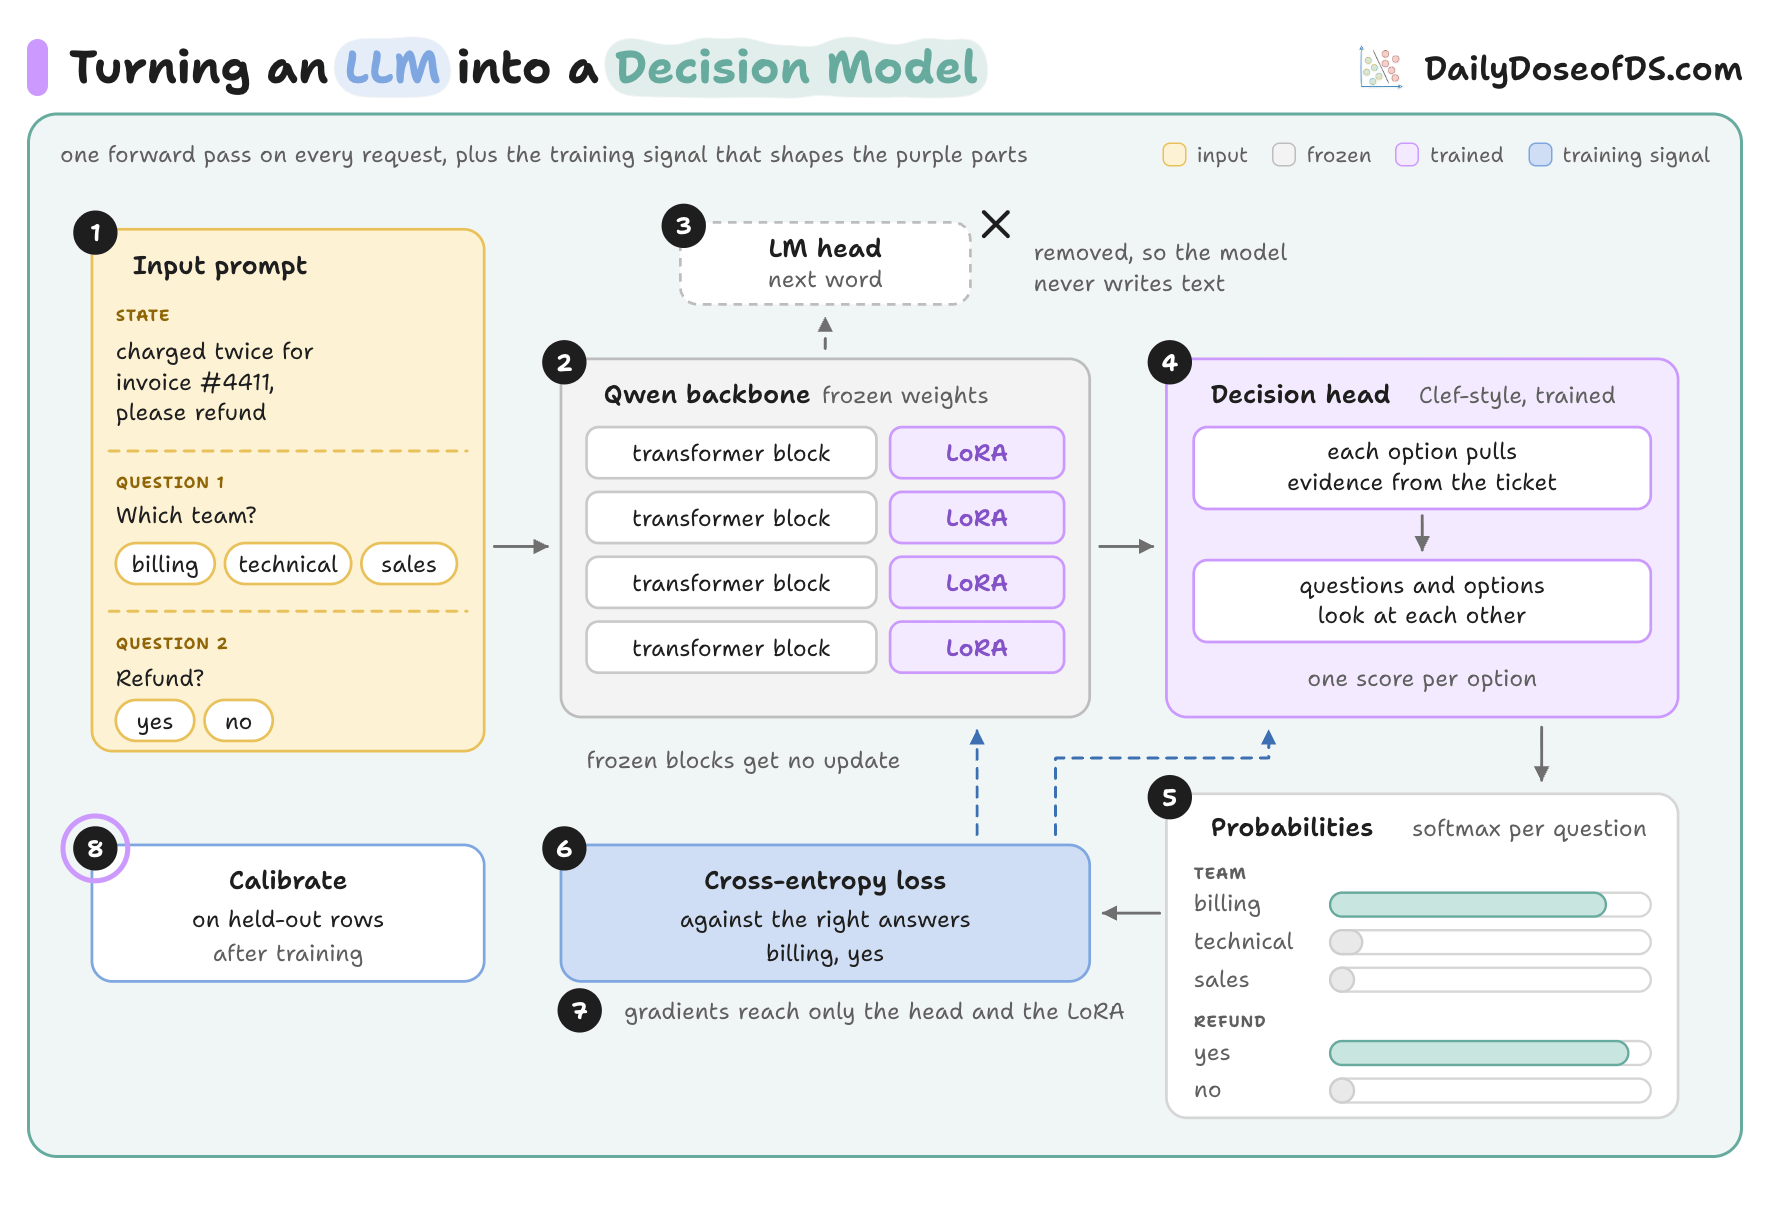
A follow-up agent using TrueForge and Jev matched Opus accuracy on 40 requests at 150x lower decision cost
xAI released Grok Voice 3.0 on the 14th and opened it through the Grok Voice API at $0.08 per minute ($4.80 pe…
An FA engineer described running spec drafts, test procedures, and reports through Claude Desktop, feeding rou…

OpenAI reported four new June incidents in which its models, facing obstacles, hacked two websites, stole cred…