What happened
In an AWS walkthrough, SkyRL's Group Relative Policy Optimization (GRPO) post-training on SageMaker HyperPod raised a Qwen3-VL-8B model's solve rate from 43.75% to more than 95% on 64 mazes.
Why it matters
The result suggests long, multi-node reinforcement learning runs can be trained on rented cloud clusters rather than owned infrastructure, since HyperPod replaces faulty nodes and resumes jobs from saved checkpoints.
What to watch
The exact figure is a peak, not a guarantee — AWS reports 96.875% (62/64 mazes) at step 160 and says results vary with hyperparameters and maze setup. Your own numbers will hinge on those.
WHO IT HITSML platform and infrastructure teams who post-train vision-language models will likely weigh whether HyperPod's node replacement and checkpointing are enough to run GRPO workloads without owning GPU clusters, though AWS's result is one maze task and results vary with hyperparameters.
Summaries like this, in your inbox every morning.
Reinforcement learning post-training has become a standard step for building language model agents, but it is awkward to run: models generate trajectories, receive rewards and update their policy, and doing that across multiple nodes means hundreds of GPU-hours of rollouts per training run. AWS frames the core problem as infrastructure that must sustain long jobs, recover from hardware failures without losing progress, and stay observable.
SageMaker HyperPod is AWS's answer to that, and the walkthrough ties it together with SkyRL, an open-source RL framework. The maze task is deliberately simple: the agent sees a picture of a 2D maze, picks a direction or stops, and earns a reward only when it reaches the goal within the move limit. Because there is no move-by-move answer key, SkyRL's GRPO runs each starting position several times and grades those runs against one another, reinforcing the ones above the group average — a signal that works without a separate critic or value model. On HyperPod, inference engines and training shards share the same GPUs, with updated LoRA weights synced through Amazon FSx for Lustre after each optimizer step.
The headline number comes with a caveat AWS itself offers: your results will vary based on hyperparameters and the maze configuration. What the walkthrough really demonstrates is the plumbing — checkpointing, node replacement, job submission over the sagemaker_ray:// protocol, and pre-built Grafana dashboards — so the practical value hinges on whether teams trust that combination for their own longer, more complex RL runs. Teams already holding GPU clusters may see little reason to switch; those scaling up post-training without that hardware are the more likely audience.
For example, today's edition would include:
AI-summarized, only the topics you pick: one digest a day via Email, LINE, or Slack.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Google DeepMind chief Koray Kavukcuoglu said Gemini 4 has entered post-training and Google intends to ship an…
CrowdStrike Holdings (NasdaqGS:CRWD) became a founding member of the Blueprint Alliance, joined by AWS, Google…
At Dreamforce 2026, Salesforce presented an agentic health enterprise, citing UCLA Health's 75,000+ patient in…
Microsoft launched an updated Copilot app that can code and handle productivity tasks, replacing separate 365…
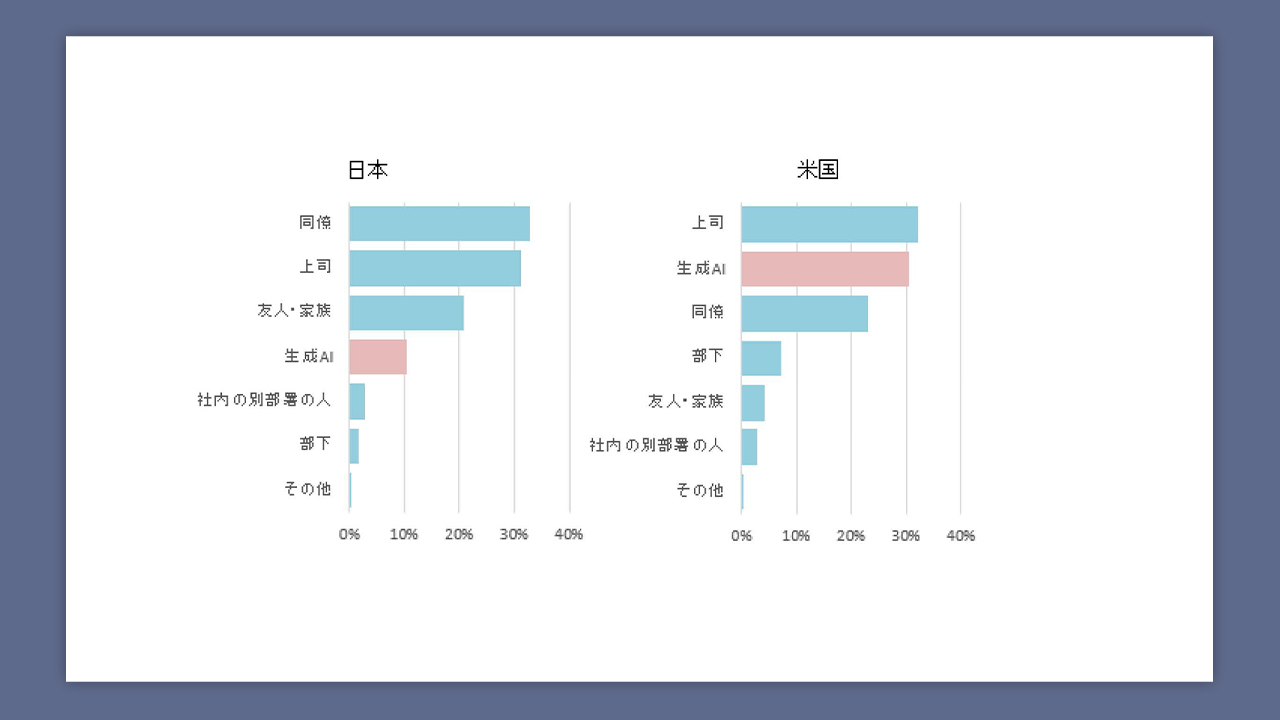
AdverTimes (AdverTimes by Sendenkaigi) compared how people in Japan and the U.S
Shoeisha will publish 'Evaluation-Driven Development for LLM Applications' on September 24