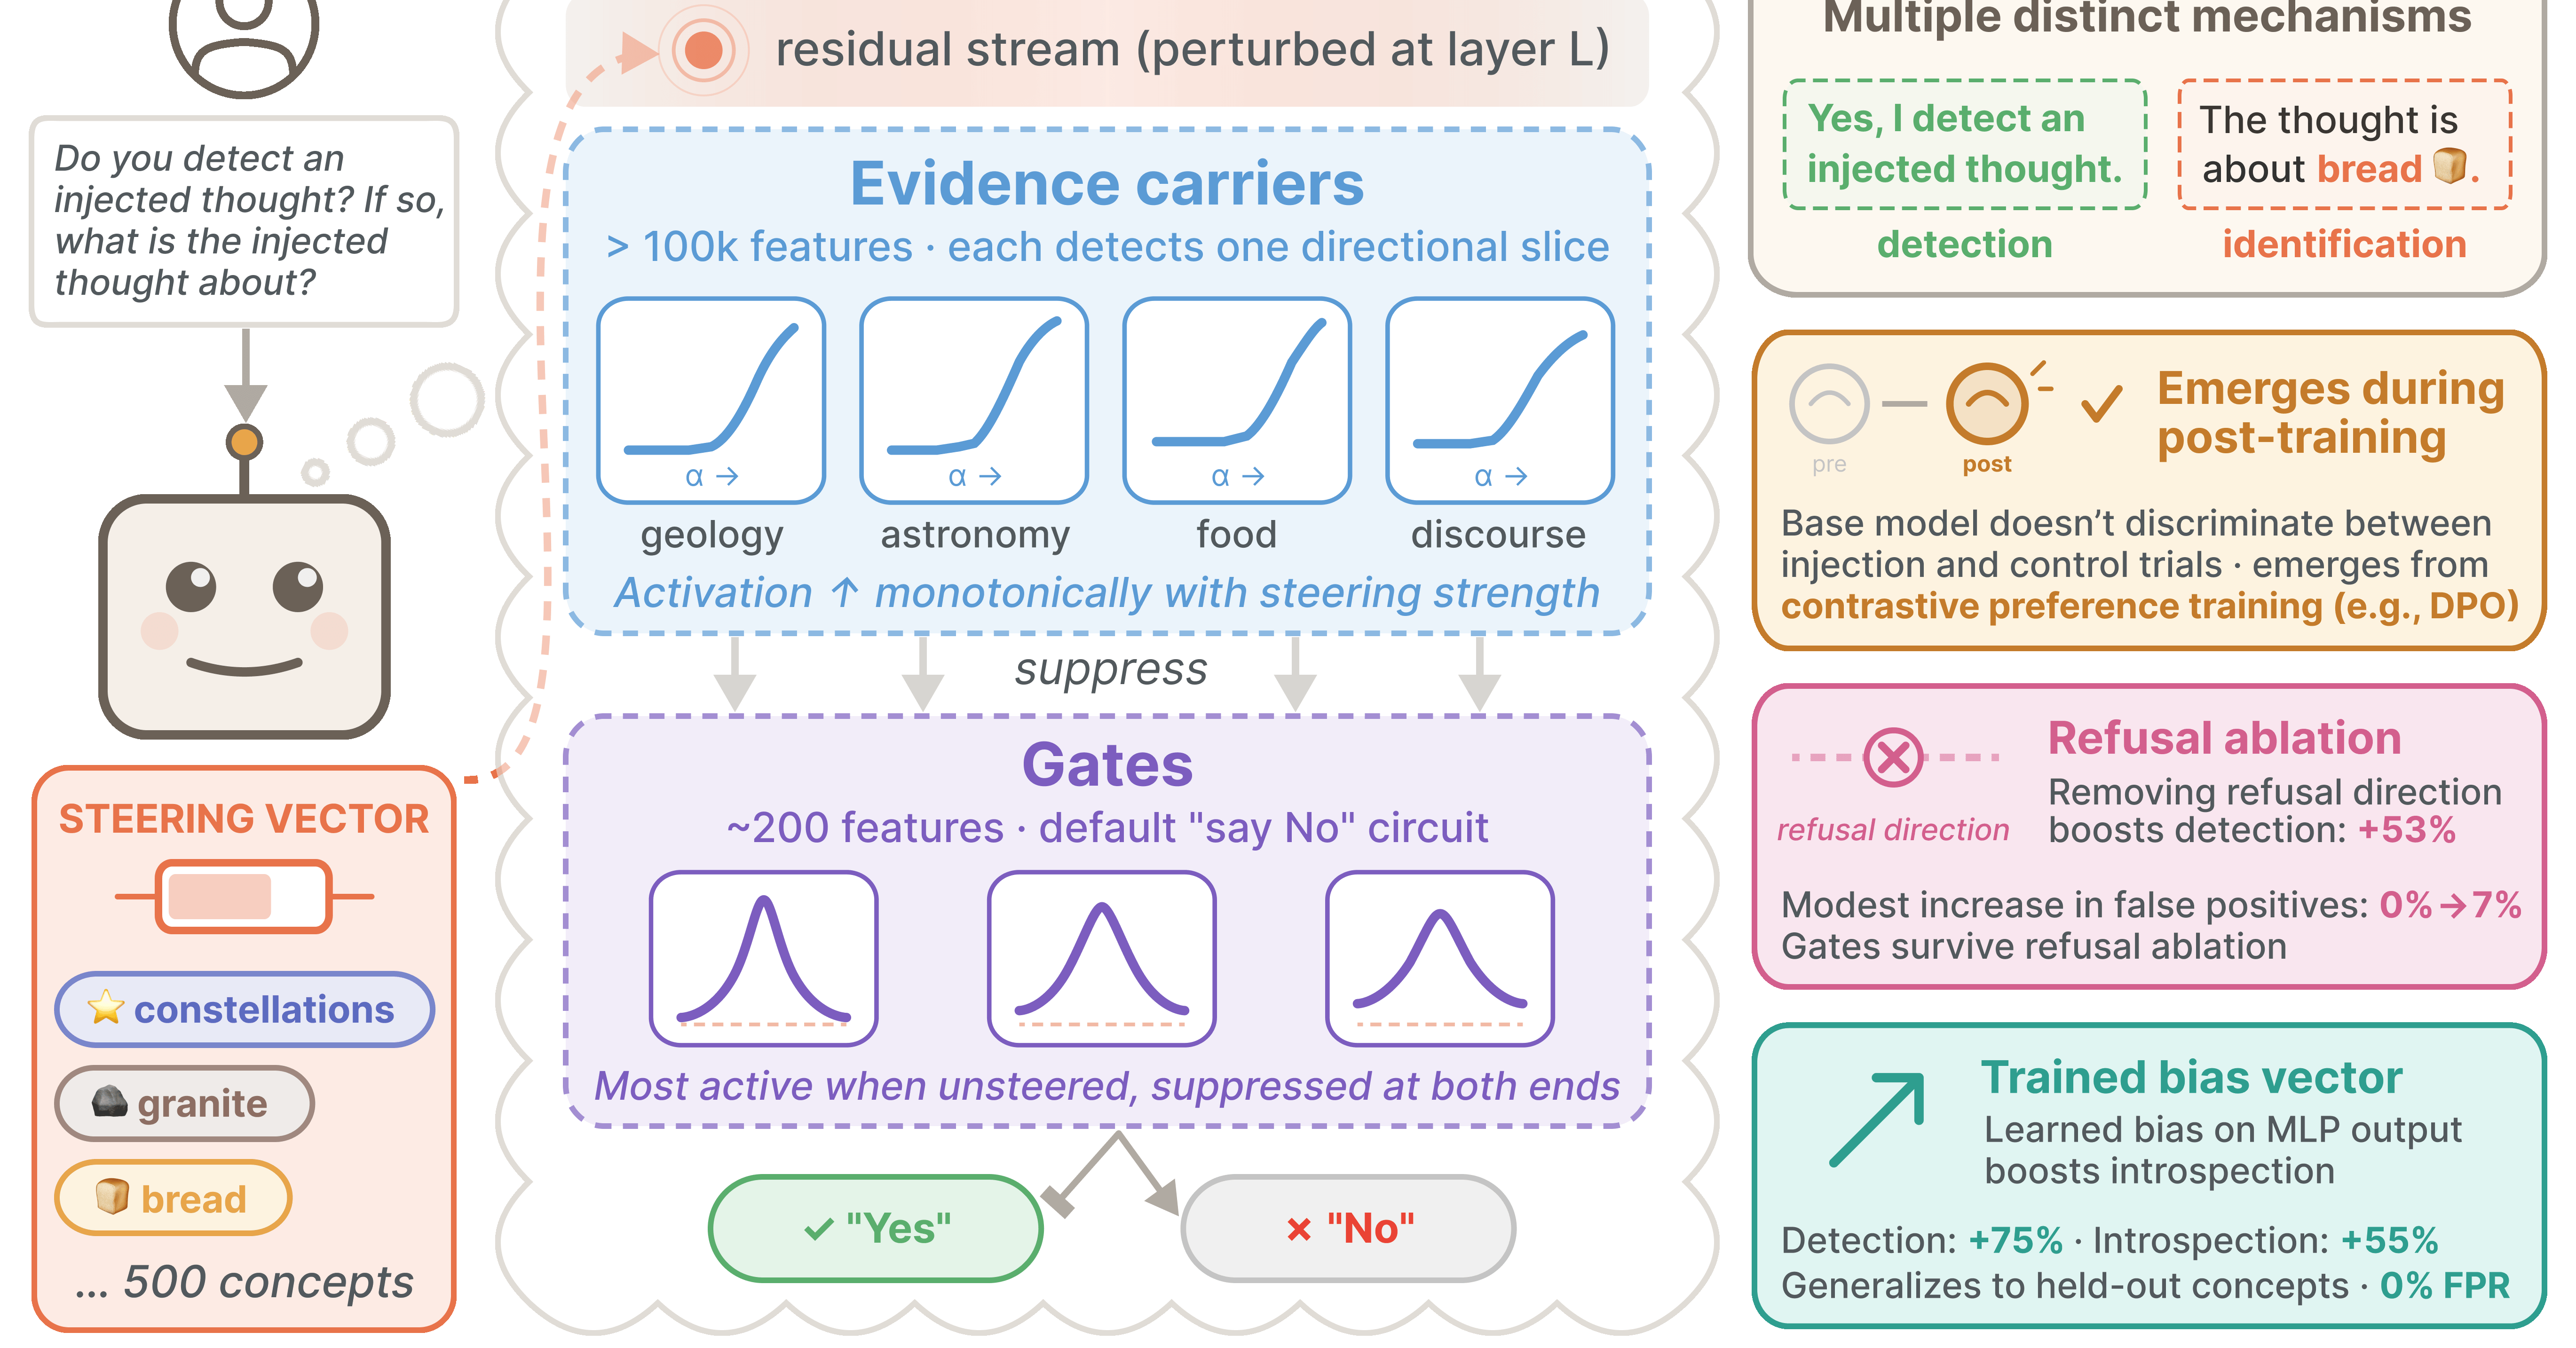
Uzay Macar and Li Yang led research showing open-weights models can detect injected concepts at modest nonzero rates with 0% false positives across different prompt formats
Summaries like this, in your inbox every morning.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Supermicro Computer appointed Mark Long as chief financial officer, bringing an experienced technology finance…

Holtek Semiconductor unveiled its 2026 product roadmap on October 15, focusing on four core areas: smart prote…

TSMC reported about NT$763.1b in Q3 net profit and confirmed that demand for advanced processors is running ah…

Nvidia-backed CoreWeave steadied Thursday after a sharp slump, as investors worried about the debt financing b…

Circlia started a proof-of-concept for TASTE SIGNAL: visitors to Holland Village Cafe FUKUOKA taste cookies an…

Weathernews said on October 15 it implemented its own AI weather-forecasting model, AI-Nowcast, in its Weather…