What happened
Thinking Machines released Inkling 2 Small, a 594B-total / 17B-active multimodal MoE, available now on Tinker. It hit 31 on the Artificial Analysis Intelligence Index, up 18 from Inkling Small, with Apache 2.0 weights promised next week after external safety testing.
Why it matters
The 18-point jump over its predecessor suggests a materially more capable model at a small active-parameter footprint. But the benchmark gains and any open-weights positioning remain conditional on the Apache 2.0 release landing next week.
What to watch
Apache 2.0 weights are promised next week, once external safety testing is fully complete.
WHO IT HITSEnterprise AI teams evaluating open-weight models for fine-tuning and inference will have a new option to test on Tinker today, with the full Apache 2.0 weights expected next week. The token-heavy inference — about 150K output tokens per Index task — may matter for teams budgeting per-task costs.
Summaries like this, every morning.
Inkling 2 Small arrives as a 594B-total / 17B-active multimodal MoE, roughly twice the parameters of Inkling Small, and is positioned as a step up in capability for the Tinker ecosystem. The model was pretrained in 68 hours on GB300s, with the main pretraining phase running 8.4T tokens natively in NVFP4. Post-training involved 17M rollouts over 9 days, and an engineer highlighted long-horizon capabilities bootstrapped from near-zero pass rates.
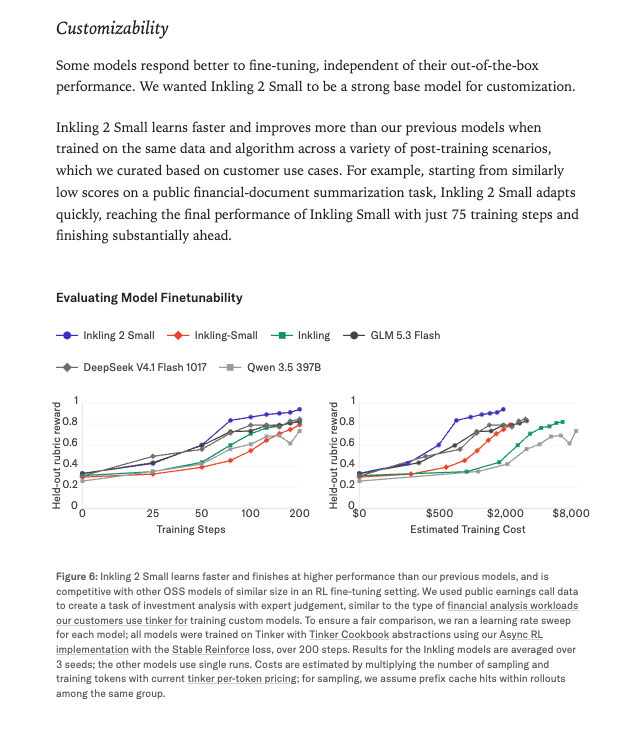
Customizability is framed as a design target, with Soumith Chintala saying it is 'probably one of the only model programs in the industry with a launch blocking eval around customizability.' He adds that for a fixed data and dollar budget, it fine-tunes better than alternatives. The model is token-heavy at inference — about 150K output tokens per Index task, compared with roughly 37K for Inkling Small — though low per-token prices keep cost per task at $1.18 versus $0.20 for its predecessor.
Vals ranks it #7 among open-weight models globally, noting strength in finance and legal but considerable ground to make up on technical agentic tasks. The open-weights claims remain conditional: Apache 2.0 weights are promised next week, and Artificial Analysis lists the model as proprietary at launch with an unconfirmed weights date.
Pick your industry and the AI tools you use, and get news related to your work every day.
Free · 30 seconds with Google · unsubscribe anytimeWhat is AIToday? →
Ask AI anything about this article. The AI reads this article, earlier AIToday articles, and Wikipedia, and cites its sources. Q&As are published on this page for other readers too.
Carnot AI Inc, which develops and provides the enterprise AI platform Jinba, was accepted into NVIDIA Inceptio…
Anthropic launched Personal Finance as a beta in the US for Pro, Max, and Ultra subscribers, giving Claude rea…
On November 5, 2026, Nvidia closed down 9.26% at $181.60, AMD lost 17.26%, and the Philadelphia Semiconductor…
The S&P 500 fell 4.3% and the Nasdaq Composite 5.5% on Nov
newmo and KDDI said on November 6 they signed a capital tie-up for autonomous taxis, with KDDI Smart Mobility…
The Nasdaq 100 fell 6.4% on Thursday, a record $2.3 trillion of market cap wiped out, while the Philadelphia s…


